Smart City Platforms: Designing for a Federation, Not a Product
Why the hard problem in city data is departmental ownership rather than throughput, and what to do about coordinate systems, spatial joins, privacy, and data quality you can defend.
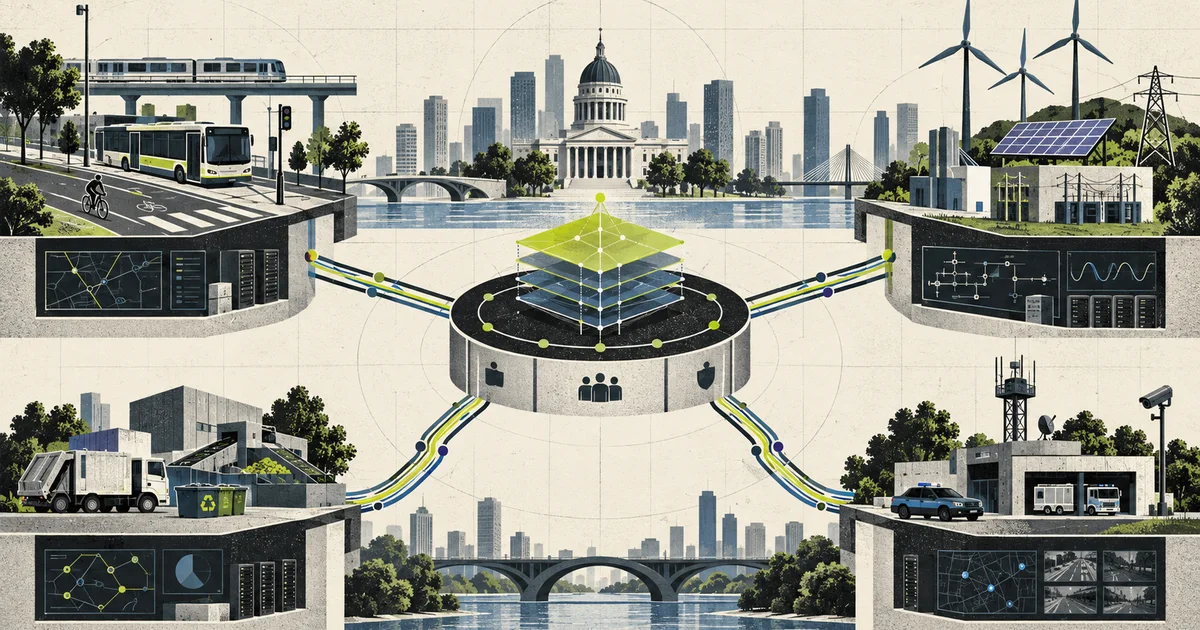
Every smart city programme starts with a technical problem. None of them stay technical problems.
A city is not a system. It is a federation of systems, each owned by a different department, each bought from a different vendor, each governed by a different policy, and each replaced when a different election decides to replace it. The hard engineering question is rarely throughput. It is what happens to your data model in four years when the transport department that owned your traffic feed is dissolved into a new one.
This article is about building for that.
The scale, for context
Assume a city of roughly 800,000 people with five million sensors and devices reporting across traffic, environment, waste, water, lighting, parking, transit, and public safety.
5,000,000 devices, averaging one report per minute
                                        = 83,333 messages/sec
peak, say five times that                = ~417,000 messages/sec

83,333/sec x 86,400 sec                 = 7.2 billion messages/day
at ~120 bytes per message               = 864 GB/day, roughly 315 TB/year
Three hundred and fifteen terabytes a year is serious but unremarkable. A managed Kafka cluster handles it, and a time series store holds it after downsampling.
None of that is the difficult part. The rest of this article is about the difficult part.
Departments are the architecture
The single most consequential decision is how the platform relates to departmental systems, and there are really only three options.
Build everything centrally. One platform replaces every departmental system. This produces a monolith with a procurement process measured in years, no political owner for any individual domain, and a single failure that every department notices at once. It also fails permanently the first time a department head who did not want it leaves.
Federate, do not replace. The platform ingests from existing departmental systems, normalises, and provides cross-domain views. No department loses its system.
Build nothing shared. Each department does its own thing. This is the default outcome when coordination fails, and it is what usually happens without a deliberate decision.
Federation is almost always the right answer, and it has one hard requirement that teams consistently underestimate:
You are a guest in someone else’s system. Their maintenance window is when your data stops arriving. Their vendor’s API changes without notice. Their budget ends and their contract lapses. Their data has quality problems you cannot fix and must not silently correct.
Design for that from the beginning:
per domain:
    connector        -> normalises to the common model
    quarantine       -> stores what could not be parsed, with a reason
    freshness        -> the platform knows when it last heard from each source
    provenance       -> every record carries its source system and transform
That last one is the most valuable and the most frequently skipped. A record that says “air quality 42 µg/m³ on Road A” is nearly useless in a dispute. A record that says “air quality 42 µg/m³ on Road A, from department source aq-v3, transformed by connector version 2.4 at 14:32, original value 41.8, rounded for display” can be defended.
The same place is the hard part
This is the data modelling problem that consumes more schedule than throughput ever will, and it is worth spelling out because it is not intuitive.
Two air quality sensors, one from the environment department and one from a contractor, are 30 metres apart. Are they the same place?
For a heat map over a city, almost certainly yes. For a regulatory air quality report, absolutely not, because they have different calibration histories, different heights above the road, and different siting standards.
Then add:
- Coordinate reference systems. One department publishes latitude and longitude in WGS84. Another publishes a national grid eastings and northings. A third publishes UTM zone coordinates. Feeding all three into one table as if they were the same thing produces errors of hundreds of metres, and the error is silent.
- Cadastre and address models. A traffic camera is located by street segment, a waste bin by a route and a stop number, a water meter by a service address, a lamp by a column reference. None of these are coordinates and all of them need to become coordinates.
- Elevation. A traffic sensor on an overpass and one underneath it are a few metres apart horizontally and several metres apart vertically. Whether that matters depends on the question.
So the platform needs an explicit place model rather than a latitude and longitude column.
place
    place_id          stable internal identity
    crs               which coordinate reference system the source used
    geometry          normalised geometry in the platform's own CRS
    altitude_m
    address_ref       pointer to the address registry
    segment_ref       pointer to the road or route network
    cell              derived hierarchical grid cell
    provenance        how this place was derived
Normalise early, into one reference system, and record the source system. The alternative is a query-time conversion on every spatial join, which is where a hundred-metre error becomes very hard to find.
Put everything on a grid at ingest
Almost every cross-domain question in a city is a question about an area.
- Air quality by neighbourhood
- Traffic incidents by district
- Flooding by ward
- Noise complaints by postcode
If your sensors have no common spatial index, every one of those questions is a spatial join at query time, against heterogeneous coordinates, on a dataset nobody wants to scan.
Resolve it once, at ingest, to a hierarchical grid. Uber’s H3 is the usual choice and the resolution choice is a genuine trade-off:
H3 resolution 7   ~5.2 km2 per cell      district or borough level
H3 resolution 8   ~0.75 km2 per cell     neighbourhood level
H3 resolution 9   ~0.105 km2 per cell    city block level
H3 resolution 10  ~0.015 km2 per cell    sub-block
Storing the cell for a sensor alongside its coordinates, at one or two resolutions, turns a spatial join into an equality filter.
index on (h3_res8, recorded_at)SELECT h3_res8, avg(value)
FROM sensor_readings
WHERE h3_res8 = ANY (:cells) AND recorded_at >= :since
GROUP BY h3_res8;The catch is that a single grid cannot serve both a borough rollup and a block-level question without re-resolving. The practical answer is to store a parent cell alongside the child, so a rollup is a sum over children and a drill-down is a lookup, and neither has to re-derive anything.
For genuinely relational spatial work, PostGIS is the right tool, with one decision that matters more than the rest:
geometry    -> planar, fast, wrong for distance on the earth
geography   -> spheroidal, correct, slower
A “find all sensors within 500 metres” query written against geometry on city-scale coordinates will give you answers that are wrong by a few percent, which is a bug that survives testing because the results look plausible.
Telemetry and events, again, but harder
The three-store split from the industrial platform applies, with an extra wrinkle: cities generate events that are legal and financial in a way that factory events are not.
Telemetry is environmental and traffic readings. High volume, time-ranged, downsampled aggressively. Air quality at 1 Hz is pointless; at 5 to 15 minutes it is the regulatory standard for a reason.
Events are the ones that matter. Traffic collisions, flood reports, air quality exceedances, pothole reports, emergency dispatches, waste collection completion, streetlight faults. Low volume, high value, immutable, retained for years, and often the subject of a public records request.
Assets are the physical things: lamps, bins, signals, sensors, chargers, trees, bridges. Slow-changing, hierarchical, with their own maintenance history.
The wrinkle is that city events tend to be asserted rather than measured, and they conflict. A collision reported by a camera, a call to a hotline, and a police dispatch are three records of one event, created by three systems, with three times and three locations. They have to be correlated into one incident, and the correlation is a judgement, not a computation.
That means the platform needs a place for human adjudication, because a human will be asked to confirm the merge, and the system should record who did it.
Emergency response is a different product
Everything above optimises for throughput and analytical queries. Emergency response has a completely different requirement, and it is the one that gets the least design attention until the first incident.
The latency budget is not a throughput number.
911 call -> dispatch decision         seconds, dominated by human workflow
traffic incident detected -> operator seconds, 5 to 10 is fine
flood level change -> public warning  minutes
air quality exceedance -> publication  minutes to an hour
A thirty-second-old traffic alert is worthless and a ten-minute-old air quality figure is normal. Designing one pipeline latency budget for all of it produces something that is too slow for emergencies and too fast to be useful analytically.
The other thing about emergencies is that data quality is at its worst and system usage is at its most unprecedented. People will use the interface during the incident who have never used it. A feed nobody has looked at in eight months will be read by a duty officer at three in the morning.
The design consequence is a deliberate degraded mode:
nominal:      full dashboard, live map, historical context, filters
degraded:     last known state per asset, explicit staleness timestamps
              no historical queries
              pre-canned views only
offline:      a printed or locally-served runbook
And the staleness must be explicit on every element. A map showing a sensor’s last known state without saying how old it is will be read as current by someone under pressure. That is the failure that turns a technical problem into an incident.
Privacy is about aggregation
City sensing creates real privacy exposure, and it is not where people expect.
A single air quality sensor is not personal data. A smart meter reporting consumption every fifteen minutes at a fixed residential address is a very good behavioural profile: occupancy patterns, absence, approximate appliance use, and a strong signal about who is home.
The general pattern: individually harmless measurements become personal data when aggregated over time and linked to a fixed place. The controls that matter are therefore about aggregation and linkage, not about the sensor.
Reasonable controls:
- Minimum cohort size. Suppress or coarsen any output derived from fewer than a threshold number of contributors, commonly ten or more. Below that, a single household’s consumption is identifiable even if the data is nominally aggregate.
- Spatial coarsening for small populations. A sensor serving a rural ward serves a handful of people; publishing at full resolution is publishing about individuals.
- Time coarsening. Finer granularity is more identifying than coarser granularity, so short windows need stronger controls than long ones.
- Retention limits. Fifteen-minute residential data does not need to be kept for fifteen years, and deleting it is the most effective privacy control available.
- Purpose limitation. Data collected for traffic management is not automatically available for enforcement, and the platform should make that a technical constraint rather than a policy document.
None of this is exotic, and all of it needs to be designed in rather than bolted on, because removing a published dataset retrospectively is not possible once someone has downloaded it.
Data quality is a user-facing feature
A city platform publishes to the public, which changes the stakes on quality completely. A private dashboard with a wrong number is a bug. A public dashboard with a wrong number is a loss of trust that a platform does not recover from, because the audience remembers the wrong number.
Three things a public surface should always do:
Show provenance and freshness. Not in a tooltip nobody opens. On the same visual level as the number.
Show data quality alongside data. Coverage, the fraction of sensors reporting in the window, and known gaps. A heat map that says “87% of sensors reporting” is more useful than a confident map that is quietly missing a district because its gateway is down.
Refuse to show a number you cannot stand behind. If a source has not reported for twenty minutes, the dashboard should not display its last value without a staleness marker. An empty cell and a stale cell are different facts and the interface has to distinguish them.
This also has an internal benefit, because it turns data quality from a department’s problem into a visible operational metric that the platform team is accountable for.
per source:
    last_message_at
    messages_expected vs messages_received
    parse failure rate
    fields missing
    values outside plausible range
A source that quietly stops reporting is the most common real failure in a federated city platform, and it is invisible unless freshness is a first-class signal with an alert on it.
Surviving a change of administration
This is the part that most architecture documents omit and most programmes discover painfully.
A platform outlives the political cycle that commissioned it. In four years, a new administration will have different priorities, a different vendor for one domain, and a budget that protects traffic and not environment. Your data model has to absorb that without a rewrite.
Three decisions that make this survivable:
Never hard-code a domain into the platform. Domains are configuration, with a schema registry, an owner, and a lifecycle state. A department being reorganised is a configuration change, not a refactoring.
Keep vendor-specific logic in connectors. Every departmental system has quirks. Those belong in a connector, versioned and testable, not in the shared model where they contaminate everything.
Make provenance permanent and never destructive. When a department switches vendor, the old data must remain queryable and attributable, because a trend that spans a vendor change is exactly the kind of thing an audit will ask about. A platform that drops history at a supplier boundary cannot produce one.
bad:   one "traffic_speed" series, silently changing meaning at the vendor swap
good:  "traffic_speed" + source_system + connector_version on every record
That one property is the difference between a platform that can be handed to a new owner and one that has to be rebuilt.
Failure stories worth testing
A department’s system is down for maintenance
Confirm the platform degrades to stale-with-timestamps rather than showing nothing or, worse, fresh data. Then confirm the source is marked unavailable on every surface that uses it.
Two sensors from different departments turn out to be the same object
Confirm the place model can merge them without losing either source’s provenance, and that historical queries still resolve to one place.
Someone publishes a figure in a national grid as if it were WGS84
This happens. Confirm the platform can detect coordinate systems outside a known bounding box, because a lat/lon of 530,000 is obviously wrong and a UTM easting read as a longitude is not.
An emergency happens and the duty officer opens the map for the first time
Have someone who has never seen the interface use it during a drill. Everything they need has to be on the first screen.
A privacy threshold is breached by a small ward
Confirm coarsening happens before publication, not after a complaint.
A new vendor takes over one domain
Confirm the switchover is a new connector and a new source_system value, with no migration of the shared model.
Flooding takes out a district’s comms
Confirm assets in the affected area go to a stale state that is visibly stale, and that the runbook is reachable without the platform.
A number on a public dashboard is wrong
Confirm you can identify which source and connector version produced it, and trace the transformation. If you cannot, you have a problem that is not technical.
A production-ready architecture
  [ departmental systems ]   traffic, air, waste, water, lighting, transit
        |  vendor APIs, polling, file drops, MQTT
        v
  +-------------------------------------------------------+
  | Connector layer (per domain)                            |
  |   parse -> normalise CRS -> resolve place -> tag source |
  |   versioned, quarantined on failure, freshness tracked |
  +---------------------------+----------------------------+
                              | canonical events
                              v
     +-----------+   +--------+--------+   +---------------+
     | Telemetry |   | Event store     |   | Asset registry|
     | time      |   | immutable,      |   | hierarchy,    |
     | series    |   | long retention  |   | ownership,    |
     +-----+-----+   +--------+--------+   +-------+-------+
           |                    |                    |
           +--------------------+--------------------+
                              v
              +-------------------------------+
              | Spatial layer                 |
              |  H3 grid at ingest, PostGIS   |
              |  place model, address registry|
              +---------------+---------------+
                              v
     +----------------------+--------------------+
     |                      |                    |
+-----v------+     +--------v-------+   +--------v---------+
| Analytics  |     | Public portals  |   | Emergency       |
| dashboards |     | and open data   |   | console,        |
| reporting  |     | with provenance |   | degraded mode   |
+-------------+     +----------------+   +------------------+

  Privacy layer: cohort thresholds, spatial and temporal coarsening
A sensible delivery checklist:
- Map the departments, the owners, the vendors, and the procurement cycles before designing the data model.
- Build connectors, not replacements, and treat every source as a guest you do not control.
- Put provenance and connector version on every record, permanently.
- Normalise coordinate reference systems at ingest and record the source system.
- Resolve a place model with a stable identity, and store an H3 cell at one or two resolutions.
- Choose
geographyovergeometryfor any distance or containment question at city scale. - Keep telemetry, events, and assets in three stores with three retention policies.
- Build a deliberate degraded mode for emergency use, with staleness on every element.
- Design aggregation-based privacy controls in, with cohort thresholds and time coarsening.
- Publish provenance and coverage next to every public number, and show nothing you cannot source.
- Make domains configuration rather than code, so a reorganisation is a config change.
- Alert on source freshness, because a silently dead feed is the most common real failure.
Common mistakes
| Mistake | What actually happens | Better decision |
|---|---|---|
| Replacing departmental systems | The programme is dead at the first change of administration | Federate and normalise |
| Assuming the source is reliable | A dead feed looks like a quiet city | Track freshness per source and alert |
| One lat/lon column for everything | Mixed reference systems produce silent hundreds-of-metre errors | Normalise at ingest, record the source CRS |
| Spatial joins at query time | Every cross-domain question is slow and hard to reason about | Store an H3 cell at ingest |
geometry for distance at city scale |
Distances are wrong by a few percent and look plausible | Use geography for distance and containment |
| Telemetry and events in one store | High-value incident records become unqueryable | Separate stores, separate retention |
| Merging conflicting event sources in code | The merge is a judgement presented as a computation | Route it to a human and record who decided |
| No degraded mode for emergencies | First-time users meet a blank map at three in the morning | Pre-canned views and explicit staleness |
| Silent staleness | An operator reads a twenty-minute-old value as current | Timestamp every element, always |
| No aggregation privacy controls | Fifteen-minute household data is effectively surveillance | Cohort thresholds, spatial and temporal coarsening |
| Publishing without provenance | A wrong number cannot be traced and trust is lost | Source system and connector version on the record |
| Hard-coding domains into the model | A departmental reorganisation becomes a rewrite | Domains as configuration with a schema registry |
| Dropping history at a vendor change | Trends spanning the change cannot be produced | Never destroy provenance or history |
| Treating quality as an internal concern | The public discovers it for you | Show coverage and quality beside the data |
| Optimising one latency target for everything | Too slow for dispatch, too fast to be useful for air quality | Separate latency budgets per domain and per use |
The complete story in one minute
A city platform does not replace anything. It ingests from departmental systems through versioned connectors that parse, normalise the coordinate reference system, resolve a stable place identity, and record the source and connector version on every single record.
Telemetry goes to a time series store with an H3 cell stored alongside the coordinates, so a neighbourhood question is an equality filter rather than a spatial join. Events go to an immutable transactional store, and conflicting reports of the same incident are merged by a human rather than a heuristic. Assets go to a registry that tracks ownership, hierarchy, and maintenance history.
A place model sits underneath, with a stable identity per location, a normalised geometry, and pointers to both the address registry and the road network, because a traffic camera and a waste stop are located in completely different terms and both have to become coordinates.
Analytics and public portals read from those stores through the spatial layer, and every number they show carries its source, its freshness, and its coverage. Emergency users get a separate degraded console with pre-canned views and staleness on every element, because the people using it during an incident are not the people who built it.
Privacy controls coarsen any output derived from too few contributors, and domains live in configuration so that a change of administration is a config change rather than a rewrite.
That is the whole path:
departmental systems -> connectors -> (telemetry | events | assets) -> spatial layer -> surfaces
                              |
                              +-> provenance and freshness on every record
The hard parts were never the throughput. They were building a platform that treats its sources as guests, its geography as a modelling problem, and its own trustworthiness as a product surface.
What this team still owns
A city platform is a federation, not a master database. Preserve source ownership, licence, coordinate reference system, schema version, update cadence, quality flags, and a contact for every dataset. Public aggregates need a documented privacy threshold and suppression rule that is evaluated again after filters, because safe city-wide counts can become identifiable at one block and one hour. Operational screens display freshness and provenance as prominently as the value.
Technical references
Related notes.
EV Charging Platforms: The Meter Is the Product and the Connector Is the Weakness
OCPP, the five-system transaction, demand charges on connected capacity, idle bays, and why public charging reliability is a hardware problem wearing a software costume.
Micromobility Platforms: The Ride Is a Distributed Transaction
The unlock and ride lifecycle, when a ride actually starts, curb economics, battery swap logistics, and why the payment authorisation is the hardest part of a scooter.
Fleet Management Systems: The Platform Is Telematics, the Product Is Exceptions
Hours-of-service compliance, driver behaviour scoring as an employment decision, fuel leakage, and why a fleet system's real value sits in the five percent of cases that are not normal.