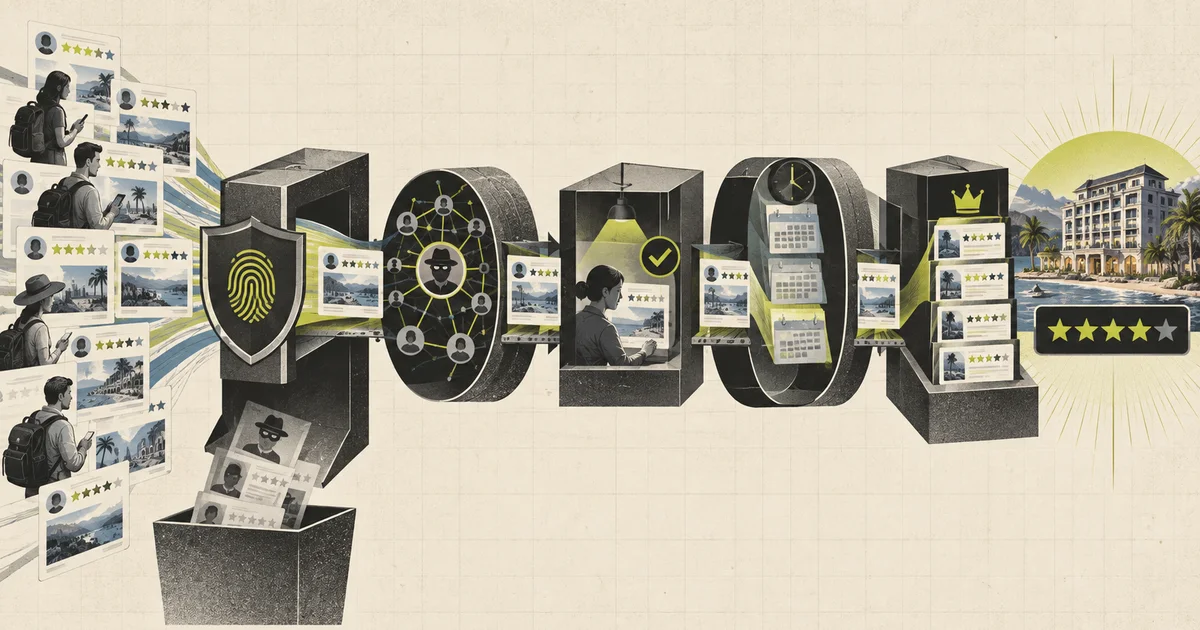
Travel Review Platform: Moderation, Fraud, and the Recency Problem
Running a travel review platform at scale — review eligibility, fraud detection, ranking that resists gaming, and the moderation workflow that makes it trustworthy.
Hi, I’m Rahiyan Safin. I build scalable, event-driven backend platforms with Java, Spring Boot, and C#/.NET. I help teams turn complex enterprise constraints into dependable software.
Fig. 01 A system is only as good as its recovery path.
Long-form engineering notes for readers who care about what happens between the architecture diagram and a running enterprise system.
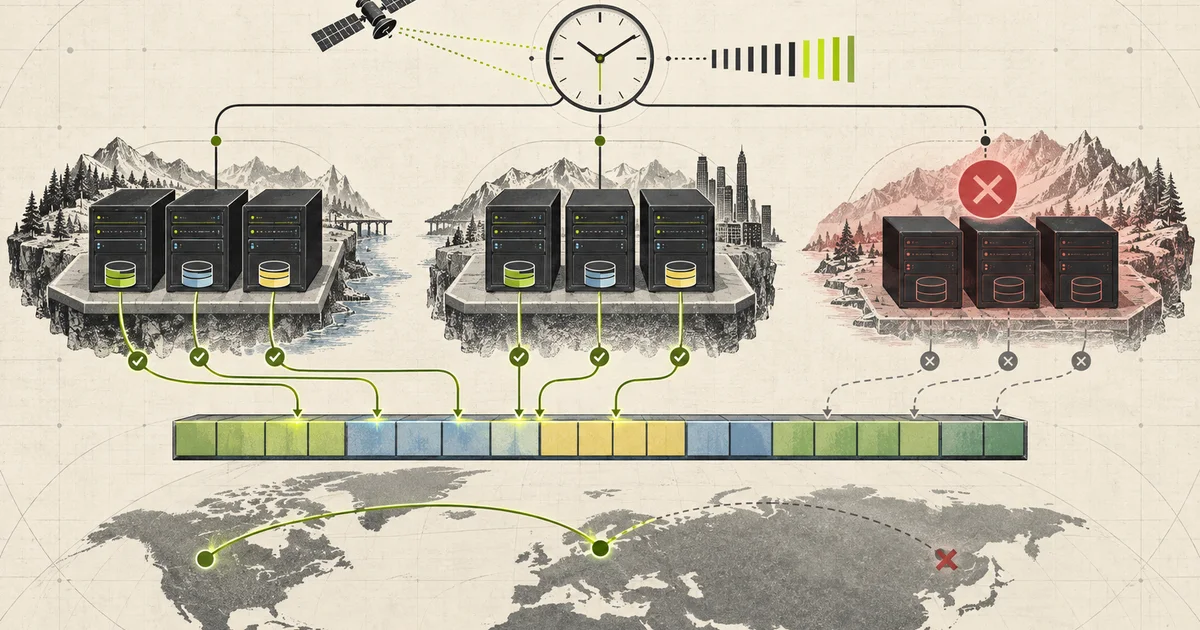
Why a global SQL database is really a problem of agreement and time, how Google solved it with TrueTime, GPS, and atomic clocks, and how CockroachDB reaches a practical design on ordinary infrastructure.
Running a travel review platform at scale — review eligibility, fraud detection, ranking that resists gaming, and the moderation workflow that makes it trustworthy.
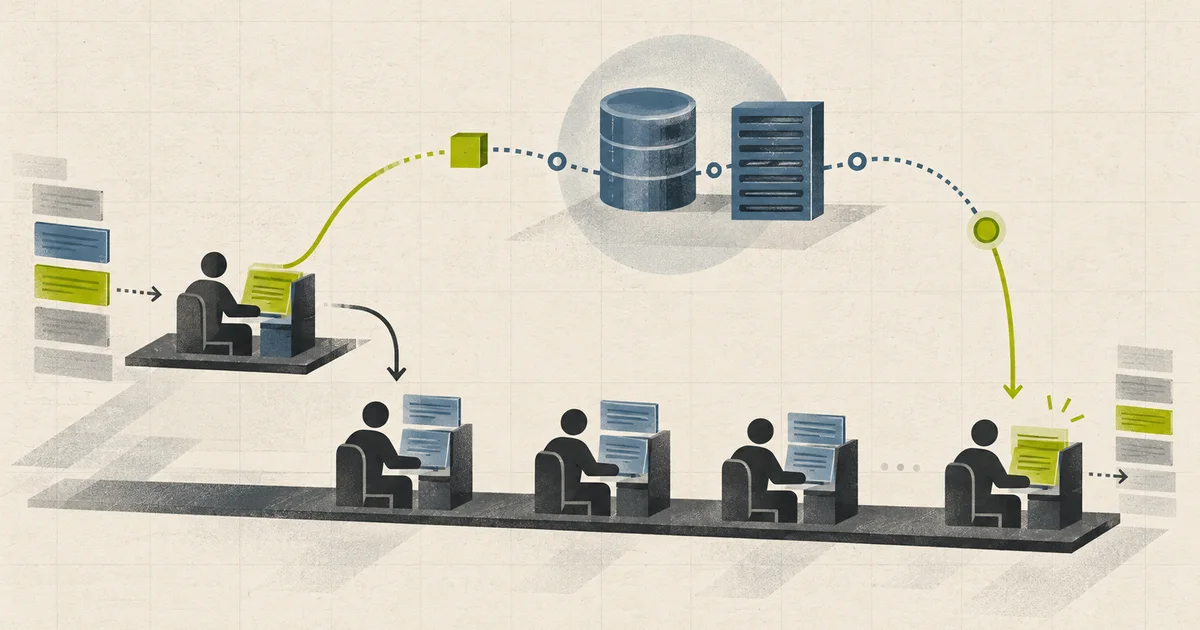
A story-led explanation of Tasks, compiler-generated state machines, continuations, threads, I/O completion, exceptions, cancellation, contexts, and practical async design in .NET.
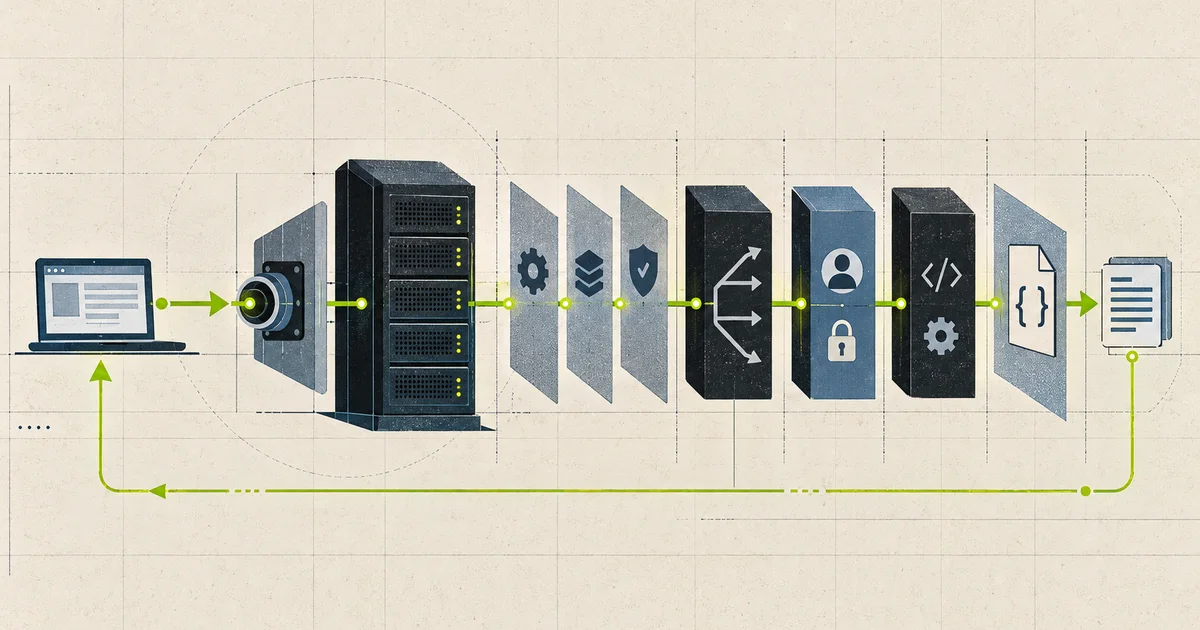
A plain-English walkthrough of how an ASP.NET Core application starts, builds its middleware pipeline, accepts traffic through Kestrel, selects an endpoint, and returns a response.
Search my articles, background, skills, and contribution history in plain English. Every result takes you back to something you can read and verify.
Start each Event Hubs consumer group at an approved position, reconcile with stable event IDs and business sequence numbers, and keep Kafka available until the rollback window closes.
Read the article →Private sessions run for product teams. The companies are under NDA, so each entry gives the problem and the decision rather than the client. Full write-ups are in workshops.
A team could publish but could not reason about what happened after a consumer crashed mid-batch. Rebuilt the failure story around idempotency keys, a poison-message path, and a replay operators had actually rehearsed.
Four brokers, no capacity plan, and a broker upgrade that ate a weekend. Worked through what changes when the platform runs the cluster: compatibility gaps, partition mapping, dual running, cutover, and the rollback nobody had tested.
Two systems that had to agree, maintained by hand, forever. Replaced the nightly job with logical replication into a stream, then spent most of the session on the hard part: schema evolution and what a consumer does when it receives a shape it has never seen.
Built for a team whose services passed load tests and still timed out in production. Read a state machine out loud, traced a continuation onto a thread pool, and found where a request was blocking something that looked asynchronous.
A third-party callback was the only part of the flow nobody owned. Drew the trust boundaries, moved the secret handling, made the audit trail answerable, and scoped what genuinely had to live inside the cardholder data environment.
 Binary Quest
 TAP
 SSW Consulting
 SVT Robotics
 Shine Solutions
 Neolution
 JTL Software
 NovoTX
 Eximia
 SOFTURE
Client work is described at a safe level. No private repositories, confidential metrics, or NDA material are published here.
Dependable enterprise systems feel predictable because their boundaries, failure modes, observability, and recovery paths were designed deliberately.
I am a senior software engineer based in Dhaka with 8+ years of experience across enterprise SaaS, manufacturing, fintech, and healthcare. My core work spans Java/Spring Boot, C#/.NET, event-driven architecture, and cloud platforms.
More about me