Travel Recommendation Engine: Why the Obvious Approach Fails and What Actually Works
Candidate generation, two-stage ranking, exploration, and the feedback loops that turn a travel recommender into a filter bubble.
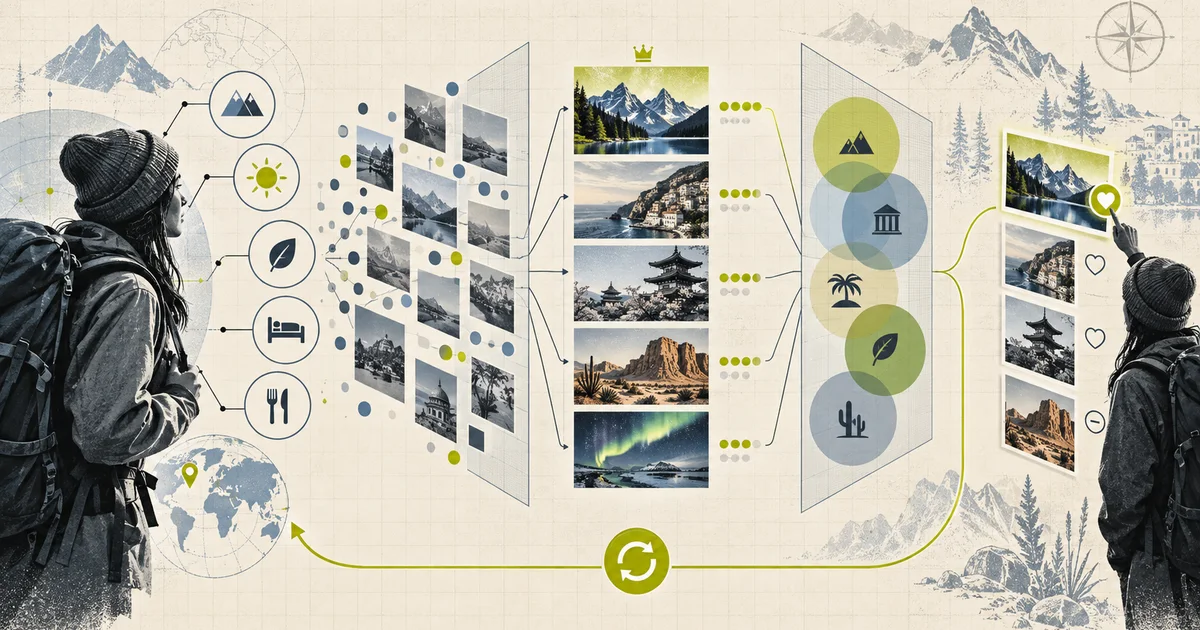
The first version of every travel recommender is the same three lines: index the hotels, run collaborative filtering, return the top ten. It works in a demo with 5,000 hotels and 50,000 users. It does not work in production, and the reasons it fails are structural, not tuning problems.
The scale, and what makes it hard
  a mid-sized travel marketplace
    2 million listings
      - 400,000 hotels
      - 1.2M vacation rentals
      - 380,000 restaurants
      - 25,000 experiences
    8 million users
    40 million booking events
    impressions: billions

  the interaction matrix at 8M x 2M
    density if every user viewed 30 items:
      240M filled cells / 16,000,000,000,000,000
      = 0.0000015%

  candidate generation must go from
    2,000,000 -> ~500 in under 100ms
Two properties of this data shape every design decision.
Extreme sparsity. With 0.0000015% density, collaborative filtering has almost no signal per user. A user with 30 views across 30 different cities is not a preference signal — it is noise. This is why content and context carry most of the weight, and why the best systems use collaborative filtering as one feature among many rather than as the model.
A long-tail catalogue. A small fraction of listings get most of the bookings. The head is well covered by collaborative filtering. The tail — which is most of the catalogue, and much of what makes the marketplace worth browsing — has no interaction history and must be recommended on attributes alone. This is a cold-start problem on the item side, and it is a permanent feature of the business, not a bootstrap phase you pass through.
Two systems, not one
  +----------------------------------------------------------+
  |  STAGE 2: ranking                                        |
  |  order ~500 candidates precisely for this user            |
  |  a learned model, ~20-50ms                              |
  +----------------------------+-----------------------------+
                               |
                               v
  +----------------------------------------------------------+
  |  STAGE 1: candidate generation                           |
  |  2,000,000 -> ~500                                       |
  |  must be fast, cheap, and have high recall               |
  |  ~20-80ms, runs on every request                         |
  +----------------------------------------------------------+

  the rule
    recall@500 of 1.0 matters far more than
    ranking accuracy

    if the perfect answer is not in the
    candidate set, no ranker can find it
Stage 1 is where most engineering effort goes, and it is where most projects underinvest. The metric that matters is recall@k: of the items the user would have engaged with, what fraction is in the candidate set. Recall of 0.9 with a mediocre ranker usually beats recall of 0.7 with a great ranker, because the ranker can only reorder what it receives.
Practical generation sources, run in parallel and merged:
| Source | Why it contributes |
|---|---|
| Recently viewed / booked city | Strongest single signal in travel |
| Similar listings (“you may also like”) | Item-to-item, works on the tail |
| Collaborative neighbours | User-to-user, strong on the head |
| Content and attribute match | The only source for brand-new listings |
| Popular in destination and dates | The cold-start fallback that always works |
| Price and availability band match | Users cluster tightly on price sensitivity |
The merge is a deduplicated union, usually with each source contributing a variable number of slots — a fixed 50 from each source is wrong because source quality varies by user and by context.
What the ranker actually sees
  features, roughly grouped

  user
    - home city, travel history summary
    - average price band actually booked
    - average trip length
    - party size, children, pets
    - loyalty tier, if any

  item
    - category, brand, star rating
    - price, price per night
    - review score, review count
    - amenities
    - distance from city centre
    - property type

  context (the most valuable group)
    - destination
    - dates, and how far away
    - day of week
    - trip occasion: leisure vs business
    - weather at the destination
    - is this a first visit to the city
    - how late in the session it is

  interaction
    - impression count
    - click count
    - click-through rate, impression-weighted
    - last interacted timestamp
    - was this saved / shortlisted
The context group is where a travel recommender earns its keep, and it is consistently underweighted in first attempts. A user who books a 3-star city hotel in a warm destination in March and a 5-star beach resort in July in the same year is not contradictory. They are two trip types. A model without occasion and weather features will average these into mush.
Filtering is a constraint, not a feature
This is the single most common correctness bug in travel recommenders.
  WRONG
    features: price = 180, maxPrice = 150
    model scores candidates
    -> the 145-rated hotel scores highest
    -> the 180 one gets shown
    -> the user notices, loses trust permanently

  RIGHT
    stage 1 filter: price <= 150, rating >= 4.0,
                    2 bedrooms, airport <= 20km
    stage 2 ranks whatever survives
    -> the constraint is not negotiable
    -> the model optimises within it
A user who sets a hard budget and then sees a result above it does not treat it as a ranking error. They treat it as the system not listening, and the session is over. Hard filters go in candidate generation, before any scoring, and the filter set comes directly from the explicit UI controls.
There is a softer middle ground worth knowing: some constraints are preferences with weights (a user who has never booked above $200 but has “budget mode” off) and some are absolute. Learn the distinction from how the user engages — if they repeatedly widen a filter rather than scrolling past results, the filter may be a preference. If they filter and then never widen, it is a hard constraint.
Cold start, and why the first session matters
  no history: 0 views
    1. the user's stated intent
       (destination, dates, party, budget)
    2. destination-level popularity
       for those exact dates
    3. high-review-count listings
       in the user's price band
    4. editorial or algorithmic "best of"
       for the destination

  rule
    never show a brand-new listing with
    2 reviews to a user with no history

    a low-review-count item cannot be
    recommended on quality, only on
    attributes, and the user has no
    reason to trust the attributes yet
The first-session strategy that works: use the destination, not the user. “Best hotels in Lisbon for March under $200 with rating above 4.4” is a good first result set. It is a wide, safe, and immediately useful answer, and it gives the user something to click, which generates the signal that every later recommendation needs.
The listing cold start runs on a different clock. A new property has no reviews, no clicks, and no bookings. Give it a fixed exposure budget — display it in browse and search results at controlled rates, with elevated position when it matches strong contextual criteria, and cap the daily impressions. Track the conversion carefully: early impressions land on an audience that did not ask for this property, so a low early conversion rate is not evidence the property is bad.
Position bias and the click problem
  position 1: 12% CTR
  position 5: 5% CTR
  position 10: 2% CTR

  if you train on raw clicks, the model learns
    "position 1 is good"
  not
    "this item is good"

  and then it ranks position 1 higher
  -> which makes position 1 get more clicks
  -> a self-reinforcing loop with no
     information about quality in it at all
The standard fix is to make clicks position-aware. Train with an inverse propensity weight, where each click is down-weighted by how likely it was to happen at that position regardless of quality. Where you lack propensity data, inject randomised exploration: a small percentage of impressions deliberately randomised across positions, which both generates the propensities and produces an unbiased sample.
The signals worth more than the click, in order:
- Booking. The only signal that reliably reflects satisfaction, and it is sparse and delayed.
- Save to list / shortlist. An explicit statement of intent, cheap for the user, and much more predictive than a click.
- Detail view with dwell time. A click that stays for 40 seconds is a different signal from a click that bounces in 800ms.
- Click. Weak, biased, and used in quantity.
Two-stage ranking beats one big model
  stage A: 500 candidates
    a GBDT (LightGBM / XGBoost) over
    the full feature set
    ~20ms, handles thousands of features
    and non-linear interactions well

  stage B: top 50 from A
    a small neural model (two-tower or
    a shallow DNN) with embeddings
    - user embedding
    - item embedding
    - context embedding
    ~20-30ms
    captures taste that explicit features
    cannot express

  output: final ordering
Why split. The GBDT is strong on structured features, which is most of what stage A has, and it is fast and debuggable — you can print feature importances and see that a misconfigured date feature is dominating. The neural model is strong on learned representations, which is what stage B needs for the candidate set where the decision is genuinely hard. Running the neural model over 500 candidates is 10x the latency for no benefit, because the top 50 it would reorder are all similarly scored by stage A.
The value of the split shows up in operations. When quality regresses, stage A or stage B identifies which half changed. With a single model, you have an unexplained accuracy drop.
Exploration and the filter-bubble problem
  exploitation
    show the user what they clicked before
    -> they click it again
    -> the model confirms the model
    -> no information gained

  a travel recommender that only recommends
  the Lisbon boutique hotel they already
  saved will never introduce them to the
  thing they would have loved
A travel catalogue has enormous long-tail value, and an exploitation-only recommender cannot see any of it. The mechanism that works is constrained exploration: deliberately inject items that are different but defensible — a different neighbourhood, a different property type, a different price band, at the same quality level. The constraint is what makes it safe. Random exploration produces bad results and trains the user to ignore the surface.
The measurement is a genuine tension worth naming: the recommendation system’s short-term click metric will fall when you explore, and the long-term metric that pays for exploration is hard to attribute. The workable practice is to hold out a small exploration cohort permanently, so you have a permanently unbiased read on what the catalogue actually contains and not just what the previous model showed people.
Serving architecture
  OFFLINE, every few hours
    - user profile: recent interactions,
      aggregate preferences, trip history
    - item profile: attributes, quality
      scores, availability calendar summary
    - item embeddings, trained
    - user embeddings, trained
        |
        v
  +----------------------------------------------------------+
  |  CANDIDATE CACHE                                        |
  |  precompute neighbours, "similar to this",             |
  |  "people who stayed here also stayed",                  |
  |  for the top ~50k items users actually browse          |
  |  NOT for 2M items x 8M users                           |
  +----------------------------+-----------------------------+
                               |
  REQUEST
    filter (hard constraints from UI)
        |
        v
  +----------------------------------------------------------+
  |  generation: online sources + cache hits                |
  |  ~500 candidates in <80ms                               |
  +----------------------------+-----------------------------+
                               |
                               v
  +----------------------------------------------------------+
  |  stage A GBDT (20ms) -> stage B NN (25ms)               |
  +----------------------------+-----------------------------+
                               |
                               v
  +----------------------------------------------------------+
  |  post-processing                                          |
  |  - dedupe near-identical listings                       |
  |  - cap results per host / per neighbourhood              |
  |  - enforce inventory and availability                    |
  |  - the deterministic exploration slots                  |
  +----------------------------+-----------------------------+
                               |
                               v
  response + impression logging with full context

  watch: recall@500, CTR by position, booking conversion,
        exploration slot performance, cold-start survival rate
The candidate cache is the single biggest latency lever and it is cheap to build: precompute item-to-item neighbours and user-to-user neighbours for the small set of entities that carry real traffic, since the tail gets recommended through content and popularity instead.
Failure stories worth testing
Set max price to 150 and check the results
No result may exceed 150. This is the filter-integrity test and it is where hand-rolled ranking code usually fails.
Train on raw clicks with no position weighting
Measure CTR by true relevance rank. The model will look better on its own metric and worse in reality, which is the entire point of the test.
Remove the destination from the feature set
Performance collapses. Confirms context dominance and shows you how much of the “personalisation” is actually just “where are they going”.
Show a 2-review listing to a brand-new user as position 1
They bounce. Confirms that low-review-count items need an exposure ramp.
Fill the slots entirely from “recently viewed” similarities
Click-through will not drop. Booking rate will. This is the filter-bubble failure and the metric that detects it is the conversion metric, not the engagement metric.
Compare stage A ranking against the final stage A+B output
Any improvement here is free latency reduction. If the neural model reorders almost nothing, it is not earning its 25ms.
Serve the same destination to a user 40 times in a session
Engagement drops after roughly the fourth rotation. Confirms the need for diversified slots and exploration, not just top-N.
Turn off all exploration for two weeks
The permanently-explored cohort’s booking rate should be higher. That gap is the argument for keeping exploration on.
Duplicate a listing with 90% identical content into the results
Check the dedupe and host-diversity caps. A marketplace that shows eight rooms from one host reads as an ad, and users treat it as one.
Make availability 3 days stale
Confirm sold-out listings are filtered before ranking, not after. Filtering after ranking is how users end up clicking a dead listing.
Give a returning user a completely different first screen than a new user with identical filters
Measure whether the difference helps. It usually does, which means the user’s history is being underused.
Serve results with all candidates from one neighbourhood
Compare against a forced-neighbourhood-diverse set. This is the test for whether “diversity” means anything in your implementation.
A production-ready checklist
- Split generation from ranking and measure recall@k on generation. Optimise the ranker only after recall is high.
- Run multiple generation sources in parallel and merge, with source-specific slot budgets rather than a fixed quota per source.
- Apply hard filters in candidate generation, before any scoring. Never let a model outrank an explicit user constraint.
- Weight the context features heavily: destination, dates, occasion, weather, party composition. That is where travel-specific signal lives.
- Use bookings and saves as primary targets. Treat clicks as a biased, secondary signal and correct for position.
- Inject randomised exploration to obtain unbiased propensities, and keep a permanent exploration cohort.
- Rank the tail on content and popularity; do not attempt collaborative filtering on items with no interaction history.
- Give new listings a capped exposure budget and evaluate them on contextual conversion, not raw early CTR.
- Use a GBDT then a neural model rather than one large model, so failures are attributable and latency is controlled.
- Precompute neighbours for the entities that get real traffic, and serve the long tail from content and popularity.
- Enforce diversity in the post-processing stage: dedupe, cap per host, cap per neighbourhood.
- Log the full context with every impression, or the training data will be unrecoverable later.
- Track conversion as the primary metric alongside CTR, because exploration and diversity always look like a CTR loss.
- Keep a holdout group to measure what the catalogue truly contains, independent of what past models recommended.
- Version the features. A regression traced to a feature change is minutes of work; an unversioned model is days.
Common mistakes
| Mistake | What actually happens | Better decision |
|---|---|---|
| Collaborative filtering as the model | Nothing to learn from at 0.0000015% density | Content, context, and popularity carry it |
| One stage over 2M items | Unaffordable latency, no recall measurement | Generate then rank, and measure recall |
| Filters applied as features | The model violates them and trust is gone | Filter in generation, before scoring |
| Training on raw clicks | Learns position, not quality | Propensity weights, plus exploration |
| Ignoring context | Averages a business trip with a family holiday | Weight occasion, weather, dates heavily |
| Recommending low-review listings to new users | The user has no basis to trust them | Exposure ramp, high-review items for cold users |
| Top-N from one source | Filter bubble, no long-tail discovery | Multiple sources, diversity caps, exploration |
| Exploiting only | Never surfaces the long tail | Constrained exploration, defensible alternatives |
| One large neural model | Latency cost, unattributable regressions | GBDT then neural, both cheap to debug |
| No dedupe or host caps | Reads as an advertisement | Post-processing diversity |
| Availability filtered after ranking | Users click dead listings | Filter availability before scoring |
| Judging by CTR alone | Exploration looks like a loss always | Conversion and long-term cohorts |
| No impression context logged | Training data is unrecoverable | Log the full context per impression |
| Same first screen for everyone | Wasteful, and worse for new users | Rank per stage of user maturity |
| Optimising only for the head | Most of the catalogue is unreachable | Content path for the tail |
| Forgetting booking lag | Attribution lands on the wrong trip | Delayed-conversion-aware training |
| Unversioned features | A quality drop with no explanation | Version features with the model |
The complete story in one minute
A travel recommender is two systems. Candidate generation turns two million listings into five hundred, and its recall is the number that matters — a perfect ranker over a set that excludes the right answer is still wrong. Generation has to be fast, cheap, and cover the long tail, and the honest assessment is that most of the value is not collaborative filtering. At 0.0000015% interaction density, content and context do the work, and collaborative filtering is one feature among many. The context features are the ones people skip: occasion, weather, trip length, party composition. A user booking a 3-star city hotel in March and a 5-star beach resort in July is not contradictory, they are two trip types.
Hard filters go in generation, never as features. A user who sets a $150 ceiling and sees a $180 result has learned the system is not listening, and that is unrecoverable. The signals, ranked: booking, then save-to-list, then detail view with dwell, then click — because clicks are position-biased, so train with propensity weights and inject randomised exploration to get unbiased data and surface the long tail at the same time. A pure exploitation recommender will never show anyone the listing they would have loved, and that catalogue depth is what the marketplace is selling.
Two-stage ranking — a GBDT over the 500, then a small neural model over the top 50 — because the GBDT handles thousands of structured features fast and debuggable, and the neural model is needed only where the decision is hard. The operational benefit is attributability: when quality regresses, you know which half changed. Cold start is solved differently on each side: new users get destination-level answers, which are wide and safe and generate the first signal, while new listings get a capped exposure budget evaluated on contextual conversion, because early impressions land on an audience that did not ask for that property.
Serve it with a neighbour cache for the entities that get real traffic, content and popularity for the tail, post-processing dedupe and host caps so the page does not read as an ad, and a permanently held-out exploration cohort. Measure conversion, not click-through, because exploration and diversity will always look like a CTR loss and the only way to defend them is a number that shows what they are worth.
generate wide, measure recall, filter before ranking
context features over collaborative filtering
propensity-weighted clicks plus real exploration
GBDT then neural, cold users by destination, cold items by exposure ramp
conversion as the metric, diversity enforced in post-processing
The hard part was never scoring hotels. It was knowing which two hundred hotels to score, and being honest about the fact that a click at position one is mostly a statement about position.
What this team still owns
Log the candidate set, eligibility filters, feature/model versions, position, exploration policy, and outcome so ranking changes can be evaluated without pretending displayed items were random. Hard constraints—dates, occupancy, legal availability, accessibility requested by the user—run before scoring. Exploration has a quality floor and an exposure budget, and its long-term effects are measured by booking, cancellation, repeat use, supplier concentration, and destination coverage rather than CTR alone.
Technical references
Related notes.
Accommodation Marketplace: Two Sides of a Transaction That Never Meet
Running a two-sided accommodation marketplace — supply onboarding, ranking that serves both sides, payments in a regulated flow, and the disputes problem.
Flight Search System: Caching by Degradation, Not by Answer
Flight search at scale — GDS and aggregator fan-out, result caches that age gracefully, and the itinerary-combinatorics problem that makes searching hard.
Travel Itinerary Planner: Constraint Search Where the User Is the Optimiser
Multi-day itineraries as constraint satisfaction, with travel time, opening hours, reservations, and the user's own trade-offs made explicit.