Unused Indexes: The Planner Is Reading Statistics You Forgot to Refresh
Sargability, stale statistics, the leftmost prefix rule, correlated columns, and the cost settings that make a planner reject an index it should have chosen.
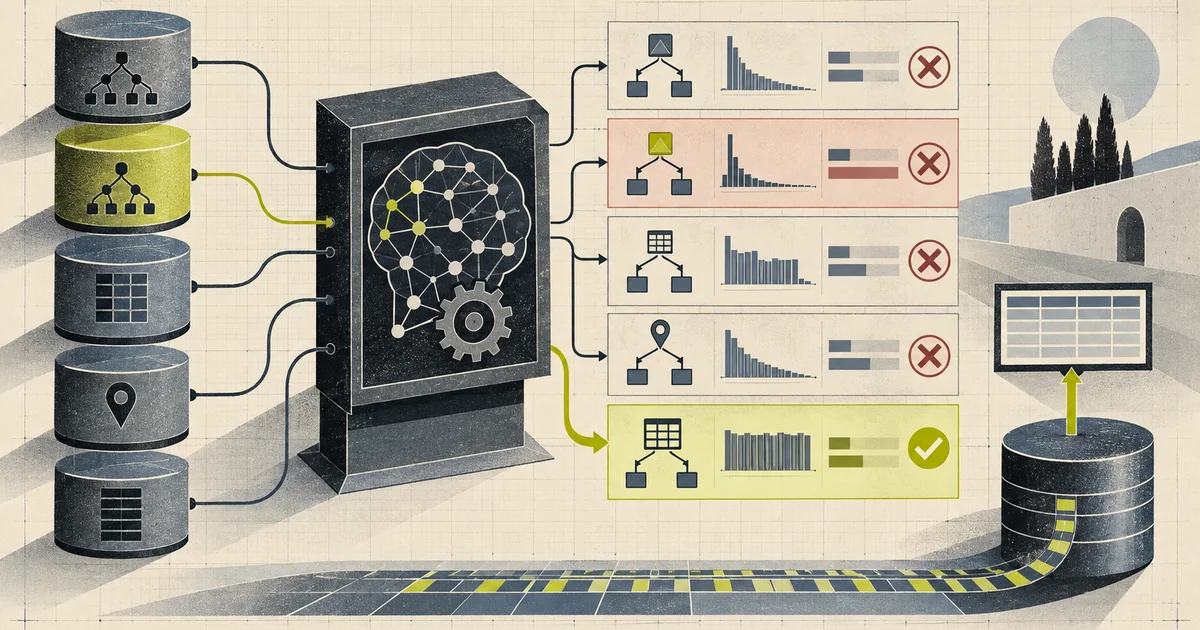
The index exists. The query is selective. EXPLAIN returns Seq Scan on a table with fifty million rows, and the reasonable conclusion is that the planner is broken.
More often the planner is correct, and the thing that is broken is the query. Occasionally it is neither, and the real fault is a statistics target that was last sampled before the data changed shape.
Both of those are worth telling apart, because the fix is different and guessing wastes an afternoon.
It is also worth separating the index you built from the index that earns its write amplification, since an index the planner refuses only pays for itself on the writes it forces. See covering indexes and index-only scans for the case where the planner is right and the index is still wrong, because it does not contain the column you filter on, and UUID primary keys and index fragmentation for the case where a correct-looking index is large and slow because its keys arrived in random order.
The planner is doing arithmetic, not asking what you meant
An index is only worth using if it cuts the number of rows read by more than the cost of finding it. Postgres estimates the number of rows a predicate matches, multiplies that by the cost of reading one row sequentially, and compares it against the cost of walking the index and then fetching rows one at a time from the heap.
The number that decides it is not a preference. It is arithmetic on two estimates, and both estimates come from statistics.
cost of a sequential scan   = pages_in_table  x  seq_page_cost
cost of an index scan       = index_pages    x  random_page_cost
                             + matched_rows  x  cpu_tuple_cost
The default random_page_cost is 4.0 and seq_page_cost is 1.0. These are relative planning units, not a claim that uncached random storage latency is exactly four times sequential latency; the default also assumes many indexed reads are cached. SSDs, network storage, and a memory-resident working set can justify different ratios, but only after measurement across the query mix.
This is why lowering random_page_cost is such a popular fix and such a bad one. It does not make the index better. It changes the exchange rate so that indexes look better, and it does that to every query in the database including the ones that were correctly choosing a sequential scan.
Sargability: check this first
A predicate is sargable when the database can use an index to reduce the rows it must examine. The most common way to lose that is to apply a function to the column.
-- not sargable: created_at is wrapped, so no index can be entered
SELECT * FROM orders WHERE date(created_at) = '2026-08-05';

-- sargable: the column is compared directly
SELECT * FROM orders WHERE created_at >= '2026-08-05'
                          AND created_at <  '2026-08-06';
The second query is not just faster, it is also correct in a way the first is not. Wrapping a timestamp column in date() throws away the time component, so the predicate matches every order in the whole day rather than the one second you meant. The half-open range is both sargable and honest.
Column-side type conversion creates a similar problem, but PostgreSQL does not generally invent a cast between unrelated parameter and column types. A text = integer comparison normally fails with operator does not exist; ORMs and hand-written SQL more often make the query non-indexable by explicitly casting the indexed column.
-- valid SQL, but a normal text index cannot satisfy the bigint expression
SELECT * FROM accounts WHERE external_ref::bigint = 88213;

-- bind the parameter as text: type-correct and indexable
SELECT * FROM accounts WHERE external_ref = '88213';
In .NET this is a contract problem before it is a planner problem. Bind a text identifier as text and let a mismatched parameter fail during testing. Do not repair the mismatch by adding a cast around the column in production SQL. If numeric comparison is genuinely required, store a validated numeric representation or create a deliberately chosen immutable expression index.
The other ways to lose sargability:
LIKE '%widget'— a leading wildcard has no fixed prefix to search from.LIKE 'widget%'is fine,LIKE '%widget'is a scan.ORacross two different columns —WHERE a = 1 OR b = 2can use a bitmap of two indexes in Postgres, but only if both branches are individually sargable and the planner decides it is worth the two scans.!=and<>— rarely selective, so the planner is usually right to ignore the index. If 80% of your table hasstatus <> 'done', the index is not an optimisation, it is a way to make the database read a different part of the same data.- Comparing two columns from different tables in a way that requires a join for every row.
- A collation mismatch, where the index was built with one collation and the query specifies another.
The leftmost prefix rule
A composite index on (tenant_id, created_at) is sorted by tenant_id first and by created_at within each tenant_id. The entries for a single tenant_id are contiguous. The entries for a created_at value are scattered across every tenant.
 (tenant_id, created_at)

 tenant 1    t1  2026-01-01
             t1  2026-03-14
 tenant 2    t2  2025-11-02
             t2  2026-02-28
 tenant 3    t3  2026-01-19
             t3  2026-04-01
WHERE tenant_id = 2 can seek directly. Traditionally, WHERE created_at > '2026-03-01' could not use the trailing key as an efficient leading search and often required a full index or table scan.
The version qualification now matters. PostgreSQL 18 added B-tree skip scan, which can internally repeat searches for values of a missing leading column when the planner estimates that doing so is cheaper. It is most useful when the leading column has few distinct values; it does not make arbitrary trailing-column queries free or turn every composite index into a replacement for a correctly ordered one.
The durable rule is that the index is sorted by the first column, then the second. Leading equality constraints plus a constraint on the first non-equality column provide the most reliable narrowing. Later columns can still be checked in the index, and current PostgreSQL may choose skip scan, but neither property guarantees that fewer index entries are read.
The practical mistake is building indexes for the individual filters and assuming the composite one covers them. WHERE tenant_id = ? and WHERE created_at > ? are two different leading columns and need two different indexes if both are hot. A composite index where created_at is the second column does not serve the second query, and an index on (created_at) alone is usually the right answer for a time-range report across all tenants.
Stale statistics and the sampling lie
Postgres samples rows to build a histogram and a most-common-values list, and it does that on a schedule driven by autovacuum. Between samples, the planner works from a picture of the table that was true at some point in the past.
This matters enormously when the distribution is skewed, which is the normal case for a status column or a plan tier.
-- what the planner believes
SELECT attname, n_distinct, most_common_vals, most_common_freqs
FROM pg_stats WHERE tablename = 'orders';

-- how the data actually looks now
SELECT status, count(*) FROM orders GROUP BY status ORDER BY 2 DESC;
When 0.4% of rows are status = 'pending' and the histogram was built when that was 12%, the planner estimates roughly thirty times too many rows. A plan that should read 200,000 rows looks like it reads 6,000,000, and a sequential scan wins the comparison. The index is not being rejected because it is bad. It is being rejected because the arithmetic was performed on the wrong number.
This is also why the problem looks intermittent. A table that is steadily growing in a stable shape keeps roughly the right statistics. A table that crossed a threshold, or one where a campaign sent a million rows into a new state, drifts out of shape between samples and behaves badly until the next ANALYZE.
Two settings are worth knowing:
-- the threshold that triggers a statistics-only pass, as a fraction of the table
ALTER TABLE orders ALTER COLUMN status SET (n_distinct = 200);
ALTER TABLE orders SET (autovacuum_analyze_scale_factor = 0.02);
The default scale factor is a tenth of the table, so a table with a million rows does not get re-analysed until a hundred thousand have changed. On a table that is churning a large fraction of its rows, that is far too lazy, and lowering the scale factor to something like 0.02 is usually the actual fix.
ANALYZE orders; by hand is fine, but it is a repair and not a design. If the same table drifts every week, the schedule is wrong.
Extended statistics, for when columns are related
The planner assumes columns are independent when it multiplies their selectivity estimates together. That assumption is the default and it is frequently wrong.
-- a row where country = 'BD' almost always has city = 'Dhaka'
-- planner multiplies: 1/200 countries x 1/3000 cities = 1/600,000
-- reality:          1/200 countries                = 1/200
It underestimates by three thousand. Underestimate the row count and the planner picks a plan that is wrong for the data it will actually meet, which usually means a nested loop over a table it should have hashed.
CREATE STATISTICS orders_country_city (dependencies)
ON country, city FROM orders;

ANALYZE orders;
dependencies handles functional relationships like this one. mcv records combinations of values that are common together, which is the right tool when the relationship is not a strict implication but the two columns are still correlated. This is the fix for “the planner chooses a nested loop on a join that obviously should be a hash join”, and it costs one row of statistics and one ANALYZE.
Cost settings are a budget, not a hint
Changing random_page_cost to 1.1 is a legitimate move when the storage is genuinely fast, and it should be done in the knowledge that it applies to every query in the instance.
-- for a database whose working set fits in RAM
ALTER SYSTEM SET random_page_cost = 1.1;
ALTER SYSTEM SET effective_cache_size = '24GB';
SELECT pg_reload_conf();
effective_cache_size is the one people get wrong. It does not allocate anything. It tells the planner how much of the operating system’s page cache it should assume is available, and it is the difference between a planner that assumes everything is a disk read and one that assumes a large fraction of the index is already in memory.
Setting random_page_cost = 0.1 is the common mistake. At that point the planner believes random reads are essentially free, and a two-million-row nested loop starts to look competitive with a hash join, which is a plan that will collapse as soon as the working set exceeds the cache.
The honest position is that cost parameters are a model, and the model should match the hardware. Change them deliberately, at the instance level, and measure before and after on a representative query set. Changing them per query, or in the hope of nudging one plan, does not work because the planner has no idea why you did it.
Arguing with the planner properly
There are four legitimate responses to a wrong plan, and only one of them is a cost parameter.
Write a sargable predicate. The highest-value fix by a wide margin, because it is a real improvement rather than a reweighting. Remove the function from the column, fix the type coercion, replace the leading wildcard, convert the OR into a UNION of two sargable branches if the planner will not use a bitmap.
Index the expression. If you genuinely need a derived value, it can be indexed only when every function in the index expression is immutable. The plain cast from timestamptz to date depends on the session time zone and is not immutable, so make the intended zone explicit.
CREATE INDEX orders_created_utc_day_idx
ON orders (((created_at AT TIME ZONE 'UTC')::date));
CREATE INDEX orders_created_at_idx ON orders (created_at);  -- keep both if both are used
The expression index is useful when the query uses a matching expression. It does not help WHERE created_at >= ..., which is why the range index remains necessary if both access paths are real, and why resolving boundary instants in the application is usually clearer.
Make the index partial. A partial index that covers 3% of the table is dramatically smaller, and the planner prefers small indexes because the cost model rewards that.
CREATE INDEX orders_pending_idx ON orders (created_at)
WHERE status = 'pending';
The planner can only use it if it can prove the query’s predicate implies the index predicate, so the query must contain that condition, not an equivalent one it cannot match.
Raise the statistics target. For a column with an unusual distribution, tell the collector to keep more detail.
ALTER TABLE orders ALTER COLUMN status SET STATISTICS 1000;
ANALYZE orders;
And when arithmetic is not the problem, measure rather than theorise. EXPLAIN (ANALYZE, BUFFERS) runs the query and reports both the plan and what actually happened, including how many rows the planner expected against how many arrived.
EXPLAIN (ANALYZE, BUFFERS, VERBOSE)
SELECT * FROM orders
WHERE tenant_id = 42 AND created_at >= '2026-08-01'
ORDER BY created_at DESC LIMIT 50;
An estimate off by more than an order of magnitude on a large table means the statistics are the thing to fix. Estimates that are roughly right with a bad plan mean the cost model is the thing to look at. Knowing which of the two you are dealing with is most of the work.
A production-ready architecture
Indexes and statistics have an owner and a refresh path, otherwise they drift within a month of being created correctly.
  query arrives
       |
       v
  +---------------+   sargable?    +-------------------+
  | predicate     | -------------> | yes -> index ok   |
  | shape         |                +-------------------+
  +---------------+
       | no -> rewrite the predicate, do not add an index
       v
  +---------------+   expected vs   +-------------------+
  | EXPLAIN       | --actual-->    | off by >10x?      |
  | (ANALYZE,     |               | yes -> ANALYZE,   |
  |  BUFFERS)     |                | then scale factor |
  +---------------+                +-------------------+
       | estimates roughly right, plan still wrong
       v
  +-------------------------------+
  | dependencies / mcv statistics |
  | then the cost model           |
  +-------------------------------+

  +--------------------------------------------------+
  | background: autovacuum_analyze_scale_factor tuned |
  | per table, not globally                         |
  +--------------------------------------------------+
A delivery checklist:
- Run
EXPLAIN (ANALYZE, BUFFERS)before concluding anything. A plan withoutANALYZEis a guess. - Compare estimated rows to actual rows first. That comparison decides whether the problem is statistics or cost.
- Fix non-sargable predicates before creating any index. An expression index over a bad predicate makes the bad predicate look intentional.
- Check the predicate for column-side casts, especially where an external identifier is stored as text but treated as numeric by one caller.
- Look for a missing leading constraint in composite indexes. On PostgreSQL 18+, verify whether skip scan helps on the real distribution rather than assuming it will.
- Lower
autovacuum_analyze_scale_factoron tables whose distribution changes, rather than runningANALYZEby hand forever. - Add
dependenciesstatistics for columns that imply each other, before touching cost settings. - Keep a partial index for a status filter that covers a few percent of the table, and make sure the query implies its predicate.
- Set cost parameters once, for the instance, to match the actual storage. Do not set them per query.
- Watch for indexes that are never used after creation. A write-amplifying index nobody reads is a liability.
Failure stories worth testing
Wrap an indexed column in a function and watch the plan change
Compare a selective half-open range on indexed created_at with a query that wraps the column in an unindexed expression. On representative data, inspect whether the usable index condition disappears and how many rows are filtered. Do not assert that one query must use an index: the planner can correctly choose a sequential scan when the relation is small or the range is not selective.
Cross a distribution threshold and re-run the query
Insert rows into one status until it is no longer rare, then run EXPLAIN before and after ANALYZE. Watch the estimated row count jump. This is the test that separates “the planner is broken” from “the planner is working from last week’s picture”.
Build a composite index and query each column on its own
Test the first column, the second, and both together on (tenant_id, created_at). Compare PostgreSQL versions and data with few versus many distinct tenants. If PostgreSQL 18 chooses skip scan for the trailing column, measure entries and pages read; a plan node using the index is not automatically the cheapest production index design.
Set random_page_cost to 0.1 and re-run a known-good plan
Confirm the nested loop plan appears for a join that was previously a hash join. This is what an over-corrected cost model looks like, and it fails only under memory pressure, which is the worst time to discover it.
Correlate two columns and watch the estimate collapse
Add a dependencies statistics object for a country and city pair, run ANALYZE, and compare the row estimate before and after. A three-thousand-fold swing on a correlated pair is normal and is entirely invisible without the statistics.
Common mistakes
| Mistake | What actually happens | Better decision |
|---|---|---|
Trusting EXPLAIN without ANALYZE |
You are reading the plan the planner wished it would use | EXPLAIN (ANALYZE, BUFFERS) before concluding |
| Adding an index over a wrapped column | The index exists and can never be entered | Rewrite the predicate, or index the expression |
Dropping random_page_cost to 0.1 |
Random reads look free and nested loops start winning | Set it once, to a value matching the storage |
Treating effective_cache_size as an allocation |
Nothing is reserved and the planner is not told anything useful | Use it to describe the real OS page cache |
| Believing a trailing composite column guarantees efficient narrowing | Later keys do not narrow like a leading key; skip scan is version- and cost-dependent | Measure on the deployed version and use a correctly ordered index for a hot path |
Assuming an OR is free |
Either two scans or a scan, depending on the branches | Make each branch sargable, or use a UNION |
Running ANALYZE by hand and calling it fixed |
It drifts again within a week | Lower the analyze scale factor for that table |
| Reading a sequential scan as an indexing failure | On a low-selectivity predicate it is the cheaper plan | Check the estimated row count first |
| Assuming independent columns | The planner multiplies selectivities and underestimates badly | CREATE STATISTICS ... (dependencies) |
| Changing cost settings per query | The planner cannot know, and the plan is unstable | Instance-level, deliberate, measured |
| Building an index nobody queries | Write amplification on every insert, paid for nothing | Review usage before adding the next one |
The complete story in one minute
The planner estimates how many rows your predicate matches, multiplies that by a cost per row, and compares the answer against the cost of a sequential scan. Both sides of that comparison are built from statistics and cost parameters, so a wrong plan is either a wrong estimate or a wrong exchange rate, and the difference is visible in EXPLAIN (ANALYZE) as a gap between estimated and actual rows.
Most of the time the planner is right and the predicate is wrong. An unindexed expression applied to a column removes the plain index condition, an explicit cast around the indexed column changes the searchable expression, a leading wildcard has no prefix to search from, and a != filter that matches 80% of the table is not an optimisation. None of these are repaired by adding another ordinary index without fixing the query shape.
The second cause is statistics that describe a table that no longer exists. Postgres samples on a schedule, and a table whose status column or plan tier has shifted since the last sample produces a confident, wrong, and internally consistent estimate. Lowering the analyze scale factor on the tables that churn fixes it durably; running ANALYZE fixes it until next week. When two columns imply each other, the planner’s independence assumption is wrong by orders of magnitude and dependencies statistics correct it for the price of one row.
Only after both of those are ruled out is the cost model worth touching, and then it is worth touching once, for the instance, to describe the storage you actually have. Lowering random_page_cost does not make an index better, it makes indexes look better to every query at once, including the ones that were correct. The index you were missing was probably a sargable predicate, and the fix was to stop asking the database a question its index could not hear.
Technical references
Related notes.
Covering Indexes: Turning One Random Read Per Row Into Zero
Why a matching index still costs one random read per row, how INCLUDE columns turn that into an index-only scan, and why a stale visibility map quietly puts the heap read back.
UUID Primary Keys: Locality, Page Splits, and the Cost You Must Measure
Random UUIDs spread B-tree inserts across leaf pages; time-ordered UUIDs improve locality. The effect differs sharply between InnoDB's clustered table and PostgreSQL's heap.
OFFSET Pagination: The Query That Gets Slower the Deeper You Scroll
OFFSET makes the executor process and discard rows before the page, so deep pages grow linearly even with an index. Keyset pagination bounds that work, and a unique tiebreaker makes the cursor unambiguous.