Distributed Lock Service: Why a Lock Is Not Enough and the Token That Fixes It
Fencing tokens, Redlock's pause problem, ZooKeeper's sequential ephemeral nodes, and the honest limits of TTL-based mutual exclusion.
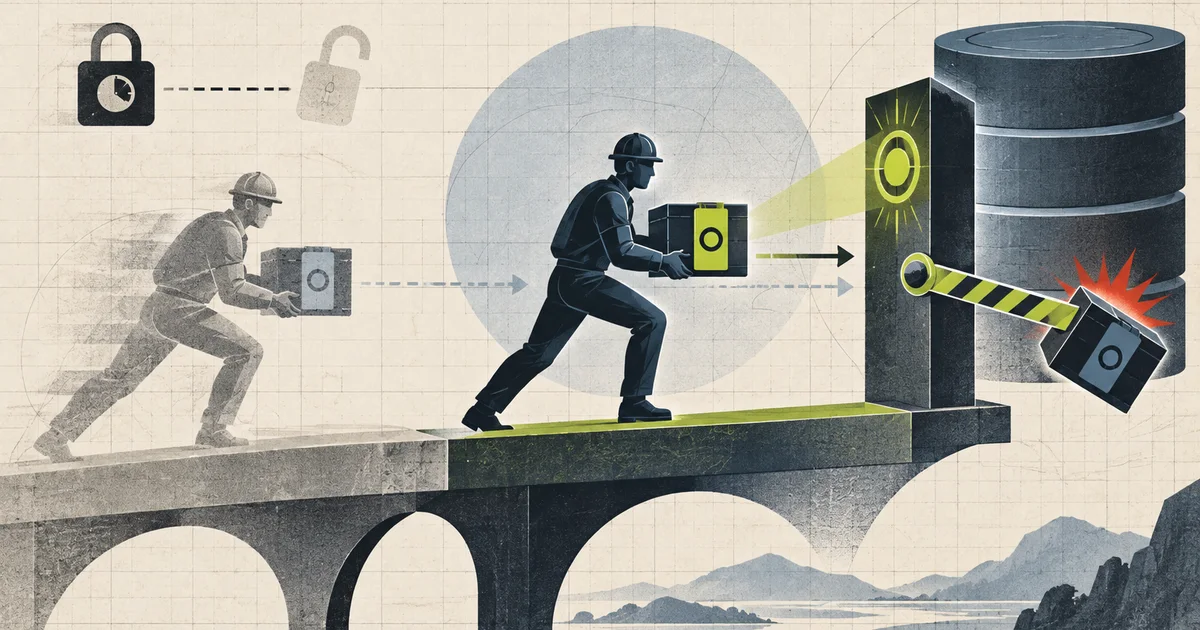
A distributed lock is easy to describe and quietly dangerous to build.
“Only one process at a time may do this.” That is mutual exclusion, and every implementation looks correct until a process stops for longer than the lock’s TTL and comes back believing it still holds the lock. At that point two processes are inside the critical section, and the storage system behind them has no idea anything is wrong.
The whole subject reduces to one question: how does the thing you are protecting detect that the lock holder is no longer trustworthy?
The scale, and why most of it is not interesting
A platform with ten thousand services, each taking about ten locks per second.
10,000 services x 10 acquisitions/sec   = 100,000 lock ops/sec

the overwhelming majority are uncontended
  the same service re-taking a lock it just released
  these are single-node operations, well under 1ms

contended locks
  a small number of resources with many waiters
  at 100 waiters, releasing a lock must wake the
  next one rather than let everyone retry

live lock state
~50,000 held locks x ~200 bytes          = 10 MB
Ten megabytes of state and a hundred thousand operations a second is not a distributed systems problem. The problem is entirely about correctness under failure, and about what happens to the ten thousand waiters who all woke up when one holder released.
This is worth saying plainly, because it is the difference between building this on etcd and building it on something you wrote yourself. You are not building a fast system. You are building a system whose failure behaviour you can reason about, and buying that with a dependency is almost always the right trade.
Three implementations, three guarantees
A single node with SET NX PX
SET lock:invoice-42 acme:9931 NX PX 10000NX means only set if absent and PX supplies a millisecond expiry. On one Redis primary this acquisition is one command. Safe release still needs compare-and-delete so an expired holder cannot delete a successor’s lock.
It is also a single point of failure, and if Redis restarts without persistence configured, every lock in the system evaporates instantly. For an uncontended lock around something idempotent, that may be a perfectly acceptable trade. For a lock protecting a payment, it is not.
Redlock across independent masters
Acquire the lock on N Redis nodes that replicate to nothing and have nothing to do with each other. The acquisition succeeds only if a majority are acquired, and the whole thing must complete inside a validity window.
validity = TTL - elapsed_time - clock_drift_allowanceattempt on 5 independent masters
success: 3 of 5 acquired
elapsed: 3ms
TTL: 10,000ms
validity: 10,000 - 3 - 2 = 9,995msWith five independent masters, the algorithm can acquire through two unavailable nodes under its timing assumptions. That is a specific availability/safety model, not the same guarantee as a consensus lease, and it still does not fence a paused former holder from the protected resource.
etcd or ZooKeeper ephemeral keys
The key is created with a lease. The holder renews it. If the holder dies, the lease expires and the key is deleted, which releases the lock without anyone noticing.
acquire:
  txn(
    compare: [/locks/invoice-42 does not exist],
    success: [put /locks/invoice-42 = {holder, token}, with lease],
    failure: [get /locks/invoice-42]
  )

renew:
  LeaseKeepAlive(lease_id) every 3 seconds
  TTL of 10 seconds

release:
  txn(compare: [value == me], success: [delete key])
Exactly one caller wins the compare-and-set, because the transaction is atomic. That is the whole safety argument, and it rests on the store’s linearizability rather than on clever locking code.
When the invariant truly depends on coordination, use a maintained consensus-backed primitive rather than designing one from storage commands. Even then, the lease alone does not protect an external resource from a paused former holder.
The problem that breaks all of them
Here is the scenario. It is not exotic and it does not require a network partition.
t=0ms      process A acquires the lock
           A now believes it holds the lock

t=1ms      A is descheduled. Or a GC pause begins.
           Or the VM is migrated by the hypervisor.
           Or the process is frozen by a container runtime.

t=0..9000  A is not running. It knows nothing.

t=9000     A's lease TTL expires server-side.
           The key is deleted.

t=9500     process B sees the key gone, acquires it.
           B now believes it holds the lock.

t=9501     A wakes up. It still believes it holds the lock.
           It has no way to know.

           A and B are both inside the critical section.
The critical detail is that A is not wrong about its own state in any way it can detect. It did a successful acquire. It did not get an error. It resumes and calls the protected resource believing it is still the mutual exclusion that makes the operation safe.
This is why TTL-based mutual exclusion is incomplete. The lock has an expiry for the case where the holder dies. It has no protection for the case where the holder is alive, unaware, and no longer the holder.
Note what this means for algorithms, not just deployments. A stop-the-world GC pause of several hundred milliseconds is normal. A full-heap collection on a large heap can be a second or more. A hypervisor pause during a live migration is seconds. In any language with a garbage collector, there is a realistic chance of a pause long enough to matter, and no lock TTL short enough to be operationally useful is safe against a pause longer than itself.
The fix: a fencing token
The resource being protected has to be able to reject a write from a holder that has been superseded. The way to do that is to hand out a monotonically increasing number with every acquisition and have the resource enforce it.
acquire lock -> returns token 1042

A uses it:  write(resource, value, token=1042)  -> accepted
                                (resource remembers 1042)

A pauses. B acquires the lock.

B uses it:  write(resource, value, token=1043)  -> accepted
                                (resource remembers 1043)

A resumes: write(resource, value, token=1042)  -> REJECTED
                                (1042 < 1043)
A’s write is refused, not because the lock service told it anything, but because the resource itself noticed the token went backwards. A’s error may be confusing — it believes it holds a valid lock — but the system is safe, and A will discover the problem on the write that matters.
This answers the stale-writer part of the pause problem only when every side effect passes through a resource that atomically enforces the token. An email, external API call, or store without conditional writes remains outside that safety boundary.
The requirement this creates is on the resource, not the lock service. The protected store must support conditional writes on a monotonic counter: “accept this write only if its token is greater than the highest I have seen.” That is easy in a database you control and it does not exist in most object stores, most message queues, and most distributed filesystems. This is the practical reason fencing tokens are less common than they should be, and it is worth checking before you design around them.
The token itself comes for free if your lock lives in a consensus store:
etcd:       the successful create transaction's revision
ZooKeeper:  an ordered lock recipe can use the sequential-node order;
            zxid is server transaction order, not the queue node suffix
etcd revisions are cluster-wide logical revisions and are a natural fencing candidate when the lock acquisition and revision are one committed transaction. ZooKeeper’s EPHEMERAL_SEQUENTIAL recipe orders contenders under a parent; its sequence counter is parent-scoped and has documented overflow behavior, so token encoding and comparison need to follow the implementation rather than assume an unbounded global integer.
Fairness, if you need it
An unfair lock has no FIFO admission guarantee; “whoever asks first” describes a fair queue, not an unfair lock. Under contention, scheduling and races decide the winner, so starvation is possible.
ZooKeeper’s documented recipe creates an ephemeral sequential node under the lock path. Ordering is by the sequence suffix within that parent, and each contender watches its immediate predecessor.
/locks/invoice-42
  ├── queue-0000000000000001   (holds the lock)
  ├── queue-0000000000000002   (watches queue-0000000000000001)
  └── queue-0000000000000003   (watches queue-0000000000000002)
Everyone watches only their immediate predecessor. When queue-...01 is released and deleted, its watcher wakes up, checks that it now has the lowest remaining sequence, and takes the lock. Each waiter watches one node instead of all of them, so there is no thundering herd — the wake-up chain is O(1) per release rather than O(waiters).
That is the whole technique, and the same structure works on top of a lease-based store: a monotonic counter as the sequence, a watch per waiter on its predecessor, and a check for the lowest remaining number on wake.
The cost is real and you should be honest about whether you are paying it deliberately. Sequential nodes allocate a node per waiter, every release costs a wake-up plus a read to confirm, and the queue must be garbage collected if waiters abandon. In a system where the lock is uncontended 99.9% of the time, all of that is pure overhead to make the 0.1% case fair. Most systems do not need it.
Contention, and what to do about it
A hot lock serialises every acquire. A thousand services contending on one resource is a design problem, not a scaling problem, and the three fixes are ordered by how often they are the right one.
Shard the resource. Instead of one lock:account, use lock:account:{shard}. Ten shards turns one serialisation point into ten and ten thousand into a hundred thousand. The catch is that this only works if the critical section can genuinely be split, and it cannot if the section spans the whole account.
Change the concurrency model. A read-write lock lets many readers proceed while a writer waits, which is usually what a cache or a lookup actually wants. A striped lock — N independent locks indexed by a key hash — gives the same benefit when contention is on many similar resources rather than one.
Drop the lock. If conflicts are rare, compare-and-swap is better than mutual exclusion: no serialisation at all, no waiting, no TTL, and no pause problem. A read followed by a conditional write retries on failure. This is strictly better whenever the operation is idempotent and the conflict rate is low, which is more often than people assume.
Deadlock detection, when you hold more than one
Holding two locks in a consistent global order removes deadlock by construction. When that is not possible — because the set of locks is discovered at runtime — the wait-for graph gives you detection.
process A:  holds X, waiting for Y
process B:  holds Y, waiting for X

                    A
                   / \
              waits   holds
                 /       \
             holds       waits
                 \       /
                    B
              cycle -> victim
A background loop builds the graph from current lock state, finds a cycle, and picks a victim. Breaking it means forcibly revoking the victim’s locks — in a lease store that is deleting the key, which makes the victim’s next renewal fail and tells it, unambiguously, that it lost the lock.
Two things make this workable. The victim needs to be told, which a lease gives you for free and a bare advisory lock does not. And the cycle has to be detected in bounded time, so the graph is rebuilt periodically and the interval is a real parameter, not an implementation detail.
In practice, most systems should reach for the ordered-acquisition rule first and use detection as a safety net.
Failure stories worth testing
Freeze the lock holder for longer than the TTL
The single most important test in this whole area. Confirm the frozen process is unable to write when it resumes, because the token check rejects it. If it can write, the system has no safety and you have a lock service that only works when nothing goes wrong.
Kill the holder outright
The lease expires, the key is deleted, the next waiter gets the lock. Measure how long that takes; it is the TTL plus a renewal interval, and it is the recovery time of your lock.
Have every waiter wake at once
Release a hot lock with a thousand waiters. Exactly one acquires, the rest go back to waiting, and the process does not fall over.
Let the lock service restart entirely
Confirm what happens to live locks. With a consensus store, surviving members keep the state. With a single Redis node, they are gone, and that is the argument for the more expensive option.
Have a client abandon its wait
The ephemeral sequential node must disappear. Test that a client that disconnects mid-wait does not permanently block the queue behind it.
Lose quorum in the lock store
The lock service must refuse to hand out new locks. The dangerous outcome is not an outage, it is a lock service that keeps working from a minority and now has two independent views of who holds what.
Expire a lease that the holder still believes is alive
This is the same as the pause test, from the other side. Confirm the resource rejects the stale write and that the error is logged somewhere an operator will eventually see it.
Run two lock services against the same resource
If fencing tokens come from different sources they will not be comparable and safety is lost. This test should confirm that all tokens for a resource come from one monotonic sequence.
Renew a lease from a process that has been frozen
Confirm the renewal fails or the key is gone, rather than being accepted on arrival after a long gap.
A production-ready architecture
  acquire(resource, ttl)
        |
        v
  +---------------------------+
  |  lock coordinator         |  in-memory registry of
  |  local waiter queues      |  local waiters, so a
  |  monotonic sequence       |  broadcast only goes to
  +------------+--------------+  the local process
               |
      txn: compare key absent
            put key = {holder, token}
                  with lease
               |
               v
  +---------------------------+
  |  consensus store          |  etcd / ZooKeeper
  |  lease grants + expiry    |  linearizable, single
  |  watch on the key         |  source of truth
  +------------+--------------+
               |
    token = commit revision
               |
               v
  +---------------------------+
  |  renewal loop             |  every ttl/3, per holder
  |  failure -> release +     |  failure here is the
  |  wake local waiters       |  "process died" signal
  +---------------------------+

  client
    token = acquire(...)
    ... do work ...
    write(resource, value, conditional_on: token > last_seen)
                 |
                 v
          accepted, or rejected as stale
A sensible delivery checklist:
- Use a consensus store, not a single cache node, for anything that is not idempotent.
- Return a fencing token with every acquisition, sourced from the store’s own commit revision.
- Verify the protected resource can enforce
token > last_seenbefore you rely on it. If it cannot, the lock is advisory and must be treated as such. - Release with a compare-and-set on the value, so a process cannot release a lock that has already been taken by someone else after a lease lapse.
- Set TTL from the worst-case pause and renew at a third of it. Both numbers are consequences of the pause scenario, not of comfort.
- Skip fairness unless a specific caller needs it, and document that decision.
- Shard hot resources before tuning anything. An ordered-acquisition rule beats any amount of queue engineering.
- Use compare-and-swap instead of a lock wherever the operation is idempotent and conflicts are rare.
- On renewal failure, treat the lock as lost immediately — not on the next write — and make the client abort whatever it was doing.
- Log every fencing-token rejection. It is the signal that a client has a real correctness bug rather than a transient failure.
- Give the victim selection in deadlock detection a policy, and make revocation observable to the victim.
- Test the freeze scenario in a real environment. Reasoning about it is not the same as seeing it.
Common mistakes
| Mistake | What actually happens | Better decision |
|---|---|---|
| No fencing token | A paused holder resumes and corrupts shared state | Return a monotonic token, enforce it in the resource |
| Assuming TTL prevents exclusion failure | The holder is alive, not expired, and unaware | Tokens, not timeouts, provide safety |
| Fencing token from a non-monotonic source | Tokens are not comparable and safety is lost | Use the consensus store’s commit revision |
| Single Redis node for a critical lock | A restart silently drops every held lock | Consensus store, or accept the risk explicitly |
| Release without compare-and-set | You delete a lock that now belongs to someone else | Release only if the value is still yours |
| Lease TTL shorter than a plausible GC pause | Healthy holders lose locks constantly | Size for the worst pause, renew at TTL/3 |
| Renewal interval close to the TTL | One dropped packet loses the lock | Renew at a third of the TTL |
| FIFO fairness where it is not needed | Extra nodes, extra round trips, extra latency | Unfair by default; document the exception |
| Waiters all watch the same node | Every release wakes every waiter | Watch the immediate predecessor only |
| One global lock for a hot resource | Throughput is capped at one serialisation point | Shard the resource or use a striped lock |
| No deadlock rule | Two resources taken in different orders deadlock | Acquire in a global order, detect as a backstop |
| Treating the lock as advisory but assuming it is not | Any client bug becomes silent data corruption | Enforce in the resource, and log rejections |
| Losing quorum and continuing to serve | Two independent views of who holds what | Refuse to issue locks without a quorum |
| Believing the happy path is the test | The bug only appears during a GC pause | Run the freeze test before shipping |
The complete story in one minute
A lease can serialize ownership in the lock store while still allowing a paused former holder to resume with stale authority. The failure is at the protected resource boundary. No TTL proves that a process cannot pause longer than the lease; fencing or an equivalent conditional write is what rejects stale work.
The fix is a fencing token: a monotonically increasing number returned with every acquisition, with the protected resource rejecting any write carrying a token lower than the highest it has seen. The stale holder’s write is refused even though the lock service told it nothing, and the number can come free from the consensus store’s commit revision, so the token source and the lock source cannot disagree.
Which lock store you use follows from that. A single Redis node with SET NX PX is one round trip and disappears on restart. Redlock across independent masters tolerates node failure but does not fix the pause problem, because the algorithm never claimed to. etcd or ZooKeeper with a lease gives atomic acquisition via compare-and-set and automatic release on death, at the cost of depending on linearizability.
Fairness is optional. Sequential ephemeral nodes give FIFO by having each waiter watch only its predecessor, which is a nice general pattern and pure overhead in a system where the lock is uncontended 99.9% of the time.
And the real fix for contention is usually not a better lock. Sharding the resource turns one serialisation point into N. And wherever the operation is idempotent and conflicts are rare, compare-and-swap beats mutual exclusion outright, because it has no waiters, no TTL, and no pause problem.
acquire -> token
   |
   +---> use, carrying the token
   |
   +---> write rejected if the token went backwards
The hard part was never making two processes take turns. It was making every protected effect reject the process whose turn had already ended.
Technical references
Related notes.
Distributed Configuration Management: The Part Where Everyone Builds a ZooKeeper
Raft, linearizable reads, watch fan-out, and MVCC — how etcd and Consul actually keep fifty thousand services watching config without falling over.
Travel Review Platform: Moderation, Fraud, and the Recency Problem
Running a travel review platform at scale — review eligibility, fraud detection, ranking that resists gaming, and the moderation workflow that makes it trustworthy.
CockroachDB from First Principles: The Database That Refuses to Die
Why a global SQL database is really a problem of agreement and time, how Google solved it with TrueTime, GPS, and atomic clocks, and how CockroachDB reaches a practical design on ordinary infrastructure.