Travel Review Platform: Moderation, Fraud, and the Recency Problem
Running a travel review platform at scale — review eligibility, fraud detection, ranking that resists gaming, and the moderation workflow that makes it trustworthy.
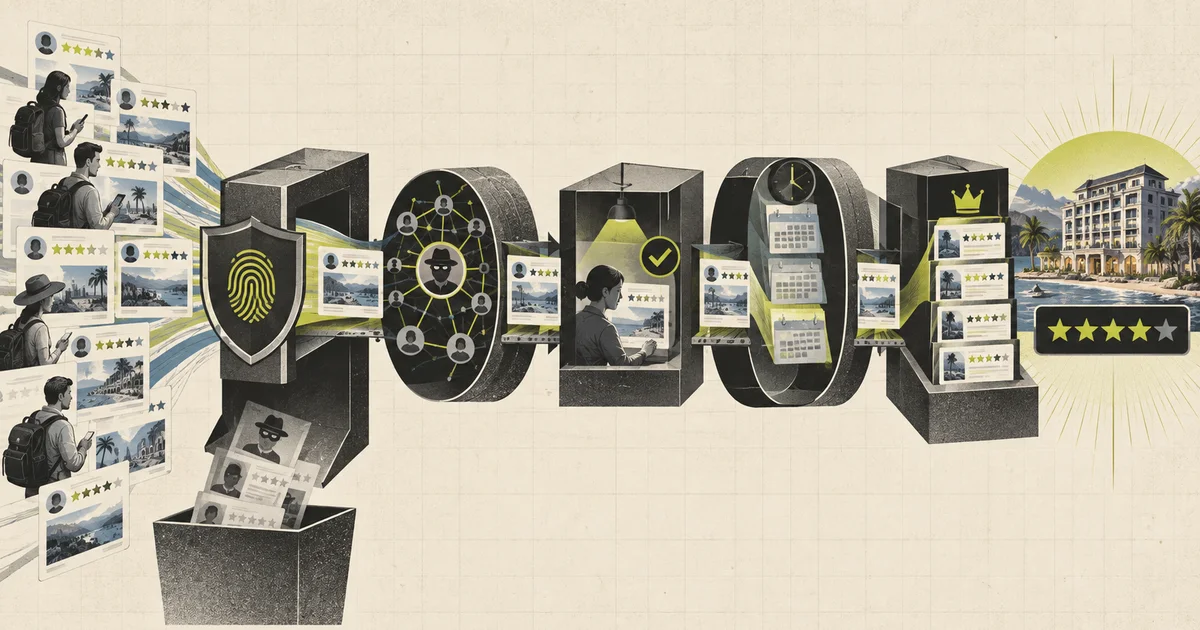
Reviews are the highest-value, lowest-quality data in travel. A guest who had a bad stay and a guest whose booking was cancelled by the platform produce the same three-sentence review with the same rating, and a platform that cannot tell them apart is ranking noise.
The scale
  a large travel platform
    20M reviews
    3,000-5,000 new reviews per day
      - peak 20,000 (post-holiday)
    8M verified "I stayed here" reviews
    12M unverified ("reviewed an
      experience / airline / tour")
    2M properties + 500 airlines

    moderation volume
      20,000/day at peak
      - auto-flagged: 15-25% by
        model, but almost all pass
      - human-reviewed: 300-800/day
      - appeals: 50-150/day

    ranking inputs
      - average score (and its
        distribution, not just the mean)
      - recency weighting
      - volume and its distribution
      - verified-stay proportion
      - fraud scores
      - helpfulness votes
      - recency of the reviewer
        (a reviewer with 40 reviews in
         a week is a pattern, not a
         person)
That last item is more informative than people expect. The rate at which a reviewer writes reviews is one of the strongest fraud signals available, because genuine guests stay a few times a year and review platforms employ dozens of accounts.
Eligibility, and why it is the foundation
  the requirement
    "verified stay" means:
    - the reviewer was a real guest
    - at THIS property
    - on a real booking
    - that has completed (or is
      within the review window)

  the mechanism
    post-stay invitation
    - the booking completes
    - an invitation is sent with a
      single-use token
    - the token is bound to the
      booking, not the property
    - the review it produces is
      VERIFIED

  the properties that matter
    - the token is SINGLE USE
      (no sharing a link to 50 people)
    - the token is BOUND TO A BOOKING
      (a review of a different property
       with the same token is not
       verified)
    - the invitation window is
      defined and enforced
      (e.g. 3-24 months)
    - the review is bound to the
      BOOKING, not the property, so a
      guest who stayed twice gets two
      reviews
    - and the property can RESPOND
      once, publicly, to each review
Verified-stay review systems are the ones that work, and every property of the token design is doing work. A token that can be reused or that is not bound to a specific booking is a “verified” label with no verification in it, and once users learn that, the label means nothing.
One interesting case: reviews of a stay that was cancelled by the platform. The guest genuinely stayed-or-attempted-to-stay and has a real experience, and the correct treatment is a verified review that is not attributed to the property’s quality score — because the platform failed, not the hotel. This requires the review to carry more than a boolean: it needs a category (stay, cancellation, service issue) and a way to keep platform-caused cancellations out of the property’s rating while still letting the guest be heard. Excluding them entirely is defensible and simpler; excluding them without telling the guest is not.
Fraud: an attack on the ranking
  the incentive
    a good review raises a property's
    score
    -> more direct bookings
    -> the property has a direct
       financial incentive to buy
       reviews
    -> competitors have an incentive
       to sabotage

  the attack patterns
    - volume: hundreds of 5-star
      reviews over weeks
    - burst: 30 reviews in 2 days
    - synchrony: reviews arriving in
      waves, similar length, similar
      vocabulary
    - reviewer networks: accounts that
      review each other, all in the
      same city, all "verified"
    - compensation: hosts offering a
      discount for a review (illegal in
      many jurisdictions, hard to
      detect directly)
    - competitor sabotage: 1-star
      waves with a distinctive topic
      ("the wifi was terrible")

  the defences
    1. RATE-BASED signals
       reviews per month per reviewer,
       burst detection, wave detection
    2. GRAPH signals
       reviewer-reviewer edges (do they
       review each other's properties?),
       property-property edges, shared
       device / IP / payment / address
    3. TEXT signals
       embedding similarity to other
       reviews of the same property,
       near-duplicate detection, n-gram
       overlap across "independent"
       reviews
    4. BEHAVIOURAL signals
       review length distribution vs.
       the reviewer's history, rating
       deviation from their other reviews
       (a reviewer who always gives
        5s suddenly giving 1s at one
        property)
    5. INCREMENTAL signals
       does a review appear immediately
       after a review request? does the
       property have a suspicious ratio
       of reviews to bookings?
The most underused signal is the graph one, and it is the most robust. A reviewer-reviewer graph built from “these accounts reviewed properties in a pattern consistent with collaboration” catches distributed fraud that no text classifier will, because the text is genuinely different and the accounts are genuinely created by different people. Shared infrastructure (payment instruments, device fingerprints, addresses) is the same idea in a different form, and it requires the platform to be willing to collect and retain that linkage, which is a privacy decision as well as an engineering one.
The structural defence matters more than any detector. Make the incentive cost more than it earns. Practical mechanisms: reviews only affect ranking when they are verified stays; verified stays require a real booking, so bulk purchased reviews cannot become verified; the review’s effect on ranking is dampened for properties with an unusual review-to-booking ratio; and the platform’s badge and placement are tied to the distribution and trend, not the mean, so a burst of 5s moves a property less than a burst would suggest.
The distribution point is worth expanding because it is a genuine ranking improvement rather than a fraud control. A property with 200 reviews averaging 4.8 with a tight distribution is reliably good. A property with 8 reviews averaging 4.8 might be excellent or might be 8 cherry-picked ones. So the ranking should use a confidence-adjusted score: the Bayesian posterior mean, which shrinks small-sample means toward the global mean. This handles the small-sample problem correctly, and it is the same shrinkage that makes any average-of-small-numbers trustworthy.
Recency, which is the thing that makes travel rankings feel wrong
  the situation
    property had a 4.6 average
    last year
    a refurbishment happened in
    March
    since then: 40 reviews at 4.9
    no negative reviews since March

  a plain average says 4.65
  the guest-relevant answer is
    "4.9 since March, and this is a
     new, refurbished property"

  the same in the other direction
    a legendary 4.9 property that
    has quietly declined to 4.1 for
    six months
    the average hides the decline
    entirely
Three mechanisms fix this, and a platform needs all three:
Time weighting. Exponentially or half-life decay, so recent reviews dominate. A half-life of 6-12 months is a reasonable default for hotels; longer for stable categories like airlines, where service changes slowly.
Trend detection. Fit a slope over the recent reviews and show the direction. A property at 4.9 and falling is a different recommendation than one at 4.9 and stable, and the trend is available long before the average moves.
Change detection for the property itself. A refurbishment, a new management company, a construction period — these are events that reset the relevance of history. The platform often knows about them (the property told it, or the data shows a review gap), and when it does, the history before the event should be visually and computationally separated. This is the single most useful thing a platform can do for a property in transition, and it is rarely done.
Ranking, and the gaming surface
  the ranking signal list
    - confidence-adjusted score
      (Bayesian posterior mean)
    - time-weighted (recency)
    - verified-stay proportion
      (weighted higher)
    - volume
    - fraud-adjusted (removals
      excluded, suspicious downweighted)
    - trend
    - review length (a proxy for
      effort, weakly correlated with
      usefulness)
    - helpfulness votes
    - reviewer history (a reviewer
      with a pattern of accurate
      reviews, however you measure it)

  the anti-gaming move
    a review gets:
      - surface order: by default
        recency, which is gameable but
        honest
      - "most helpful" sort: by the
        helpfulness signal

    "most helpful" is an ATTACK
    SURFACE
      - authors learn that specific
        phrasing ranks well
      - campaigns optimise for it
      - and helpfulness votes are
        cheap to buy
The “most helpful” sort is a genuine problem, and the standard mitigations are: weight votes by the voter’s own history (one vote from a reviewer with a track record of useful votes, many from accounts created to vote), cap a review’s contribution to the helpfulness ranking over time, and never let helpfulness affect the quality ranking — only the display order within a quality band.
The deeper principle: ranking signals should be a small set of durable quantities, and everything else should be display. A review’s text is content. Its helpfulness is a display property. The property’s quality is a statistical estimate. Mixing these into one opaque score makes the system impossible to reason about and trivially gameable, and the fastest way to make ranking trustworthy internally is to make it explainable: given a property and a date, be able to say which signals moved the estimate and by how much.
Moderation as a queue
  the pipeline
    1. INGEST
       - bind to booking if verified
       - language detection
       - immediate hard blocks:
         PII (phone, email, address),
         hate/abuse categories that
         are illegal to host,
         competitor solicitation
    2. AUTO-ASSESS
       - fraud score
       - toxicity
       - relevance (is this a review
         of a hotel, or a restaurant
         review posted on a hotel?)
       - PII redaction
    3. ROUTE
       - clean -> publish
       - borderline -> human queue,
         ordered by
           * harm if published
             (a defamatory or
              PII-bearing review)
           * likely fraud
           * property appeal
       - clear violation -> reject
         with a reason the author
         can act on
    4. APPEAL
       - author can appeal once
       - a different moderator reviews
         it (separation of duties)
    5. AUDIT
       - sample of "clean" decisions
         reviewed for quality
         - moderator agreement tracked
         - a decision taxonomy that
           supports reporting

  the SLA
    - hard violations: minutes
      (PII, illegal content)
    - fraud: hours
    - borderline: 24-72h
    - and an expiry: if moderation
      does not happen in the window,
      what is the default?
      -> "publish" leaks bad content
      -> "hold" denies a legitimate
         review
      -> this is a product decision
         that must be made explicitly
The SLA question at the end is the one that gets left implicit and then causes an incident. Every queue needs a stated default on timeout, and the choice between publishing a borderline review and holding a legitimate one is a product judgement with different victims. Most platforms publish low-harm borderline content with a flag and a fast removal path, and only hold for specific categories where publishing causes real damage.
Separation of duties on appeals is a small implementation detail with a large effect on perceived fairness, and the audit sample is how you find out that your moderators disagree with each other systematically. Moderator agreement, measured, is a quality metric that almost nobody tracks and everybody should.
Failure stories worth testing
Reuse a booking token across 50 accounts
The token must be single-use and bound to a booking. This is the verification test.
Review a different property using a valid booking token
Must be rejected. Binding is to the booking, not the property.
Have a property buy 200 five-star reviews over three months
Measure the effect on its ranking before and after rate-based and graph signals. It should move far less than the raw count suggests.
Look for reviewer networks with identical device fingerprints
Confirm the graph signal catches accounts that no text classifier separates.
Add a 40-review property averaging 4.8 and compare its rank to a 200-review property at 4.7
Bayesian shrinkage should place the small-sample property above, but not dramatically. This is the confidence test.
Have a property decline from 4.8 to 4.1 over six months and check what the page shows
Trend detection should show the decline. A plain average hides it.
Refurbish a property in March and compare the displayed score before and after
The history-pre-event separation is the useful fix, and it is the one most often missing.
Let a review’s author learn the “most helpful” phrasing and run a campaign
Watch the helpfulness ranking degrade. The mitigation is display-only helpfulness and voter weighting.
Test a borderline review and let the moderation queue exceed its SLA
The timeout behaviour must be explicit. Silence here becomes an incident.
Appeal a rejection with the same moderator
Separation of duties is required, and a different moderator should see the original reasoning.
Post a review containing a phone number and an address
Immediate hard block with PII redaction, before any queue.
Write 30 one-star reviews mentioning “wifi” at a competitor
Competitor-sabotage topic detection is a real and tested requirement.
Track moderator agreement on a sample of clean decisions
Systematic disagreement between moderators on the same content is the signal that the policy is not actually written down.
A production-ready architecture
   post-stay invitation (single-use token,
   bound to booking)
        |
        v
  +----------------------------------------------------------+
  |  INGEST + BINDING                                        |
  |  - token -> booking -> property + dates                  |
  |  - verified vs unverified, with category                 |
  |  - platform-caused cancellations separated               |
  +----------------------------+-----------------------------+
                               |
                               v
  +----------------------------------------------------------+
  |  FRAUD + SAFETY                                          |
  |  - rate / burst / wave signals                            |
  |  - reviewer graph + shared-infrastructure edges          |
  |  - text similarity across "independent" reviews          |
  |  - PII redaction, hard-block categories                   |
  +----------------------------+-----------------------------+
                               |
                               v
  +----------------------------------------------------------+
  |  MODERATION QUEUE (with SLA and a timeout default)       |
  |  - ordered by harm-if-published, then fraud likelihood   |
  |  - rejection with an actionable reason                    |
  |  - appeal to a different moderator                        |
  |  - audit sample + agreement tracking                      |
  +----------------------------+-----------------------------+
                               |
                               v
  +----------------------------------------------------------+
  |  RANKING (explainable, small signal set)                  |
  |  - Bayesian posterior mean (small-sample shrinkage)      |
  |  - time weighting (category-specific half-life)          |
  |  - trend slope                                            |
  |  - verified proportion, fraud-adjusted volume            |
  |  - pre/post-change separation for refurbished properties |
  |  - helpfulness = DISPLAY ONLY                             |
  +----------------------------+-----------------------------+
                               |
                               v
  +----------------------------------------------------------+
  |  DISPLAY                                                 |
  |  - distribution, not just the mean                        |
  |  - recent reviews first, with the date visible           |
  |  - trend indicator, recency of the last review           |
  |  - property response, shown in context                    |
  +----------------------------+-----------------------------+

  watch: review-to-booking ratio, verified share, fraud removals,
        moderator agreement, queue age p95, appeal overturn rate
Delivery checklist:
- Make verified-stay reviews structurally verified: single-use token, bound to a specific booking, with a defined invitation window. Everything else in the system depends on this.
- Give reviews a category so platform-caused cancellations can be excluded from a property’s quality score without silencing the guest.
- Build fraud detection on rate, burst, wave, graph, and text signals together, and prioritise the graph and shared-infrastructure signals because they catch distributed fraud that no text classifier will.
- Use a Bayesian posterior mean for the displayed score so a small-sample 4.8 does not outrank a well-evidenced 4.7, and show the distribution rather than the mean alone.
- Time-weight by category — months for hotels, longer for airlines — and add a trend slope so a property at 4.9 and falling reads differently from one at 4.9 and stable.
- Detect property changes (refurbishment, new management) and separate the history before the event, which is the most useful thing a platform can do for a property in transition.
- Keep helpfulness as a display-order signal only, weight its voters by history, and never let it touch the quality estimate.
- Keep the ranking signal list small and explainable, so an internal “why does this property rank here” question has an answer.
- Build moderation as a queue with a stated SLA, a reason taxonomy that the author can act on, and an explicit default on timeout.
- Separate duties on appeals and audit a sample of clean decisions, tracking moderator agreement as a quality metric.
- Hard-block PII and illegal content before the queue, not during it.
- Instrument the review-to-booking ratio per property as the primary structural fraud signal, and act on it in ranking as well as in investigation.
Common mistakes
| Mistake | What actually happens | Better decision |
|---|---|---|
| Reusable booking token | “Verified” means nothing | Single-use, bound to booking and property |
| Platform cancellations count against the hotel | Ratings measure the platform, not the property | Review categories |
| Mean score with no shrinkage | 8 cherry-picked 5s beat 200 real 4.7s | Bayesian posterior mean |
| No time weighting | A 4.6 from last year equals one from June | Category-specific half-life |
| No trend detection | Quiet declines hidden by the average | Slope over recent reviews |
| Text-only fraud detection | Distributed fraud with varied text survives | Graph and shared-infrastructure signals |
| Ranking on helpfulness | Authors optimise phrasing, campaigns run | Display-only, voter-weighted |
| Moderation with no timeout default | A queue stall becomes an incident | Explicit SLA and default |
| Same moderator on appeal | Perceived unfairness, no learning | Separation of duties |
| No PII block in the ingest path | Personal data published, then chased | Redact before the queue |
| Ignoring the review-to-booking ratio | Purchased reviews move the ranking | Structural signal, used in ranking |
| Unactionable rejection reasons | Authors cannot fix, they just retry | Reason taxonomy the author can act on |
| No audit of “clean” decisions | Policy drift is invisible | Sampled audit, agreement tracking |
| Reviews sorted by recency with no quality weight | Recent noise dominates | Quality first, recency as a tiebreak |
The complete story in one minute
Reviews are the highest-value, lowest-quality data in travel, and the whole system’s trustworthiness rests on one thing: knowing who is actually allowed to write. So verified-stay reviews need to be structurally verified — a single-use token bound to a specific booking and property, with a defined invitation window — and every property of that design is doing work. A reusable or unbound token makes “verified” a label with no verification in it, and users learn that within weeks. The interesting case is a stay cancelled by the platform: the guest genuinely has a real experience, so they need a review with a category that keeps it out of the hotel’s quality score without silencing the guest.
Fraud is a supply attack on a ranking system, and the defence is structural before it is a classifier. Reviews only move rankings when they are verified stays, which requires a real booking, which makes bulk purchase ineffective. On top of that: rate, burst, and wave signals; reviewer-reviewer and shared-infrastructure graph signals, which catch distributed fraud that no text classifier will because the text genuinely differs; and text-similarity detection for near-duplicates. But the highest-leverage ranking change is not a fraud control at all — it is using a Bayesian posterior mean instead of an average, so a property with eight cherry-picked 5s does not outrank one with two hundred genuine 4.7s, and showing the distribution rather than the mean.
Then recency, which is why travel rankings feel wrong without being factually wrong. A property refurbished in March with 4.9s since then and 4.6s before is not a 4.65, and a 4.9 property quietly declining to 4.1 for six months is not a 4.9. Time-weighting by category, a trend slope, and — the most useful and most neglected feature — separating the history before a detected property change, because a refurbishment resets the relevance of everything that came before it.
Keep “most helpful” as a display-order signal only, weighted by the voter’s history, and never let it touch the quality estimate, or authors learn the phrasing and campaigns follow. Run moderation as a real queue with a stated SLA, an actionable rejection reason, separation of duties on appeals, and — the thing that gets left implicit and then causes an incident — an explicit default on timeout.
single-use booking-bound tokens; review categories for platform failures
Bayesian shrinkage on the score, distribution shown, not the mean
time weighting + trend slope + pre/post-change separation
fraud: rate, graph, shared infrastructure, text similarity
helpfulness display-only; moderation SLA with an explicit timeout default
The hard part was never collecting opinions. It was that opinions arrive from people who stayed, people whose booking was cancelled, competitors, and fraud operations, all in the same shape, and a number that looks like quality is actually a mixture of all four.
What this team still owns
Verification means proving the review token maps to an eligible booking event; it does not prove the opinion is true. Preserve original content, edits, moderation decisions, evidence, appeals, and ranking eligibility separately. Fraud scores route work and reduce influence under a documented policy; they should not silently rewrite text or erase negative sentiment. Incentives are disclosed and never conditioned on a positive rating, and suppression metrics are audited by rating and reason.
Technical references
Related notes.
CockroachDB from First Principles: The Database That Refuses to Die
Why a global SQL database is really a problem of agreement and time, how Google solved it with TrueTime, GPS, and atomic clocks, and how CockroachDB reaches a practical design on ordinary infrastructure.
The RUM Conjecture: Read, Update, and Memory Amplification
The RUM conjecture frames an access method as a trade among read overhead, update overhead, and memory or storage overhead—not as a theorem about range scans.
Dynamic Pricing for Travel: The Model Is the Easy Part
Revenue management for travel — demand forecasting, price fences, the difference between dynamic and surge, and why published prices must be honoured.