Metadata Management: The Catalogue That Nobody Updates Until the Day They Need It
Schema registries, compatibility modes, ownership as data, and why a metadata system without enforced write paths becomes a documentation site.
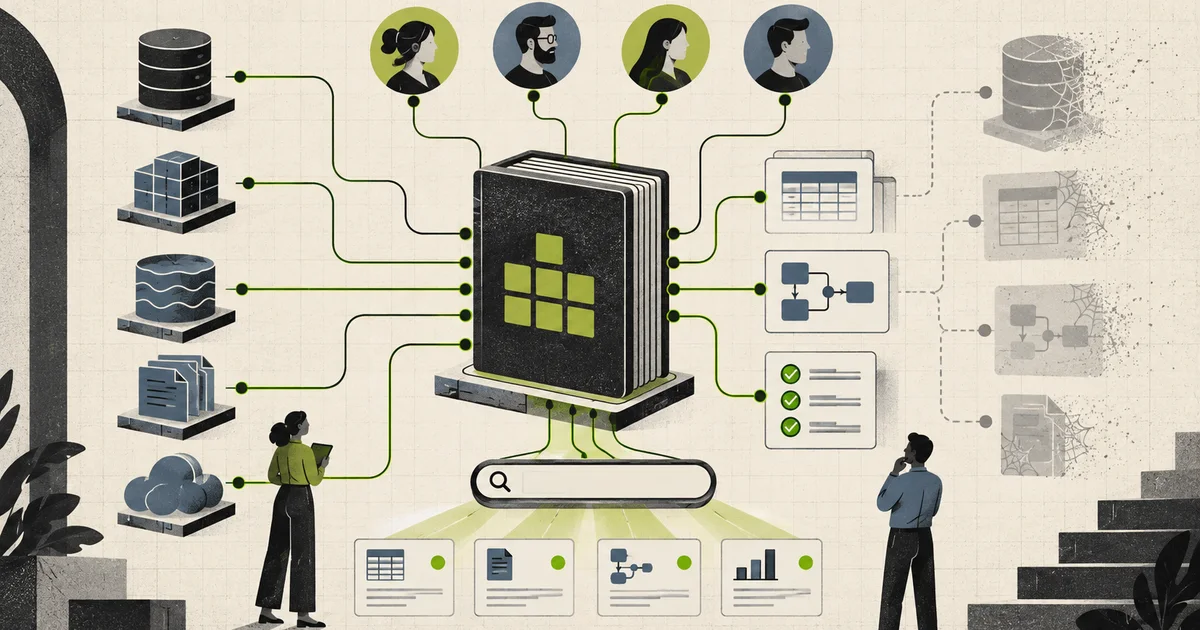
Every organisation eventually builds a data catalogue, and most of them end up in the same place: a wiki nobody updates, containing descriptions that are technically plausible and wrong in a way that only surfaces when a dashboard is quietly incorrect.
The reason is not that documentation is hard to maintain. It is that the catalogue is a second source of truth with no enforcement, and second sources of truth without enforcement become lies. The design decisions that fix this are about write paths, compatibility, and making the useful thing the easy thing.
The scale of what is being catalogued
  2,000 services
  50,000 database tables
  3,000 Kafka topics
  20,000 event schemas
  8,000 dbt models
  15,000 dashboards
  4,000 metrics definitions

  ~100,000 registered assets

  without a registry:
    a schema change reaches 50 consumers
    over the next 2 weeks, discovered individually
    -> ~200 compatibility incidents per quarter
The number that justifies the system is the second one. Schema incompatibility is a slow, expensive, recurring cost that is nearly invisible until a consumer breaks hours or days after a change, and the fix is to reject the change at the moment it is proposed rather than to find the consumers afterwards.
The three kinds of metadata, and only one of them is required
  technical metadata
    - field names and types
    - nullability, defaults, keys
    - producers and consumers
    - partition and ordering guarantees
    -> MACHINE-READABLE, ENFORCEABLE
    -> the part the system can guarantee

  business metadata
    - what the field means in the business
    - which team's metric this is
    - the definition of "active user"
    -> HUMAN, NOT ENFORCEABLE
    -> the part that makes it useful

  operational metadata
    - freshness, row counts, update frequency
    - owner, on-call, retention
    - downstream lineage
    -> PARTLY MACHINE-GENERATED
    -> the part that makes it trustworthy
Teams usually start by attempting the middle one and wonder why it does not work. “What does this field mean” cannot be validated by a system; it can only be recorded, requested, and reviewed. It is also the part that determines whether anyone uses the catalogue, because during an incident the engineer needs to know whether amount_cents is gross or net and no amount of type information tells them.
The correct order is: enforce technical metadata first, because the system can actually guarantee it, then generate operational metadata automatically, then solicit business metadata from the teams who own the data, and treat business metadata as a reviewed artefact with an owner rather than as a field someone might fill in.
Compatibility: three modes, and they are not equal
This is the most concrete thing the registry does and the thing teams most often configure wrongly.
  v1                          v2
  {                          {
    "id": "string",             "id": "string",
    "amount": "int"             "amount": "int",     <- new
  }                              "currency": "string" <- new
                              }
Backward compatibility: new consumers can read old data. A new version must be readable by consumers written against the previous version. Adding a field with a default is fine. Removing a field is not. Making an optional field required is not. Narrowing a type is not. Widening is.
Forward compatibility: old consumers can read new data. A new version must be readable by consumers written against the next version — which in practice means consumers that are older. This is the constraint that stops you removing a field: an old consumer expects it, and its absence is a break. Adding a field with a default is fine. Removing is not. Changing a type is not.
Full compatibility: both. Both directions safe, which for a shared event schema means every change is additive-with-defaults. This is the strictest mode and the correct default for anything crossing a service boundary, because you genuinely do not control the consumers’ deploy schedule.
Which mode to use, honestly:
  internal topic, all consumers in one team,
  all deployed together       -> none / backward
  internal topic, consumers
  deploy independently        -> full
  external or partner-facing  -> full, always
  database schema with a
  coordinated migration      -> none, with review
The failure mode is choosing none because “we coordinate our deploys” and then having one team that does not. Compatibility checking is cheap; a compatibility incident is a multi-day investigation with an unknown number of affected consumers. The asymmetry is not close.
One important caveat: compatibility checking is only as good as the schemas you register. If a producer writes a schema to the registry and then publishes something different, the registry is confidently wrong. That is why enforcing registration at the producer — the schema must be registered before the topic is written — is the whole value proposition, and why an unregistered producer is a registry that does not work.
Ownership as a first-class, enforced field
The most valuable metadata field is owner, and the reason it needs enforcement is that ownership decays silently.
  ownership decays like this
    team publishes a table       -> owner: team-a     (correct)
    team-a reorgs                -> owner: team-a     (wrong)
    6 months later               -> still team-a
    an incident                  -> page team-a
    team-a no longer exists      -> nobody responds

  enforcement that prevents it
    - owner is a required field, validated against
      a service catalogue, not free text
    - the owning team is verified on publish
      (they must authenticate as that team)
    - a reorg triggers a revalidation of
      everything they own
    - dashboards and alerts inherit ownership
      from the data they read
The interesting property is the last one. Ownership that lives only on tables is incomplete, because the thing a person needs at 2am is ownership of the dashboard, and the dashboard’s owner should be derived from the data behind it. Deriving it means ownership stays correct as the data changes underneath, which is exactly the case where hand-maintained ownership is always stale.
Lineage has to be captured, not documented
  table: billing_events
    written by:      kafka-consumer #4
    kafka topic:    billing.events.v2
    produced by:    billing-service (producer)
    upstream:       postgres.billing.ledger
                    stripe API (via payments-service)
    consumed by:    dbt model billing_daily
                    -> mart.finance_daily_revenue
                    -> dashboard "Finance Overview"
                    -> alert "Revenue flat"
Manual lineage of that shape is wrong within one quarter and nobody will update it. Machine-captured lineage is available at several points and all of them are better than documentation:
- Schema registry knows producers and consumers of topics, because they registered.
- Query engines know the DAG of transformations from the query plan, so a table’s upstream is derivable from the jobs that read and write it.
- dbt has a full lineage graph already, from static analysis of the model dependencies.
- Orchestrators know the task DAG of every pipeline.
- Data quality and observability tools know the runtime relationships from actual query traffic.
The practical approach is to assemble lineage from those sources rather than to introduce a place where people type lineage in. Runtime-derived lineage catches the dynamic dependencies that static analysis misses, and static analysis catches the ones that only happened to run last week.
The lineage feature that earns its cost is impact analysis: given a table, which dashboards, alerts, and models break if I change it. That is the question a schema change raises, and answering it from a lineage graph turns a week of discovery into a query.
Freshness and the trust problem
A catalogue entry with no freshness information is worse than no entry, because it looks authoritative.
  freshness signals, cheapest first
    - declared update frequency in the
      registration (a contract)
    - observed max(updated_at) in the data
    - observed write volume over a window
    - pipeline last-success timestamp

  the staleness signal people forget
    - the pipeline SUCCEEDED and produced
      the WRONG thing
    - freshness is green, correctness is not
The distinction in that last block is the one that makes data observability separate from metadata management. A pipeline that ran successfully an hour ago and has been silently truncating since is fresh and wrong. This is why the catalogue should carry a quality signal alongside a freshness signal, and why the two are displayed differently.
The derived rule for trust: show the last-updated time of the metadata entry itself, next to the last-updated time of the data. A description that says “average order value, excludes tax” where the definition changed eight months ago is actively harmful, and the only defence is making the metadata’s own age visible.
The catalogue as a deploy dependency
The adoption mechanism for schema registries is enforcement at the producer, and that means a deploy can be blocked on a catalogue check.
  deploy pipeline
      |
      v
  +---------------------------+
  |  producer registers the   |  must succeed
  |  schema BEFORE publish    |  -> this is the gate
  +------------+--------------+
               |
      compatibility check against
      the current registered version
               |
        pass  |  fail
              v     v
           deploy  reject with a
                   concrete diff and
                   the list of affected
                   consumers
Two consequences that need planning rather than discovering:
Registry availability is on the critical path of every deploy that touches data. If the registry is down, deploys block. This is a real availability dependency and it needs a considered answer — a cached compatibility snapshot, a local registry mirror, or an explicit degraded mode that allows deploys with a warning and reconciles later. Which you choose depends on how expensive a blocked deploy is relative to a bad deploy.
The error message is the adoption mechanism. A rejected schema that says “incompatible: removed field amount” is a fix in thirty seconds. One that says “COMPATIBILITY_CHECK_FAILED” is a ticket for the data team. The system should return the specific diff, the mode that failed, and the consumers affected, because a rejected deploy that does not explain itself gets a bypass added, and then the registry is advisory.
Failure stories worth testing
Register a schema, then publish something different
Confirm the registry rejects it. If it does not, the registry is documentation and you have lost the main benefit.
Remove a field with none compatibility selected
Confirm the deploy succeeds and consumers break over the following days. Then set the mode to full and confirm it is rejected with a useful message.
Add a field without a default and run full compatibility
Confirm it is rejected. An added field with no default breaks an old consumer that unmarshals strictly, and this is a common miss in otherwise careful schema reviews.
Reorg a team that owns 400 tables
Confirm the revalidation flow updates the owners. Ownership that is not revalidated is the decay path that produces an unpageable dashboard at 2am.
Change a table that nine dashboards read
Confirm impact analysis names all nine before the change is approved. If it cannot, the lineage was not captured from the pipelines.
Make a pipeline produce fresh but wrong data
Confirm the catalogue shows freshness green and quality bad, and that they are displayed separately. This is the failure that makes catalogues untrustworthy.
Take the registry down during a release window
Confirm what happens to in-flight deploys. A blocked deploy is annoying; a release freeze during an incident is not.
Reject a schema with an unhelpful message
Confirm the team’s response. This is the test for whether the error message is doing its job, and the usual outcome is a bypass.
Change a schema’s meaning without changing its structure
Rename nothing, change nothing in the type system, and the meaning changes anyway. Confirm the catalogue distinguishes the two, because only a human review catches the second.
Delete a table that an old version of a dashboard still queries
Confirm the deletion is blocked or warns with consumers. Unreferenced deletion is the one irreversible operation in a catalogue, and it needs a guard.
Have two teams register conflicting schemas for the same topic
Confirm the second registration is rejected. Last-write-wins in a schema registry is a silent correctness problem.
A production-ready architecture
   producers (services, streams, jobs)
        |
        |  register BEFORE publish
        v
  +-------------------------------+
  |  schema registry             |
  |  - versioned schemas          |
  |  - compatibility policy:      |
  |      backward / forward /full |
  |  - rejection returns the      |
  |    specific diff + consumers  |
  |  - owner required, verified   |
  |    against the service        |
  |    catalogue                  |
  +---------------+---------------+
                  |
     compatibility check gates
     every data-touching deploy
                  |
                  v
  +-------------------------------+
  |  catalogue                    |
  |  +------------------+         |
  |  | technical        |  types, keys, owners,
  |  | (enforced)       |  producers, consumers
  |  +------------------+         |
  |  | business         |  meaning, definitions,
  |  | (solicited,      |  reviewed with an owner
  |  |  owned)          |  and a visible entry age
  |  +------------------+         |
  |  | operational      |  freshness, quality,
  |  | (generated)      |  volume, last success
  |  +------------------+         |
  +---------------+---------------+
                  |
   lineage assembled from
   registry + query plans + dbt
   + orchestrator DAGs + runtime
   query traffic
                  |
                  v
  +-------------------------------+
  |  derived graph               |
  |  - upstream / downstream      |
  |  - impact analysis            |
  |  - ownership inherited by     |
  |    dashboards and alerts      |
  +-------------------------------+
A sensible delivery checklist:
- Enforce registration at the producer. A schema written but not registered makes every other feature advisory.
- Default to
fullcompatibility for anything crossing a service boundary. It is the strictest mode and the only one that respects consumers you do not deploy. - Make the rejection message a concrete diff plus the list of affected consumers. A rejected deploy that does not explain itself gets a bypass.
- Make
ownerrequired and validate it against the service catalogue rather than accepting free text. - Re-validate ownership on a reorg, automatically, and inherit ownership into dashboards and alerts from the data they read.
- Derive lineage from query plans, dbt, orchestrators, and the registry. Do not add a form for typing lineage.
- Build impact analysis, not just a graph. “What breaks if I change this table” is the question that makes the catalogue worth running.
- Show the entry’s own age next to the data’s age. A stale definition is worse than a missing one.
- Show freshness and quality as separate signals, because fresh and wrong is the common and invisible case.
- Decide how the registry behaves when it is down, before you need to, and prefer a cached compatibility snapshot to a deploy freeze.
- Review business metadata on a schedule, with the owning team, and treat a missing review as a defect.
- Guard deletion of registered assets with a lineage check. It is the one irreversible operation and the one most likely to be run in a hurry.
Common mistakes
| Mistake | What actually happens | Better decision |
|---|---|---|
| Optional schema registration | Producers skip it, registry is documentation | Enforce before publish |
none compatibility on a shared topic |
Consumers break days later, slowly | full across a service boundary |
| Rejection message is an error code | Teams add a bypass within a week | Concrete diff plus affected consumers |
owner as free text |
Unpageable ownership after a reorg | Validated against the service catalogue |
| Ownership hand-maintained per dashboard | Stale the moment the data changes | Inherit from the data, derive it |
| Manual lineage | Wrong within a quarter, never updated | Derive from query plans, dbt, orchestrators |
| Lineage without impact analysis | A graph nobody queries during a change | “What breaks if I change this” as a feature |
| No entry-age display | An eight-month-old definition looks authoritative | Show metadata age next to data age |
| Freshness as the only quality signal | Fresh and wrong passes every check | Separate freshness and correctness signals |
| Registry down blocks all deploys | Release freeze during an incident | Cached compatibility snapshot, degraded mode |
| Business metadata with no review | Meaning drifts, definitions conflict | Owner review on a schedule |
| Deleting an asset with no lineage check | A dashboard queries a table that is gone | Guard deletion with a consumer check |
| Last-write-wins on schema registration | Two teams, two truths, one silent break | Reject the conflicting registration |
| Cataloguing only tables | The dashboard a human needs has no entry | Catalogue dashboards and alerts too |
| Technical metadata only | Precise and useless during an incident | Solicit business meaning with an owner |
| No schema history | Cannot answer “when did this field appear” | Full version history, queryable |
| One catalogue for everything | Nobody can find their layer | Federate, link, or filter by domain |
| Metadata as a nightly export | Always a day stale, never authoritative | Read from the source systems, live |
The complete story in one minute
A metadata system fails in a predictable way: it becomes a second source of truth with no enforcement, and second sources of truth without enforcement become lies. The fix is to make the correct write path the path of least resistance — producers must register a schema before they publish, and a deploy that would break an existing consumer is rejected at proposal time rather than discovered days later by the consumer.
Three kinds of metadata need different treatment. Technical metadata is machine-readable and enforceable, so the system can guarantee it. Business metadata — what a field actually means, whether amount_cents is gross — cannot be validated by any system and is the part that makes a catalogue worth opening during an incident, so it needs a named owner and a review. Operational metadata is mostly generated and is what makes the entry trustworthy.
Compatibility is the concrete payoff. Backward protects new consumers from old data, forward protects old consumers from new data, and full is both. Anything crossing a service boundary should be full, because you do not control your consumers’ deploy schedules, and the asymmetry is not close: a compatibility check costs seconds, a compatibility incident costs days with an unknown blast radius.
Lineage must be captured from the pipelines that produce data — query plans, dbt, orchestrator DAGs, registry registrations — because hand-maintained lineage is wrong within a quarter. And the feature that earns the whole system’s cost is impact analysis: given a table, which dashboards, alerts, and models break if I change it.
Finally, the catalogue becomes a deploy dependency the moment you enforce it, which is a real availability dependency. Decide what happens when the registry is down before you need to, and make the rejection message good enough that nobody is tempted to add a bypass.
register before publish, or the registry is a wiki
compatibility: full across service boundaries
lineage: captured from pipelines, never typed
trust: metadata age + data age + freshness + correctness, all visible
The hard part was never storing the schemas. It was making the catalogue the only place the truth lives, instead of the place where someone once wrote down what they believed.
Technical references
Related notes.
Data Mesh Architecture: Four Principles and the Organisation Chart Hiding Inside Them
Domain ownership, data as a product, the federated plane, and why data mesh is a reorganisation with an API in front of it.
Travel Review Platform: Moderation, Fraud, and the Recency Problem
Running a travel review platform at scale — review eligibility, fraud detection, ranking that resists gaming, and the moderation workflow that makes it trustworthy.
CockroachDB from First Principles: The Database That Refuses to Die
Why a global SQL database is really a problem of agreement and time, how Google solved it with TrueTime, GPS, and atomic clocks, and how CockroachDB reaches a practical design on ordinary infrastructure.