Ride Matching Algorithm: Batching, Detours, and the Trade-off Every Marketplace Rediscovers
How ride matching actually works — spatial partitioning, ETA matrices, batch windows, and why lowest-detour and shortest-wait pull in opposite directions.
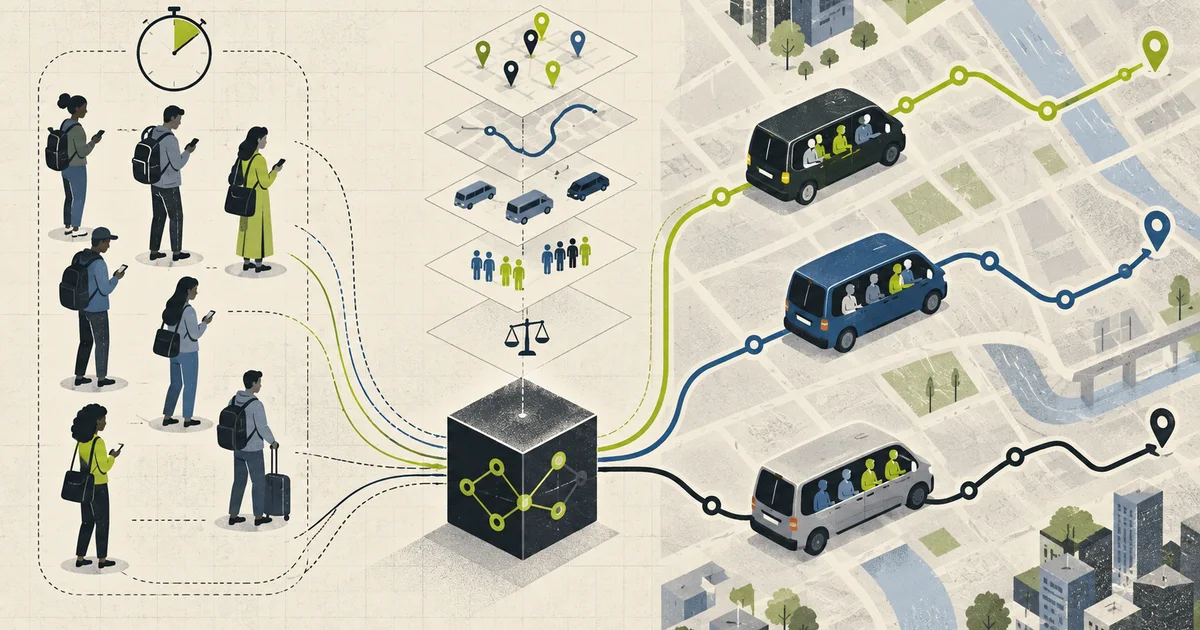
A ride matching algorithm sounds trivial: a rider wants a car, a driver is nearby, pair them up. The reason it is one of the hardest pieces of real-time software is that the obvious algorithm is bad, the fix for the obvious algorithm is worse, and the fix for that has a parameter that cannot be tuned independently of city, time, and supply.
The scale
  a large city, peak hour
    12,000 drivers online
    40,000 open requests per hour
    ~11 requests per driver per hour
    1 request every 90 seconds system-wide

  matching must run
    - continuously
    - over the whole city, every few seconds
    - with a result the driver sees within seconds

  the naive scan
    40,000 requests x 12,000 drivers
    = 480,000,000 pairs
    per matching cycle
480 million pairs per cycle is not a scan anyone can run. And the reason it is not a scan anyone should run is subtler than performance: most of those pairs are absurd. A rider in one borough should never be considered for a driver in another, and the naive comparison spends almost all its time evaluating pairs that a single distance filter would have rejected.
The problem, stated properly
  given
    requests  R = {r1..rn}   with pickup, dropoff, timestamp
    drivers   D = {d1..dm}   with position, heading, availability
    ETA(a, b)                travel time from a to b

  produce
    a matching: each request -> at most one driver
                each driver  -> at most one request

  minimise
    total = sum over matched pairs of
            ( driver idle time
            + rider wait time
            + DETOUR COST )
The third term is where real implementations differ from textbook ones. Minimising wait and idle alone produces matches that are individually defensible and systemically awful, because both terms are evaluated only for the matched pair and neither accounts for the second trip the driver has to make to collect the rider.
Detour, quantified
  driver is at A, heading toward D (their own goal)
  rider pickup is at P, 200m off that line

  driver ETA to rider : 4 min
  rider's own trip     : 12 min
  total driver time   : 16 min

  but the driver would have arrived at D
  in 6 min without the pickup

  real cost of the match
    = 4 min collected + 2 min detour
    = the driver spent 2 extra minutes
      for a $6 fare

  scaled
    300,000 rides/day
    2 min average extra
    = 10,000 driver-hours/day of pure detour
The mechanism that fixes this is comparing against the driver’s empty-route baseline: the time the driver would have taken to reach their next objective without this pickup. A match is only good if its total cost beats the counterfactual, and a small detour relative to a short trip is often a bad deal for the driver even when the rider waits less.
A concrete comparison used in production:
  accept a match if
    rider_pickup_eta + rider_trip_duration
    <
    (1 + tolerance) x (driver_eta_to_own_next_stop)
The tolerance is what makes it work. Set it too tight and drivers reject matches; set it too loose and you are back to minimising only the rider’s wait. This single multiplier is the most sensitive parameter in most ride systems, and it should be tuned per city and per time of day.
Batching, and why the window is everything
  no batching: match immediately on arrival
    rider waits: lowest possible
    match quality: worst possible
      - a driver 300m away might be
        gone in 4 seconds
      - a driver 900m away, 20s away,
        heading the right way: missed
    driver idle: high (immediate means grabbing
                 whatever is closest)

  long batching: wait 8 seconds
    rider waits: +8s, often
    match quality: much better
      - all nearby drivers and all
        nearby requests visible together
    driver idle: lower
    match rate: higher (fewer requests time out)

  why it works
    batching converts a stream of
    independently-decided pairs into
    a small assignment problem, and small
    assignment problems have good optima
The window is the trade-off knob and its optimal value is a function of supply density, not of your product preferences. Dense downtown at rush hour: a short window, because drivers are abundant and a long one just adds wait for no matching gain. Suburban at 3am: a long window, because requests and drivers are sparse and waiting is the only way to find a pair at all. Airport arrivals at a scheduled time: a long window, because the batch of arriving passengers is known in advance and matching them together beats dispatching individually.
Two implementations matter:
Time-based batching. Fixed window, e.g. every 5 seconds. Simple, predictable, and easy to reason about latency. The cost is that under low density, a request may arrive 1ms after a window closed and wait a full window for nothing.
Global idle-time window. Match when the oldest request has waited longer than the window OR a good-enough match exists. This is adaptive: during peaks the quality trigger fires early, and during troughs the time trigger fires. It costs more bookkeeping and it is worth it — the alternative is one window value that is wrong for half the day.
Bounding the search
  +----------------------------------------------------+
  |  H3 hexagon grid, resolution 9                      |
  |  ~0.1 km^2 cells, ~1.2km across                     |
  +----------------------------------------------------+
        |
        v
  for a new request at cell X
    1. look at cell X and its ring neighbours
       (1, 3, 7, or 19 cells by radius)
    2. request->driver and driver->request
       ETAs are precomputed per cell pair
    3. beyond the ring, the fallback is a
       sparse-index query (not a scan)
        |
        v
  candidate set: tens to low hundreds
  assignment over the candidate set only
The grid is not the clever part; the precomputed ETA matrix between cells is. Rather than routing every candidate pair through a routing engine, you compute travel time between cell centres once and cache it, plus per-cell adjustment factors for the actual pickup point. Exact routing runs only on the final handful of selected pairs.
Ring expansion order matters for a reason people miss: expanding by ring means the candidate set grows in distance bands, so you can stop as soon as the ring’s best possible match cannot beat the current best. That turns “search more” into “stop early” and it is where most of the latency reduction comes from.
The algorithm
  every matching cycle (or on batch close)

  1. gather
     open requests not yet matched
     available drivers not yet assigned

  2. bound
     index both by H3 cell
     for each request, expand rings until
       the best candidate in the last ring
       is worse than the current best match
       (or the ring limit is hit)

  3. build bipartite graph
     edge (r, d) exists if
       pickup ETA < rider max wait
       AND detour acceptable to driver
       AND driver has capacity
     edge cost =
         w1 * pickup_eta
       + w2 * (pickup_eta + trip_eta
               - driver_free_eta)     <- detour
       + w3 * expected_idle_after

  4. solve
     min-cost bipartite matching
     (Hungarian for small sets;
      auction algorithm / min-cost flow
      for larger; greedy-with-swaps
      when latency is tightest)

  5. publish, then post-process
     - notify matched pairs
     - unmatched requests stay open
     - matched drivers removed from pool
     - re-optimise later for remaining
Step 4 is where implementations diverge, and the choice is usually about the candidate set size. For a batch of 50 requests and 200 candidates in a dense area, Hungarian is fast enough and gives the true optimum. In a sparse area where the graph is larger and the deadline tighter, an auction algorithm or greedy-with-swap-pairs gets most of the benefit at a fraction of the cost. Greedy matching (best pair first, remove, repeat) is a reasonable baseline and the thing most teams ship first, so measuring its gap against Hungarian is the most valuable single benchmark in the system.
Fairness and driver distribution
  pure cost optimisation
    -> the same 2,000 drivers get every
       downtown request
    -> the other 10,000 idle downtown
    -> when those 2,000 finish, the
       rest of the city has no supply
       because nobody was there

  the metric that matters
    Gini coefficient of driver earnings
    and the p10 driver income, not just
    mean utilisation
A cost-optimal matcher is a supply-concentration engine, and the result is that supply collapses exactly when demand spikes elsewhere. Two mitigations that are easy to add:
Earnings-floor routing. When evaluating driver supply for a request, weight the candidate set by an earnings multiplier that grows for drivers below a target hourly rate. Costs change, match quality changes slightly, distribution improves substantially.
Idle-time bonus in the objective. Add a small negative cost for matching a long-idle driver, which pulls requests toward drivers who have been waiting. It is a tiny change to the objective and it is very effective, because it exploits a resource that is otherwise free.
Cancellation is an algorithm output
  rider cancels: driver arrived at pickup
  root causes, roughly in order
    - wait was longer than expected
      (the ETA was optimistic or traffic moved)
    - the match was poor: wrong vehicle type,
      long detour visible in the ETA, bad pairing
    - the driver's rating or car was not
      what the rider expected
    - price changed at confirmation

  driver cancels
    - the pickup ETA was wrong when accepted
    - the trip is too short for the detour

  what this means
    cancellation rate is a MATCH QUALITY metric
    and it is one of the strongest leading
    indicators of future supply
Cancellation is usually treated as an exception to be minimised with policy. It is better treated as a measurable property of the matcher, because it is downstream of exactly the trade-offs the algorithm is making. If you increase the driver tolerance to lower rider wait times, expect cancellations to rise. If you batch longer, expect ETA-at-pickup accuracy to improve and cancellations to fall. Every parameter has a cancellation shadow.
The strongest practical intervention: a rider-side ETA that accounts for the actual matched driver, not the nearest-driver average. Riders tolerate a 6-minute wait they were told about; they do not tolerate a 6-minute wait they were told would be 3.
Failure stories worth testing
Set the batch window to 30 seconds in a dense downtown at rush hour
Measure wait times and match rate. Wait will look acceptable, match quality will be great, and the acceptance and cancellation rates will tell you whether riders and drivers tolerate it.
Set the window to 0 (immediate matching) system-wide
Match rate collapses and driver idle time rises. This is the counterfactual that makes the window defensible.
Greedy-match a batch, then re-run Hungarian on the same batch
Measure the cost difference. Usually 3-8%, which is the number to argue with when someone proposes removing the assignment step.
Remove the detour term from the edge cost
Driver acceptance falls, driver earnings spread narrows, and long pickups to short trips rise. The detour term is not optional.
Expand rings until all candidates are exhausted instead of stopping early
Compare latency. The early-stop rule is where the speed comes from.
Replace precomputed cell-to-cell ETAs with live routing for every pair
Measure p99 matching latency. This is the change that turns a 200ms cycle into a 4s one.
Turn off the idle-time bonus
Watch the p10 driver income. Utilisation looks stable; distribution degrades within a day.
Add an earnings-floor multiplier for bottom-quartile drivers
Measure overall utilisation cost. The efficiency hit is usually under 1%; the retention benefit is not.
Route everything to the top 2,000 drivers downtown for one evening
Watch the next morning’s citywide response time. This is the supply-collapse experiment and it is dramatic.
Publish a fixed 4-minute pickup ETA regardless of the matched driver
Cancellation rate goes up specifically among riders who had a 7-minute actual wait. The promise, not the wait, is the problem.
Make traffic spike 3x in one zone
Confirm the candidate set shrinks toward fast roads and that the ring-stop rule does not cut off supply that is actually closer than it appears.
Give two drivers identical positions and availability
Check the tie-breaking. Without deterministic tie-breaks you will see flaky reassignment and duplicated notifications.
Drop the pickup-radius expansion and match only within the rider’s cell
Match rate halves at the edges of the city. Bounding too tightly is a real failure mode, not just a missed optimisation.
Run matching on stale driver positions (30s old)
Measure cancellation and driver-side rejections. Stale positions produce matches that are already wrong by dispatch time.
A production-ready architecture
   driver location stream (every 2-5s)
        |
        v
  +----------------------------------------------------------+
  |  LOCATION INGEST + STATE                               |
  |  - H3 cell assignment per driver                        |
  |  - availability, heading, vehicle type                  |
  |  - last-seen with TTL expiry (drop stale)                |
  +----------------------------+-----------------------------+
                               |
   request arrives
        |
        v
  +----------------------------------------------------------+
  |  REQUEST QUEUE with batch semantics                     |
  |  - window by global idle time or quality trigger        |
  |  - separate queues per batch key (city / airport / geo)  |
  +----------------------------+-----------------------------+
                               |
                               v
  +----------------------------------------------------------+
  |  MATCHING CYCLE                                          |
  |  - candidate generation: rings + early stop              |
  |  - edge build: ETA + detour + idle-bonus costs          |
  |  - solve: Hungarian / auction / greedy-with-swap         |
  |  - fairness reweighting for low-earner drivers          |
  +----------------------------+-----------------------------+
                               |
                               v
  +----------------------------------------------------------+
  |  DISPATCH + EXPECTATION                                 |
  |  - notify rider and driver                               |
  |  - per-driver pickup ETA (not a fleet average)           |
  |  - publish tentative status to the map                   |
  +----------------------------+-----------------------------+
                               |
                               v
  +----------------------------------------------------------+
  |  FEEDBACK LOOP                                           |
  |  - actual wait, driver-reported detours                 |
  |  - cancellations by cause                                |
  |  - acceptance/rejection by driver                        |
  |  - recalibrate ETA model on a rolling window             |
  +----------------------------------------------------------+

  watch: match rate, median wait, p90 wait, cancellation by
        cause, driver acceptance rate, earnings Gini,
        supply distribution by zone
Delivery checklist:
- Implement the matching cycle as a bounded-candidate-set assignment problem, not a global scan.
- Bound geography with an H3 grid and precompute cell-to-cell travel times. Route exactly only the final pairs.
- Add an early-stop rule to ring expansion based on the best candidate in the current ring.
- Include the detour term, measured against the driver’s empty-route baseline, with a tunable tolerance.
- Make the batch window adaptive: idle-time triggered, not a single fixed value.
- Use per-driver pickup ETAs in the rider promise, computed from the actual matched driver.
- Add the idle-time bonus and an earnings-floor reweighting, and monitor distribution metrics, not just mean utilisation.
- Instrument cancellation by cause and treat it as a match-quality signal.
- Benchmark greedy against Hungarian on a real batch and record the gap as a business number.
- Expire stale driver state with a TTL. A driver who went offline 40 seconds ago is not available.
- Separate batch keys by geography and trip type so airport and city demand do not compete.
- Make tie-breaking deterministic. Non-determinism shows up as flaky reassignments.
- Recalibrate the ETA model on a rolling window rather than assuming the map is static.
- Log every match decision with the full candidate context; matcher regressions are otherwise unreproducible.
Common mistakes
| Mistake | What actually happens | Better decision |
|---|---|---|
| Greedy nearest-driver matching | 3-8% worse cost, and invisible in aggregate | Assignment over the candidate set |
| No detour term | Drivers reject good-looking matches | Detour vs empty-route baseline |
| Ignoring the batch window | Either bad waits or bad matches | Adaptive, idle-time-triggered window |
| Global scan for candidates | Unaffordable latency, most pairs absurd | H3 rings with early stop |
| Live routing per candidate pair | p99 latency in seconds | Precomputed cell-to-cell ETAs |
| A fixed ETA promise for all riders | Cancellations among long waits | Per-driver pickup ETA |
| Cost-only objective | Supply collapses where it is not optimised | Idle-time bonus, earnings floor |
| Ignoring cancellation causes | A tuning knob regresses, nobody knows why | Cancellation by cause, as a match-quality metric |
| Optimising mean utilisation | Tail drivers churn, supply thins | Gini and p10 income |
| Ring expansion without early stop | Full expansion every cycle | Best-in-ring stop rule |
| Batching by city only | Airport and downtown demand compete | Per-geography batch keys |
| Stale driver state | Matches that are already wrong at dispatch | TTL expiry on availability |
| Non-deterministic tie-breaks | Flaky reassignments, duplicate pings | Deterministic ordering |
| Optimising only rider wait | Driver-side churn | Objective with driver acceptance term |
| Cold-start city with no ETA cache | Everything is slow until the cache fills | Pre-seed the cache per market |
| Caching ETAs forever | Stale traffic, worsening promises | Rolling refresh with traffic layer |
The complete story in one minute
Ride matching is a min-cost bipartite assignment problem, not a nearest-neighbour loop. The naive global scan is 480 million pairs per cycle, and even a fast scan is wrong because the objective that matters includes detour — the extra time a driver spends collecting a rider relative to their own next stop. A 200-metre pickup detour is invisible to both parties and costs a real city-scale sum of driver hours. Fix it by comparing each match against the driver’s empty-route baseline, with a tolerance multiplier that is the most sensitive parameter in most systems and must be tuned per city and per hour.
Batching is the trade-off knob. Longer windows mean better matches and worse waits, and the optimum depends on supply density, not preference. Use a global idle-time trigger rather than a fixed window so it adapts between peak and trough. Bound the search with an H3 grid and precomputed cell-to-cell travel times, expand rings outward, and stop as soon as the current ring’s best cannot beat the best match — the early-stop rule is where the latency comes from. Route exactly only the final pairs.
A cost-only matcher is a supply-collapse engine: it sends every downtown request to the same two thousand drivers, and the next morning the rest of the city has nobody. Add an idle-time bonus and an earnings-floor reweighting and monitor the Gini and the p10 income, not mean utilisation. Treat cancellation as a matcher output rather than an exception — it is the leading indicator of future supply, and it moves predictably with every parameter you change. And give each rider an ETA computed from the driver they were actually matched with: riders forgive a six-minute wait they were told about, and never forgive one they were promised would be three.
assignment, not greedy; detour vs empty-route baseline
adaptive batch window; H3 rings with early stop; cached cell ETAs
per-driver ETA promises; idle-time bonus and earnings floor
cancellation as a match-quality signal
The hard part was never finding the closest driver. It was deciding when not to match, and paying attention to what the match costs the person driving.
What this team still owns
Candidate generation, travel-time estimation, assignment, offer delivery, and driver acceptance are separate clocks. Record the snapshot and objective used for each match, expire offers, and make acceptance a conditional transition so two riders cannot acquire the same driver. Optimise predicted pickup time and system consequences—not straight-line distance—and keep cancellation, earnings, accessibility, and geographic-service metrics beside conversion so the objective cannot quietly externalise cost onto drivers or neighbourhoods.
Technical references
Related notes.
Waze-Style Navigation at Scale: Routing Engines, Map Matching, and the Traffic Model
Building navigation at map scale — road-graph routing, map matching from GPS traces, live traffic estimation, and incremental rerouting.
Last-Mile Delivery System: The Problem That Is 80% Small Talk and 20% Optimisation
Last-mile delivery route design, density-based territory planning, failed delivery recovery, and the operational details that dominate the economics.
Driver Dispatch System: Assigning Work When the Vehicle Is Not the Constraint
Freight dispatch with capacity, hours-of-service, and multi-depot realities — the parts of dispatch that a load board does not solve.