Soft Deletes: Why a Unique Constraint Cannot Span a Column You Can Change
A soft-deleted row still holds its unique value, so the second registration of the same email fails on a constraint nobody expected to fire. The fix is a partial index, and the decision about whether to use one is upstream of that.
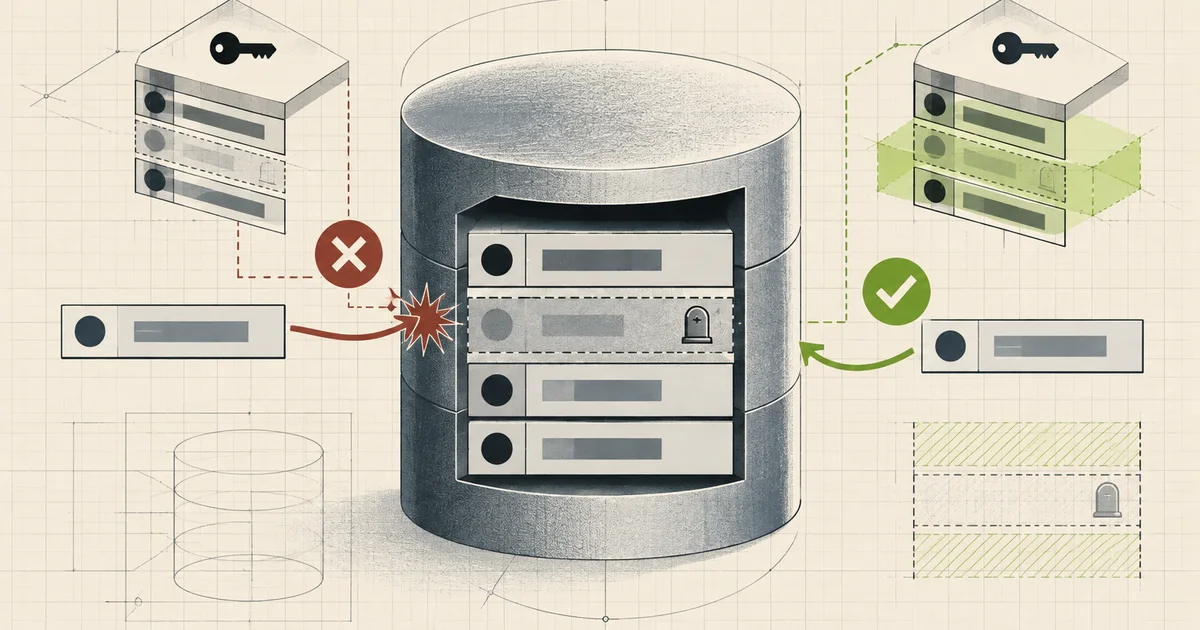
A soft delete is one nullable column and a filter. The implementation takes an afternoon, it works on the first day, and it produces a bug report some months later that reads like a mystery because the cause is a constraint that was correct when it was created.
The cause is that a soft-deleted row is still a row, and it still holds the value you made unique.
Every fix is a schema decision rather than a query decision, and each one is a small, permanent cost. A partial unique index puts the predicate in the index and leaves the table alone, which is the closest thing here to a free fix, but it means your uniqueness now has to be re-stated every time the predicate changes. A nullable unique column and COALESCE works in older engines, and moves the problem to the second write instead. The version that looks free at review time is a WHERE clause in application code, which fails the moment two services write the same table without a shared library. If you are already storing a document for the record, the same trade-off shows up as JSONB and deferred schema.
The bug that happens on the first re-registration
CREATE TABLE users (
    id         bigint PRIMARY KEY,
    email      text NOT NULL,
    deleted_at timestamptz,
    UNIQUE (email)
);
// registration
if (await _db.Users.AnyAsync(u => u.Email == email, ct)) throw new EmailTaken();
_db.Users.Add(new User { Email = email, DeletedAt = null });
await _db.SaveChangesAsync(ct);The application check makes this look correct, because the application queries with a deletion filter and therefore does not see the deleted row.
  timeline

    t=0    register ada@example.com      -> row A, deleted_at = null
    t=1    delete ada@example.com        -> row A, deleted_at = now()

    t=2    register ada@example.com
            app check: AnyAsync(Email == ...)
              -> global filter excludes row A
              -> returns false
              -> proceeds to insert
            database: UNIQUE (email) sees row A
              -> duplicate key value violates unique constraint
The application says the email is available and the database says it is not, and both are correct, because they are looking at different sets of rows. The failure is immediate and total: every re-registration after a deletion fails, for every email, forever, until someone hard-deletes the old row.
It is worth being clear that the fix is not “add a filter to the insert check”. The check is already filtered. The uniqueness guarantee lives in the database, applies to the physical row, and there is no way to scope a plain unique constraint to a predicate.
The four workarounds
There are four ways people address this. Two are wrong, one is a workaround with a cost, and one is the answer.
Overwriting the value on delete. Append a tombstone so the old row no longer collides.
UPDATE users
SET email = email || '+deleted-' || id::text,
    deleted_at = now()
WHERE id = 88123;
It works and it is a mistake. The email is now wrong on the row, restoring the user leaves you with a corrupted address, and any support process that looks up a deleted user by email finds nothing. You have also made the deleted row useless for the audit purpose that justified the soft delete in the first place.
Adding the flag to the constraint. This is the intuitive fix and it fails in a way that is worth understanding.
ALTER TABLE users DROP CONSTRAINT users_email_key;
ALTER TABLE users ADD CONSTRAINT users_email_deleted_key UNIQUE (email, deleted_at);
In a unique index, null values are distinct from each other by default. Two rows with email = 'ada@example.com' and deleted_at = NULL are not a conflict, because in the index they are (ada@example.com, NULL) and (ada@example.com, NULL), and the index only treats entries as equal when every component is equal and no component is null.
  UNIQUE (email, deleted_at), both live rows

    (ada@example.com, NULL)
    (ada@example.com, NULL)
      -> not a conflict, because NULL is not equal to NULL

    so the live-row guarantee is gone entirely
You did not add a deletion-aware constraint. You removed the uniqueness guarantee from the rows that actually needed it, and left it in place only for the tombstoned rows, where it is worthless. This is the most common wrong answer, because it looks right in review.
Postgres 15 has the missing piece, which is worth knowing if you read the manual for a version older than that and conclude the approach is impossible rather than merely unfinished.
-- Postgres 15 and later
ALTER TABLE users ADD CONSTRAINT users_email_deleted_key
  UNIQUE NULLS NOT DISTINCT (email, deleted_at);
This makes (email, NULL) collide with (email, NULL), so live rows are protected. Deleted rows can repeat an email only when their deleted_at values differ; two tombstones with the same email and timestamp still conflict. That makes the composite constraint a representation-dependent workaround, not the clearest statement of “unique among live rows.” A partial unique index expresses that predicate directly.
A separate active column. Keep a nullable column that is populated only while the row is live, and put the unique constraint on that.
ALTER TABLE users ADD COLUMN active_email text;
CREATE UNIQUE INDEX idx_users_active_email ON users (active_email);

-- on create
INSERT INTO users (email, active_email) VALUES ('ada@example.com', 'ada@example.com');

-- on delete
UPDATE users SET active_email = NULL, deleted_at = now() WHERE id = 88123;
This works everywhere including engines with no partial indexes, and it is portable. Its cost is that uniqueness is now maintained by convention: any insert that forgets to set active_email is unprotected, and there is nothing in the schema that prevents that. A trigger or a generated column closes the gap.
A partial unique index. This is the answer.
-- drop the table-level constraint, which cannot express this
ALTER TABLE users DROP CONSTRAINT users_email_key;

CREATE UNIQUE INDEX idx_users_email_live
    ON users (email)
    WHERE deleted_at IS NULL;
The index contains only live rows, and uniqueness is enforced across exactly them. Deleting a row removes its entry from the index as part of the update, so the value becomes free. The intent is stated once, in the schema, and it applies to every write path including psql, a migration, a data import, and a teammate who forgot the filter.
  the semantics you actually wanted

    UNIQUE (email)                  all rows, forever  -> wrong
    UNIQUE (email, deleted_at)      live rows unguarded -> worse
    UNIQUE NULLS NOT DISTINCT (...) protects live rows, but also compares tombstone timestamps
    UNIQUE (email) WHERE deleted_at IS NULL
                                   direct PostgreSQL expression
Support is engine-specific. PostgreSQL calls it a partial index and SQL Server a filtered index. MySQL has no index predicate, so derive an expression that becomes NULL for deleted rows and place a unique index on that expression or generated column.
-- SQL Server
CREATE UNIQUE INDEX idx_users_email_live ON users (email) WHERE deleted_at IS NULL;

-- MySQL: no partial indexes, so derive a column that is NULL when deleted
ALTER TABLE users
  ADD COLUMN active_email varchar(320)
    GENERATED ALWAYS AS (IF(deleted_at IS NULL, email, NULL)) STORED,
  ADD UNIQUE KEY idx_users_active_email (active_email);
The predicate has to reach every query
The index fixes the constraint. It does nothing about the other half, which is that every read now needs WHERE deleted_at IS NULL or it will return rows the application believes are gone.
-- correct
SELECT * FROM users WHERE deleted_at IS NULL AND id = 88123;

-- returns the ghost
SELECT * FROM users WHERE id = 88123;
A query that forgets the predicate is a privacy incident rather than a bug report, because the row is exactly what the application promised was deleted.
There is a performance detail here that catches people. For the planner to use a partial index, it has to prove that the query’s predicate implies the index’s predicate. That works when the predicate is a literal.
-- the planner can use idx_users_email_live: the predicates match
SELECT * FROM users WHERE email = 'ada@example.com' AND deleted_at IS NULL;

-- a generic prepared plan cannot prove this parameter means the index predicate
PREPARE find_user(text, boolean) AS
SELECT * FROM users
WHERE email = $1 AND (deleted_at IS NULL) = $2;
With a parameter the predicate no longer implies deleted_at IS NULL, so the partial index is not applicable and the plan falls back to a scan. If you filter by a flag from the application, either the query needs two clearly separated paths or the flag should not be a parameter on that query.
Global filters and the ways around them
EF Core’s global query filter is the ergonomic way to make the predicate reach every query, and it is a good default.
modelBuilder.Entity<User>(b =>
{
    b.HasQueryFilter(u => !u.IsDeleted);
    b.HasIndex(u => u.Email)
     .IsUnique()
     .HasFilter("\"deleted_at\" IS NULL")
     .HasDatabaseName("idx_users_email_live");
});
The HasFilter on the index is the same partial index expressed in the model, so a migration produces it and the two cannot drift.
Global filters also interact with relationships. EF applies the User filter when that entity participates in a query, including an Include. With a required navigation it may use an inner join, so filtering the deleted principal can unexpectedly remove the parent Order from the result rather than materialize a deleted customer.
// the User filter participates in the join; a required navigation can
// cause the Order itself to disappear when its Customer is filtered out
var orders = await _db.Orders
    .Include(o => o.Customer)
    .ToListAsync(ct);
There is a second gap that matters more in practice: any query that needs the deleted rows has to opt out explicitly, and the opt-out is one method call away from being used where it should not be.
// reads the deleted rows, which is sometimes exactly what you want
var tombstones = await _db.Users
    .IgnoreQueryFilters()
    .Where(u => u.IsDeleted)
    .ToListAsync(ct);
A dedicated method on a repository, named for the intent, is worth more here than the filter itself, because it makes the bypass a deliberate, reviewable act rather than something a future contributor adds while debugging.
Data growth and what “soft” actually means
The second cost of the pattern is that nothing is ever removed, and the table size is the leading indicator of a problem nobody is measuring.
  a hard-deleted table

    rows:      peak live count
    indexes:   proportional to rows
    vacuum:    cheap, steady state

  a soft-deleted table, two years in

    rows:      every row ever created
    indexes:   same, because indexes do not know about soft delete
    vacuum:    each soft delete creates one obsolete row version;
               the replacement tombstone remains a live tuple
    backup:    includes rows the business no longer wants
The index point is the one that is often missed. Soft-deleted rows stay in their indexes, so a query that only wants live rows has to walk past them, and the partial unique index is small while every other index on the table keeps growing.
An UPDATE that marks a row deleted creates an obsolete old tuple version and a new live tombstone. Autovacuum can reclaim the obsolete version once snapshots allow it; it does not reclaim the tombstone, because that row is still live to PostgreSQL. The long-term cost is retained live rows and their index entries, plus ordinary update churn—not a permanently high n_dead_tup ratio caused by the tombstones themselves.
SELECT relname,
       n_live_tup, n_dead_tup,
       round(100.0 * n_dead_tup / nullif(n_live_tup + n_dead_tup, 0), 1) AS dead_pct,
       last_autovacuum
FROM pg_stat_user_tables
ORDER BY n_dead_tup DESC
LIMIT 20;
If the retention requirement is genuinely “we may need this row in ninety days for an audit”, the honest structures are an archive table with a scheduled move, or a history table that the live row points at, or a real temporal table where the engine maintains the history for you. A nullable timestamp on the live table implements none of those and pays for all of them.
Restoring is where the design shows
Undelete reads like the inverse of delete and is not, because time has passed and the world has moved.
  delete, then the value is reused, then restore

    t=0   user A: ada@example.com            live
    t=1   user A deleted
    t=2   user B registers ada@example.com   live
    t=3   restore user A

    with UNIQUE (email) WHERE deleted_at IS NULL
      -> the index entry for A's email must now be inserted
      -> user B already holds it
      -> unique violation on the restore
The restore is a data conflict wearing a different hat, and how you resolve it is a product decision that gets made in an incident if it was not made in advance. The three answers are refuse the restore, transfer the account, or release the new registration, and each of them is a conversation with a support team.
Any soft-delete design needs that answer written down. It is a small piece of work that prevents a class of incident where the user has deleted the account, someone else has taken the identity, and an admin is asked to reconcile two accounts that both claim the same email.
A production-ready architecture
  the row is being removed
        |
        v
  is there a retention or legal requirement for it?
        |
   +----+----------------------------------+
   | no                                   | yes
   v                                      v
  DELETE the row                       what is actually required?
  smaller, faster, honest               audit trail? -> archive or
                                        history table
                                        legal hold? -> the row must
                                        stay, and so must its
                                        uniqueness
   +-------------------------------+         |
   | for the surviving case:      |         v
   +-------------------------------+   retention window
     |                             |   archive after N days
     v                             |   purge the archive separately
  +---------------------------------------------+
  | UNIQUE (col) WHERE deleted_at IS NULL       |
  |  -- the guarantee applies to live rows      |
  | every read carries the predicate            |
  |  -- global filter, and it has gaps          |
  | partial indexes for the reads that matter   |
  | restore is a conflict, with a written rule |
  | rows are actually purged, and measured      |
  +---------------------------------------------+
A delivery checklist:
- Replace every table-level unique constraint on a soft-deleted table with a partial unique index over live rows.
- Do not add the deletion flag to the unique constraint. It removes the guarantee from the rows that need it.
- Express the partial index in the ORM model so a migration produces it and the schema and the model cannot drift.
- Audit reads for a missing predicate, treating each as a data exposure rather than a bug.
- If a flag is passed as a parameter, verify the planner can still use the partial index; it cannot prove the predicate matches.
- Check navigation property loads in the ORM, since a global filter on the principal does not apply to the dependent’s query.
- Confine the filter bypass to named methods rather than letting
IgnoreQueryFiltersbe available anywhere. - Decide the restore rule before you need it, because the value will have been reused.
- Watch
n_dead_tupon soft-deleted tables, and plan the purge. - Re-evaluate whether the requirement is retention or convenience, because the archive table satisfies the first without the cost of the second.
Failure stories worth testing
Register, delete, then register the same email again
The canonical repro. It fails on a table with a plain unique constraint, and it succeeds on one with a partial unique index, and the difference is one line of DDL.
Try to make the composite constraint work
ALTER TABLE users ADD UNIQUE (email, deleted_at), then insert two live rows with the same email. Both succeed, because nulls are distinct, and the guarantee you thought you had added is not there.
Restore a soft-deleted user after the email has been reused
Reproduce it directly. You get a unique violation on the restore with no obvious correct resolution, which is exactly the incident you want to have rehearsed.
Remove the global filter and enumerate what leaks
Take a query that returns users, remove the filter, and count what changes. In a real system this surfaces anything the filter was silently protecting, including reports and admin screens.
Pass the deletion flag as a parameter and read the plan
The plan stops using the partial index. It is a small change with a large performance consequence and no error message to tell you.
Common mistakes
| Mistake | What actually happens | Better decision |
|---|---|---|
UNIQUE (email) on a soft-deleted table |
Re-registration fails on the first attempt | Partial unique index over live rows |
UNIQUE (email, deleted_at) |
Nulls are distinct, so live rows are unguarded | Partial index, or NULLS NOT DISTINCT on PG15+ |
| Overwriting the value with a tombstone suffix | The row becomes unrestorable and unsearchable | Do not mutate the identifier |
| Relying only on the application check | The guarantee is in the database, not the code | Express it in the schema |
| Believing the filter makes the flag unnecessary | A query without it returns deleted rows | Partial indexes plus an audited read path |
| Passing the flag as a parameter | The planner cannot use the partial index | Literal predicate, or separate query paths |
| Assuming a global filter covers navigation loads | A deleted principal can still materialise | Verify with an explicit test |
Allowing IgnoreQueryFilters anywhere |
The bypass becomes a debugging shortcut | Named methods for the rare cases |
| Treating soft delete as retention | Nothing is purged and indexes grow forever | Archive table, or a hard delete |
| Ignoring restore conflicts | The restore fails after the value was reused | Decide the rule in advance |
| Assuming autovacuum will keep up | Dead tuples accumulate from every soft delete | Monitor n_dead_tup and purge |
The complete story in one minute
A soft delete adds a nullable timestamp and a filter, and it introduces a bug that fires the first time somebody re-registers an email that was ever deleted. The cause is not subtle once stated: a soft-deleted row is still a row and still occupies its unique value, so a plain UNIQUE (email) constrains all rows including the ones the application believes are gone. The application check passes, because the application filters deleted rows, and the database rejects the insert, because the database does not. The fix is a partial unique index over live rows, which states the intent once in the schema and is enforced for every write path including imports and migrations.
The obvious workaround is the wrong one. Adding the nullable deletion timestamp to an ordinary unique constraint leaves live rows unguarded because nulls are distinct by default. PostgreSQL 15’s NULLS NOT DISTINCT protects the live rows but also compares deletion timestamps, which is not the policy being modeled. Prefer a partial unique index in PostgreSQL, a filtered unique index in SQL Server, or a generated/functional expression in MySQL.
The rest follows from the same boundary. The live-row predicate has to reach every read. EF Core query filters apply to included entities too, but required navigations can turn that filter into an inner join that removes parent rows; test the generated SQL and result cardinality. Keep IgnoreQueryFilters behind a named, authorized path. Restore is not the inverse of delete because the key may have been reused, so conflict handling is a product rule. And if the reason for retention is audit, compare tombstones with an immutable audit stream or archive table; a nullable timestamp is not automatically the cheapest or safest evidence model.
Technical references
Related notes.
JSONB: Winning the Schema Argument by Deferring It
A JSONB column lets you add an attribute without a migration, which is a real win. The mistake is treating that freedom as a licence to put everything in it, and the mature answer is a hybrid.
Isolation Levels: The Table That Does Not Describe Your Database
Why the ANSI isolation table describes symptoms rather than mechanisms, what MVCC changed, and how snapshot isolation still lets two correct transactions corrupt each other.
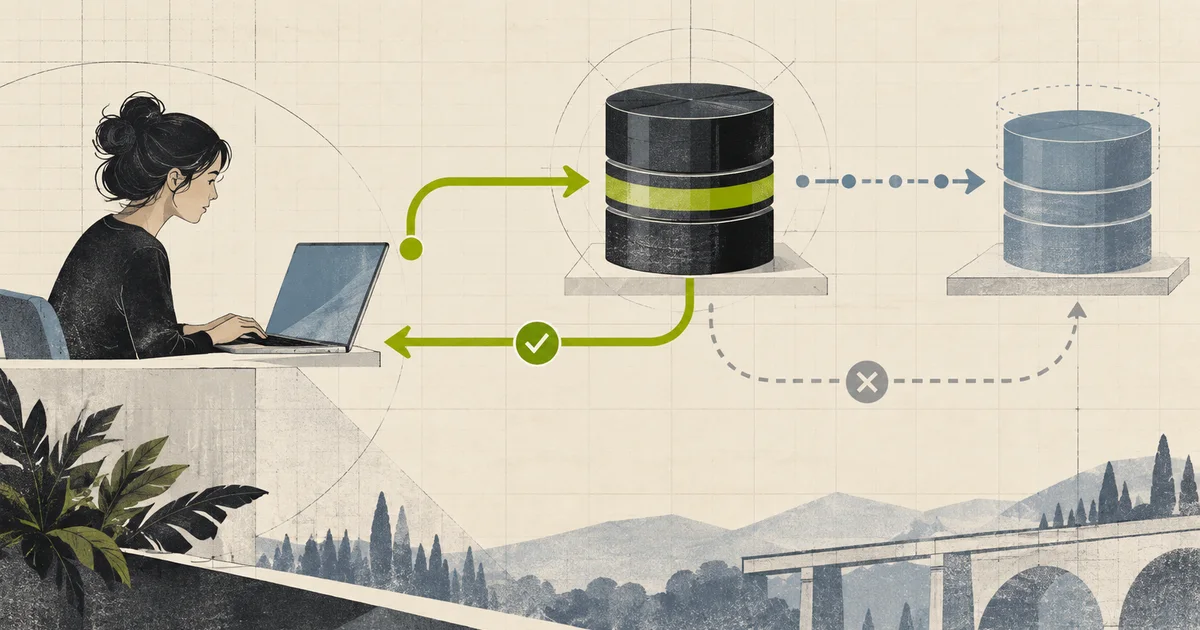
Read Replicas: The Right Answer, the Wrong Moment, and How to Keep Users From Seeing It
Asynchronous replication separates primary commit, standby receipt, durable flush, and replay. Read-your-writes depends on replay; failover loss depends on what reached the promoted standby.