Read Replicas: The Right Answer, the Wrong Moment, and How to Keep Users From Seeing It
Asynchronous replication separates primary commit, standby receipt, durable flush, and replay. Read-your-writes depends on replay; failover loss depends on what reached the promoted standby.
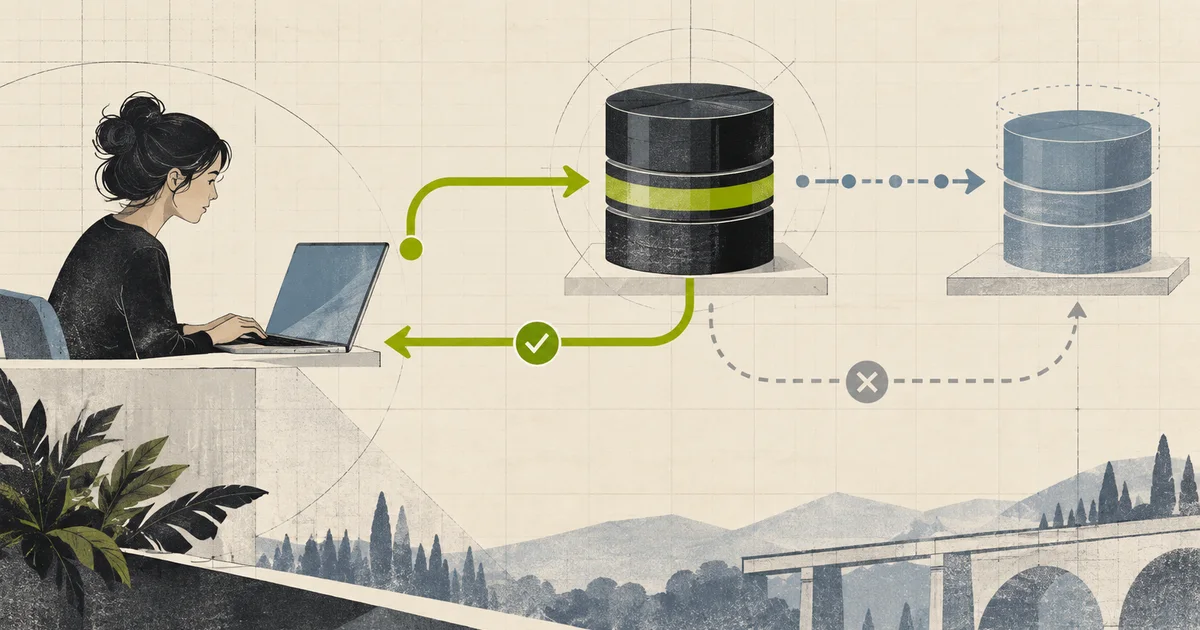
Read replicas are one of the easiest pieces of infrastructure to justify and one of the easiest to deploy in a way that produces a support ticket within a week. The ticket is always a variation on the same complaint: the user saved something, the page says it did not save, and after a refresh the change is there.
Nothing is broken. The write is durable on the primary and the read went somewhere that had not caught up yet, and the gap between those two facts is the whole problem.
It is worth being precise that “durable” is doing two jobs in that sentence. Durability on the primary is fsync, group commit, and durability. Visibility on the replica is a replication-ordering property, and the same arithmetic that makes a stale read dangerous in a single transaction makes it harmless across two connections, which is the distinction isolation levels and write skew is really about. Finally, the fix is often to pin reads to the primary, and that consumes primary capacity, so it lands directly in connection pool sizing.
Asynchronous is the default, and the tradeoff is lag
  primary                                    replica
  --------                                    -------
  COMMIT at 10:00:00.000  ->  WAL shipped    applied at 10:00:00.045
  client returns                              reads now see the write

  the gap is 45 ms, and it is not constant
The alternative is to make the primary wait.
  synchronous_commit = on

  COMMIT
    -> WAL shipped
    -> standby acknowledges the flush
    -> primary returns

  cost: one network round trip on every write, plus the standby's write
For a system where losing the last few writes on a failover is acceptable, asynchronous is the correct choice and the latency difference is not close. The consequence is that the primary and its replicas are not a single consistent state, and every application decision has to account for that.
The mistake is deploying a replica and then routing reads to it without deciding what consistency each read requires. A replica is a different kind of machine from a primary. It answers a different question.
Measuring it
Two numbers, from two places, and you want both.
On the primary, pg_stat_replication gives you the write, flush, and replay delays that Postgres has been tracking since version 10.
-- on the primary
SELECT application_name,
       state,
       sync_state,
       sent_lsn,
       write_lag,
       flush_lag,
       replay_lag,
       pg_size_pretty(pg_wal_lsn_diff(pg_current_wal_lsn(), replay_lsn)) AS bytes_behind
FROM pg_stat_replication;
flush_lag is how far behind the standby’s durable write is, and it is the number that predicts whether a failover loses data. replay_lag is how far behind it is in terms of being queryable, and it is the number that predicts whether a read will see a write.
-- on the replica
SELECT now() - pg_last_xact_replay_timestamp() AS replay_delay;
This one has a failure mode worth knowing. It measures from the last transaction’s commit timestamp, so if the replica is idle, or the workload is so light that nothing has been applied recently, the number is old and large while the replica is in fact fully caught up on everything that matters. It is a useful signal and an unreliable absolute value. A more honest measure of how much un-applied data there is comes from the LSN comparison above.
The metric to alert on is bytes_behind on the primary, because it is measured on the machine that knows what has been written, and because a byte count does not go stale when the workload is quiet. Alert on a threshold that is generous for normal operation and tight enough to catch a stuck slot, rather than on a mean.
The other diagnostic is the replication slot, and it is the one that turns a lag spike into an outage.
-- on the primary
SELECT slot_name, active, restart_lsn, wal_status,
       pg_size_pretty(
         pg_wal_lsn_diff(pg_current_wal_lsn(), restart_lsn)) AS retained
FROM pg_replication_slots;
A slot that is active = false retains WAL indefinitely, and the primary will not remove WAL it might still need. That disk fills, and it fills on the primary, which is the machine you least want to have a disk problem on.
The anomaly users report first
Read-your-writes is the consistency guarantee most applications assume and never check.
  t=0  PUT /profile    -> primary, committed
  t=1  GET /profile    -> replica, 80 ms behind
  t=2  client shows the old name
  t=3  user reports that saving does not work
The same failure appears in forms that are harder to diagnose, because the entity involved is not what the user just changed.
  cart          write the cart, read the cart        -> visibly wrong
  order status  write the order, read the order      -> visibly wrong
  permissions   write the role change,
               read your own permissions on a new request
                                                   -> the user is locked out
  upload         write the metadata,
                read it back to get an id            -> a spurious not-found
The pattern to notice is that the write and the read are in different HTTP requests, often on different instances, often hitting a different connection. Making them consistent requires a decision that crosses the request boundary, and that is where most implementations fall short.
What to do about it
The fix that is worth having is a routing decision, not a query trick. Reads that must see a given session’s own writes go to the primary; everything else goes to a replica.
public enum ReadPreference
{
    Primary,
    Replica,
}

public sealed class ReadConsistency
{
    private DateTimeOffset? _pinnedUntil;

    public void PinPrimary(TimeSpan window) =>
        _pinnedUntil = DateTimeOffset.UtcNow + window;

    public bool MustUsePrimary =>
        _pinnedUntil is { } until && DateTimeOffset.UtcNow < until;
}
// mark a request that has written something the user will read back
app.Use(async (ctx, next) =>
{
await next();
if (ctx.Request.Method is "POST" or "PUT" or "PATCH" or "DELETE")
{
var consistency = ctx.RequestServices.GetRequiredService<ReadConsistency>();
consistency.PinPrimary(TimeSpan.FromSeconds(5));
}
});And the resolver that honours it.
public sealed class ConnectionResolver
{
    private readonly ReadConsistency _consistency;
    private readonly string _primary;
    private readonly string _replica;

    public ConnectionResolver(ReadConsistency consistency, IConfiguration config)
    {
        _consistency = consistency;
        _primary  = config.GetConnectionString("Primary")!;
        _replica  = config.GetConnectionString("Replica")!;
    }

    public string Resolve(ReadPreference preference) =>
        preference == ReadPreference.Primary || _consistency.MustUsePrimary
            ? _primary
            : _replica;
}
The five-second window is arbitrary, and the important part is that it exists and is bounded. Long enough to cover the round trip and any immediate redirect, short enough that a user who navigates away for a minute gets replica reads again.
Two refinements make it noticeably better.
Be precise about which reads are sensitive. A profile read after a profile write needs the primary. An unrelated catalogue read does not, and pinning it there costs you the capacity the replica was added for. Scoping the pin to the entities a request touched keeps the replica useful.
Make the flag travel with the request, not with the process. A sticky flag on the instance means one user’s write pins every user’s reads on that instance, which defeats the purpose. Scope it to the request, and where the frontend holds a session across requests, carry an explicit token.
// the client echoes back what the write response told it
public sealed record WriteReceipt(string Entity, string Version, DateTimeOffset At);

// GET carries it, the resolver turns it into a routing decision
if (request.Headers.TryGetValue("X-Write-Receipt", out var v) &&
    DateTimeOffset.UtcNow - receipt.At < TimeSpan.FromSeconds(5))
{
    routing.UsePrimary = true;
}
This is more machinery than a five-second pin, and it is the version that survives a service with several instances and a load balancer in front of it.
Synchronous replication, selectively
There is a setting that gives you both properties, and it is meant to be used on a small number of writes rather than on all of them.
-- name the standby that can acknowledge synchronous transactions;
-- keep ordinary transactions local/asynchronous by default
synchronous_standby_names = 'FIRST 1 (user_read_replica)'
synchronous_commit = local

-- a single write that must be visible on a standby before it is acknowledged
BEGIN;
SET LOCAL synchronous_commit = 'remote_apply';
INSERT INTO account_transfers (...) VALUES (...);
COMMIT;
synchronous_commit values
local commit when written locally fastest, may be lost on failover
remote_write when written to the standby's OS no fsync on the standby
on when flushed on the standby durable on the standby
remote_apply when applied on the standby visible on the standbyremote_apply waits until the configured synchronous standby set reports replay of the commit record. If synchronous_standby_names is empty, there is no remote acknowledgement to wait for; changing the session setting alone does not make an asynchronous topology synchronous. The guarantee also applies to the standby or quorum that acknowledged, not indiscriminately to every read replica, so routing must target that set.
The design is usually a split by operation.
  every write            -> asynchronous, fast
  reads                  -> replica

  a small set of writes  -> configured sync standby + remote_apply
  that must be visible
  everywhere immediately
                             -> those reads can use the replica with
                                confidence, and stay fast
This is a useful hybrid when only a measured subset of writes needs the stronger guarantee. It is not strictly better in every system: synchronous-standby failure can block those commits, and the application still has to route the subsequent read to a standby covered by the acknowledgement.
Monotonic reads depend on routing
Physical PostgreSQL recovery replays WAL forward. A single continuously running standby does not apply a later LSN and then undo it to an earlier LSN. The usual monotonic-read failure comes from load-balancing successive requests across standbys at different replay positions—or failing over to a target that is behind the node just read.
  read 1 -> replica A, replay LSN 0/500 -> sees the change
  read 2 -> replica B, replay LSN 0/420 -> does not see the change
The result is that a replica pool is not monotonic unless the router enforces a replay-position floor. Polling “any replica until it appears” can therefore observe the value and then lose it on the next request.
The mitigations are unglamorous. Read your writes from the primary rather than polling a replica for them. Where a monotonic read genuinely matters, pin the read to a specific replica instance for the duration rather than load-balancing between them. And for the case where the value must be monotone across nodes, that is a real design constraint and asynchronous replication does not provide it, which is a case for the synchronous path above.
Visibility lag is not the same as failover loss
PostgreSQL exposes distinct send, write, flush, and replay positions for a reason. Replay lag controls query visibility. A standby may have received and durably flushed WAL that it has not replayed yet; promotion can replay that WAL before opening for writes. Potential failover loss is therefore bounded by what the chosen target has durably received, not simply by its replay timestamp.
  primary crashes at 10:05

    primary   committed and acknowledged a client at 10:04:59
    replica   last replayed at 10:04:41
    replica   last flushed at 10:04:58
              -> reads can be 18 seconds stale;
                 potential loss is closer to the unflushed gap

    a client that was told "saved" and whose change is now missing
Those are different numbers. Monitor byte/LSN gaps for send, flush, and replay, and define promotion policy around the target’s flush position. A managed service may add storage-level replication and its own recovery guarantees, so its documented RPO takes precedence over a guess derived from replay delay.
A managed service will state a maximum failover data loss, often measured in seconds or in WAL bytes, and it is worth finding that figure rather than inferring one. The levers that change it are the number of replicas and the synchronous configuration, and the levers that change the user-visible lag are almost entirely unrelated: network, storage, hot_standby_feedback, and the workload on the replica.
Hot standby feedback trades cancellations for bloat
Recovery sometimes needs to remove row versions that a standby query still expects. Without feedback, PostgreSQL resolves that conflict by waiting up to the standby delay and then cancelling the query so replay can proceed.
hot_standby_feedback = onWith feedback, the standby reports an old snapshot horizon and the primary delays vacuum removal of relevant dead rows. That can reduce recovery conflicts, but it can bloat tables and indexes on the primary. It does not itself retain WAL. A lagging or inactive replication slot can retain WAL and fill pg_wal; max_slot_wal_keep_size is the guardrail for that separate failure.
-- on the replica, the queries that hold a snapshot open
SELECT pid, state, now() - xact_start AS age, left(query, 120)
FROM pg_stat_activity
WHERE backend_type = 'client backend' AND xact_start IS NOT NULL
ORDER BY age DESC
LIMIT 10;
And the discipline that goes with it: replicas serve read traffic, and a reporting workload belongs on a reporting replica rather than on the one serving your users.
Failover
A failover is a promotion, and promotion is the point at which a replica stops being allowed to lag.
-- on the replica being promoted
SELECT pg_promote(true, 60);

-- confirm
SELECT pg_is_in_recovery();
Promotion is only half the procedure. Fence the old primary before accepting writes on the new one. If their timelines diverged, primary_conninfo does not repair the old data directory automatically: run pg_rewind against the stopped old primary when its prerequisites are satisfied, or take a new base backup. Only then configure it as a standby of the new primary.
# old primary is fenced and stopped
pg_rewind --target-pgdata=/var/lib/postgresql/data \
          --source-server='host=new-primary.internal dbname=postgres user=rewind'

# configure standby.signal + primary_conninfo, then start it as a standby.
# Do not run pg_ctl promote on the old primary: that would recreate split brain.
Two things are worth doing before you need any of it. Run a failover rehearsal on a schedule, because a promotion that has never been performed is a procedure rather than a capability. And rehearse the application side too, because the app is usually the part that fails: connection strings that resolve to a hostname that has not changed, caches that hold data from the old primary, and retry policies that turn a failover into a storm of writes against a node that is still coming up.
A production-ready architecture
        write
          |
          v
  +---------------------------------------+
  | does this write need to be visible   |
  | on a replica before it is acked?     |
  +---------------------------------------+
     | no                        | yes
     v                           v
  local/asynchronous ack     configured synchronous set
  (ordinary writes)          + SET LOCAL ... remote_apply
     |                           |
     v                           v
  +--------------------------------------------------+
  | reads                                            |
  |   same request as a write      -> primary       |
  |   within the session's window  -> primary       |
  |   everything else              -> replica       |
  |                                                 |
  | alerts: bytes_behind, slot active,              |
  |         long snapshots on the replica           |
  | feedback choice -> cancellations or bloat       |
  | reporting workload -> a reporting replica       |
  +--------------------------------------------------+
A delivery checklist:
- Export
bytes_behindfrompg_stat_replicationand alert on it. Do not alert on the replica’s replay timestamp alone, it goes stale when idle. - Alert on
pg_replication_slotswhereactive = false. That is disk filling on the primary. - Never read from a replica in the same request that wrote the entity.
- Scope the read-your-writes pin to the request, not to the process, or one user’s write pins every user’s reads on that instance.
- Prefer an explicit receipt token from the write response over a fixed time window where the client can be told when the guarantee has expired.
- Use
remote_applyonly with a configured synchronous standby set, and route the dependent read to a member whose acknowledgement covered that commit. - Decide
hot_standby_feedbackfrom the cancellation-versus-bloat trade-off; it is not a WAL-retention switch. - Cap
statement_timeouton the replica so a reporting query cannot hold a snapshot open indefinitely. - Find your managed service’s stated maximum failover data loss and write it next to your RTO, because it is a real number with a real consequence.
- Rehearse the failover, including the application, on a schedule.
Failure stories worth testing
Write then read from the replica, in a loop, and record what you see
Vary the delay between them from zero upwards. You will find a threshold where it starts working, and that threshold is your measured lag, which is a more useful number than an average from a metrics dashboard.
Run a twenty-minute report on the replica and watch the primary’s disk
With feedback on, watch dead tuples and relation growth on the primary. With it off, watch the report get cancelled by a recovery conflict. Separately pause a slot consumer to rehearse WAL retention; combining these tests hides which mechanism owns which disk growth.
Promote a replica and write to the old primary, then observe the divergence
This is the split-brain test, and it is the one that reveals whether pg_rewind is configured or merely available. Run it before you need it.
Disable a replication slot and watch the primary’s disk usage
The slot stays, the WAL stays, the disk fills. It is the quietest way to lose a primary and the one most teams have never tested.
Send a burst of writes during a failover and measure how long the retries take
The application retry policy is what turns a fifteen-second failover into a five-minute incident. This is the test that finds it.
Common mistakes
| Mistake | What actually happens | Better decision |
|---|---|---|
| Routing all reads to a replica immediately | Read-your-writes breaks on every write-then-read | Pin the sensitive reads to the primary |
| Pinning the primary per process rather than per request | One user’s write pins every user’s reads on that instance | Scope the pin to the request or to a receipt token |
| Polling a load-balanced replica pool until the value appears | The next request can hit a less-replayed standby | Pin to primary or enforce an LSN floor |
Setting remote_apply with no synchronous standby |
There is no remote acknowledgement to wait for | Configure the sync set and route to it |
Alerting on pg_last_xact_replay_timestamp |
Goes stale when idle and reports false lag | Alert on bytes_behind from the primary |
| Ignoring replication slots | An inactive slot retains WAL until the primary’s disk is full | Alert on active = false |
| Treating feedback as WAL retention | It delays vacuum cleanup and can bloat relations | Monitor bloat; monitor slots for WAL retention |
| Equating replay lag with data loss | Flushed-but-unreplayed WAL can survive promotion | Track send/write/flush/replay separately |
| Rehearsing promotion but not the application | Connection strings and caches fail, not Postgres | Rehearse the whole failover |
| Assuming a replica is a backup | It holds the same data as the primary | Backups and PITR are a separate system |
| Treating lag as a fixed number | It varies with load, storage, and long reads | Alert on a threshold, re-measure under load |
The complete story in one minute
A read replica is the right answer for read scale, for analytics isolation, and for a faster recovery target. The price of the default is that replication is asynchronous, which means a committed write is not yet a visible write anywhere else, and the gap varies with load rather than being a constant you can design around. Every application decision has to account for that, and the decision to make is which reads require which guarantee.
The failure users report is read-your-writes: they save a setting, the page lands on a standby that has not replayed the commit, and the change appears to have failed. Pin that dependent read to the primary, or carry a receipt containing a WAL position and route only to a standby that has reached it. A single standby replays physical WAL forward; the “value appeared and disappeared” failure normally comes from routing successive reads across standbys at different replay positions.
If the guarantee must cross nodes, configure a synchronous standby set and use remote_apply selectively. The setting guarantees replay on the acknowledging set, not all replicas, and those commits can block when the set is unavailable. Keep visibility and durability measurements separate: replay position explains stale reads; flush position and the managed service’s documented RPO explain failover loss. Finally, do not merge two PostgreSQL mechanisms into one story. hot_standby_feedback trades standby-query cancellations for primary bloat by delaying vacuum cleanup. Replication slots retain WAL and need their own byte limit and alert. That separation is what makes the incident diagnosable.
Technical references
Related notes.
OFFSET Pagination: The Query That Gets Slower the Deeper You Scroll
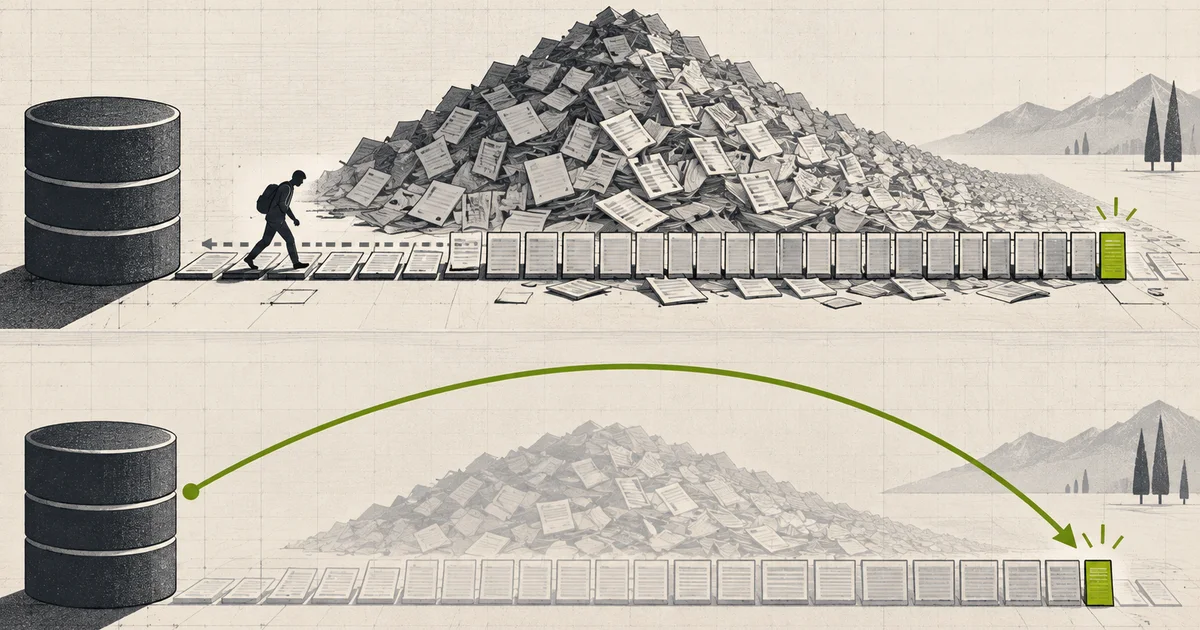
OFFSET makes the executor process and discard rows before the page, so deep pages grow linearly even with an index. Keyset pagination bounds that work, and a unique tiebreaker makes the cursor unambiguous.
Soft Deletes: Why a Unique Constraint Cannot Span a Column You Can Change
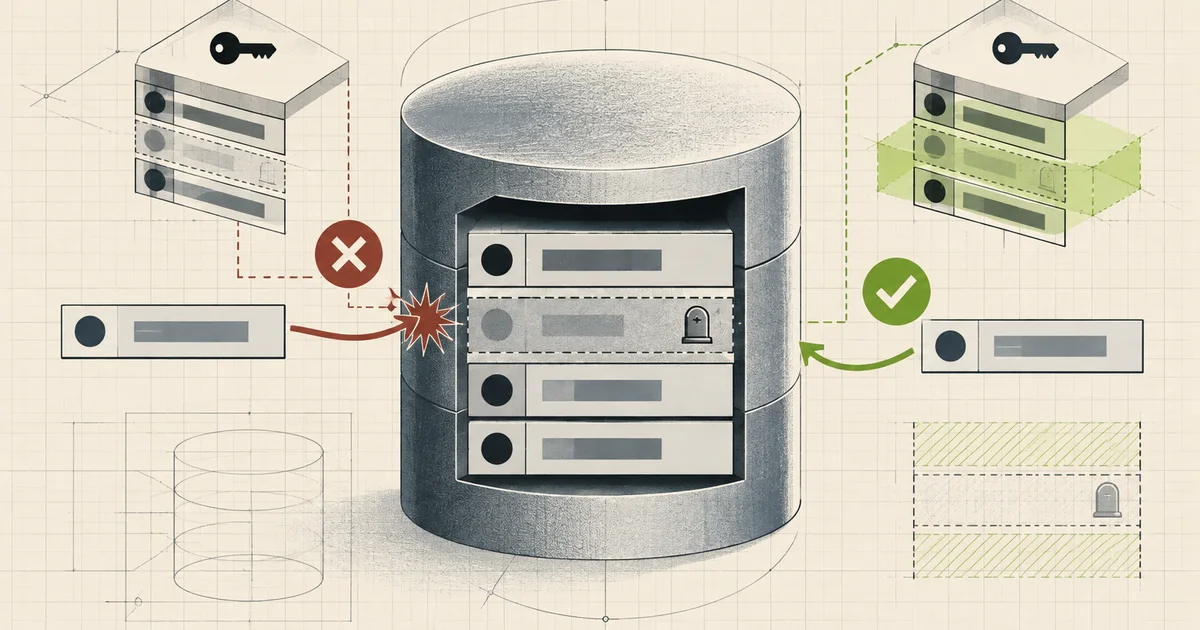
A soft-deleted row still holds its unique value, so the second registration of the same email fails on a constraint nobody expected to fire. The fix is a partial index, and the decision about whether to use one is upstream of that.
Connection Pool Sizing: Little's Law, max_connections, and the Multiplication Nobody Budgeted
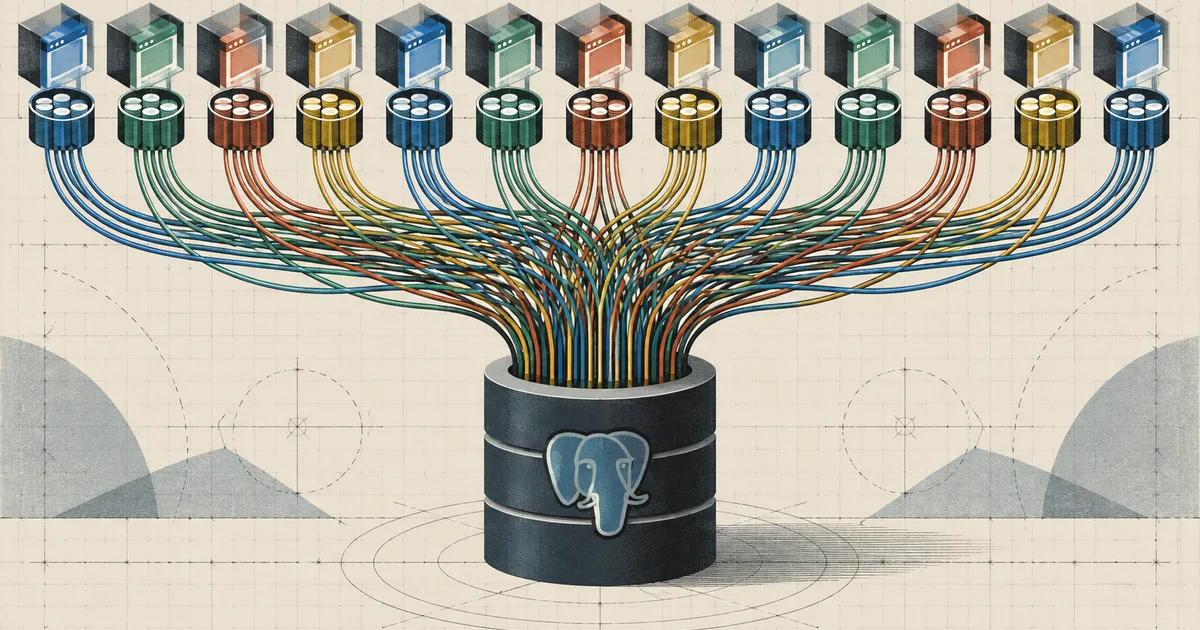
How many database connections you actually need is arithmetic, not intuition, and the real risk is that your pod count multiplies a per-instance default into more connections than Postgres has.