Connection Pool Sizing: Little's Law, max_connections, and the Multiplication Nobody Budgeted
How many database connections you actually need is arithmetic, not intuition, and the real risk is that your pod count multiplies a per-instance default into more connections than Postgres has.
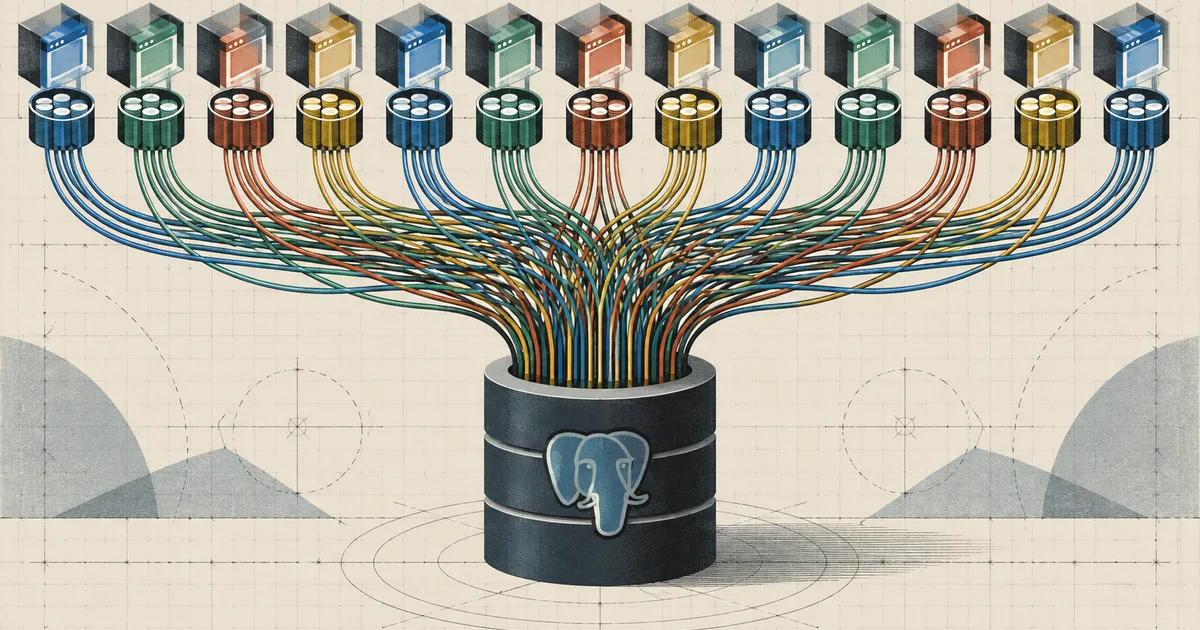
Connection pool sizing gets settled by intuition, and intuition is reliably wrong in both directions. Teams either give the application so much room that the database becomes the bottleneck it was supposed to support, or they cap it low and spend a quarter of a quarter investigating timeouts that turned out to be a queue in their own code.
The number is arithmetic. The arithmetic is one line long.
What W actually is depends entirely on how you use the connection, and two patterns that look identical in a code review produce very different numbers. A lazy-loading query issues one round trip per parent row, so the pool is sized around a query count nobody budgeted for: EF Core and the N+1 query problem. Work you batch into a single statement is the opposite case, where a fixed small pool can be the entire system: batching round trips.
The law
Little’s Law, in its database-flavored form, says that the number of connections in use at any moment equals the rate at which work arrives multiplied by the time each unit of work takes.
  L = λ × W

  L  = connections in flight
  λ  = queries (or requests) per second
  W  = time each one holds a connection, in seconds
The reason this is useful is that it turns an open question into a measurement. You do not decide how many connections you should have, you measure throughput and hold time and let the multiplication tell you.
  1,200 requests/sec, connection held for 8ms

    W = 0.008 s
    L = 1200 × 0.008 = 9.6

    so about 10 concurrent connections, and 20 for headroom
Eight. Not a hundred, not fifty, not the max_connections value you copied into the connection string.
The number surprises people because intuition treats a connection as expensive, when what is actually expensive is time spent holding one. A connection that sits idle in the pool costs nearly nothing. A connection held during a slow query costs everything it touches. So the way to reduce the number you need is to reduce the time you hold them, which means fewer round trips and shorter queries rather than a smaller application.
The rule of thumb, and its condition
The widely repeated guidance is that you want roughly a small multiple of the core count, often expressed as a fraction of max_connections. That is directionally right and frequently quoted without the part that makes it true.
The reasoning is that a connection is a process, and a process spends most of its time waiting rather than computing. Past a certain point, adding processes adds contention on shared buffers and lock tables without adding throughput, and the database gets slower rather than faster.
  CPU-bound work scales roughly with cores, up to a point

    cores 8, 20 connections   -> most are waiting, the 8 that run get the CPU
    cores 8, 800 connections  -> 800 processes, lock contention on shared
                                 buffers, context switching, slower overall
But the rule assumes your workload is holding a connection while the database does work. If your application holds a connection across a call to a payment provider, then the required concurrency is determined by how long that external call takes, and the core count is irrelevant to it.
  W is made of:

    database time     (scales with cores)
    network round trips
    application time spent while holding the connection
      <- this is the part that surprises people
That last line is why the formula and the core-count rule can disagree. Both are right, because they are answering different questions. The formula tells you what you need given your current hold time. The core count tells you the ceiling past which the database cannot benefit from more concurrency. If your first number is above the second, the answer is to reduce hold time, not to raise the ceiling.
What each connection actually costs
A Postgres connection is an operating system process, and it carries per-connection memory that scales with the largest sort or hash it might perform.
  per connection
    process stack and locals
    work_mem for each sort or hash node, at execution time
    a slot in shared buffer lookup structures
    locks on the lock table when taking any relation lock
work_mem is the item that surprises people, because it is per node rather than per query. A query with two hash aggregates can use work_mem twice. With work_mem at 8MB and 200 connections each doing two, the ceiling on sort and hash memory is over 3GB, and none of it is visible in a table of configuration values.
SHOW work_mem;                          -- per node, not per query
SELECT count(*), state FROM pg_stat_activity
GROUP BY state;

-- the number that should stay well below max_connections
SELECT count(*) FROM pg_stat_activity;
The consequence of too many connections is not primarily an out-of-memory failure. It is a latency problem, because shared buffer lookup and lock table contention get worse as the process count rises, and rising latency means connections are held longer, which means more connections are needed. The system becomes self-reinforcing in the wrong direction, and the intuitive response, raising the pool limit, accelerates it.
  the feedback loop to avoid

    more connections
      -> contention, slower queries
        -> longer hold time
          -> the application needs more connections
            -> more connections
The multiplication nobody budgeted
This is the part that shows up in every .NET deployment, and it is a configuration default rather than a mistake anyone made.
Npgsql’s default maximum pool size is 100 connections, per process.
  pods   x  max pool size   =  maximum potential physical connections

     1   x  100             =  100
     5   x  100             =  500
    20   x  100             =  2,000
    50   x  100             =  5,000
Twenty pods do not open two thousand connections merely by starting: Npgsql pools grow on demand and the default minimum is zero. But under coincident load, the fleet is permitted to attempt that many physical sessions. A ceiling above the database budget removes the protection exactly when the service scales out.
The fix is a deliberate cap in the connection string and a multiplication in your capacity planning.
var connectionString = builder.Configuration.GetConnectionString("Default");

var poolSize = builder.Configuration.GetValue("Database:MaxPoolSize", 10);

connectionString = new NpgsqlConnectionStringBuilder(connectionString)
{
    MaximumPoolSize  = poolSize,
    MinimumPoolSize  = Math.Min(2, poolSize),
    Timeout          = 5,
    CommandTimeout   = 30,
    KeepAlive        = 30,
    NoResetOnClose   = false,
}.ConnectionString;

builder.Services.AddDbContext<AppDbContext>(options =>
    options.UseNpgsql(connectionString, npgsql =>
        npgsql.EnableRetryOnFailure(3, TimeSpan.FromSeconds(5), null)));
And then the constraint that makes it a plan rather than a preference.
  sum of every workload's pool ceilings < application connection budget

     API:       5 pods x 10 = 50
     workers:   3 pods x  5 = 15
     migrations + admin reserve = 10
     planned ceiling = 75
There is no universal sixty-percent rule. Build an explicit budget for every application role, pooling proxy, migration job, monitoring session, replication/maintenance need, and PostgreSQL’s reserved connection slots. Sizing application pools to the server limit means the first diagnostic or recovery connection can be refused during an incident.
An NpgsqlDataSource registered as a singleton is worth considering over the per-context default, because it makes the pool configuration explicit in one place rather than inherited from a connection string that is read by several code paths.
builder.Services.AddSingleton(sp =>
{
    var cs = sp.GetRequiredService<IConfiguration>().GetConnectionString("Default")!;

    return NpgsqlDataSource.Create(new NpgsqlConnectionStringBuilder(cs)
    {
        MaximumPoolSize = 10,
        ApplicationName = "orders-api",
    });
});

builder.Services.AddDbContext<AppDbContext>((sp, options) =>
    options.UseNpgsql(sp.GetRequiredService<NpgsqlDataSource>()));
Exhaustion looks like a database problem
When the pool runs dry, the symptom is a client-side exception with a timeout message, and there is nothing in the database to find.
  Npgsql.NpgsqlException: Failed to open a connection
  Timeout expired.  The timeout period elapsed prior to obtaining
  a connection from the pool.
That exception is thrown by the client while waiting for a free connection. No query was sent. There is no slow query to EXPLAIN, no entry in pg_stat_activity for the request that failed, and no lock to inspect. An investigation that starts in the database finds a healthy database, because the database is healthy; it simply is not being asked to do anything.
The two failure modes are distinguishable from the database side, and the distinction saves a lot of time.
  client waiting for a pool slot
    pg_stat_activity: no new row
    pool: exhausted, wait time climbing
    application: connections in use == pool size

  client waiting for a lock on a real connection
    pg_stat_activity: row with wait_event_type = 'Lock'
    pool: slots returned slowly and may also become exhausted
    application: correlate pool wait with database wait events
The first is a capacity or a leak. The second is a query or a transaction problem, and it is the one that gets misdiagnosed as the first far too often.
Leak is the other common cause, and in a pooled client it usually looks like code that opens a connection and returns it too late, or a DbContext held longer than the request, or an exception path that skips the return.
// fine: the context is disposed, so the connection goes back to the pool
public async Task<Account> GetAsync(Guid id, CancellationToken ct)
{
    await using var db = _contextFactory.CreateDbContext();
    return await db.Accounts.FirstOrDefaultAsync(a => a.Id == id, ct)
        ?? throw new NotFoundException();
}

// wrong: one mutable context shared for the lifetime of a singleton
public class BadRepository
{
    private readonly AppDbContext _db;   // shared across threads, tracker grows
    public BadRepository(AppDbContext db) => _db = db;
}
A DbContext is not thread-safe and is not a connection pool. It is a per-unit-of-work change tracker that normally opens a provider connection for an operation and returns it afterward. A singleton context does not necessarily pin one physical connection forever, but it does share mutable tracking state across requests, permits unsafe concurrent use, and can retain an unbounded graph. The scoped unit-of-work boundary is still the fix; connection lifetime should be measured independently.
Proxies, and prepared statements
Pooling proxies sit in front of Postgres to keep a fleet of application instances from multiplying connections, and they are the right answer to the capacity problem above. The one thing to know before you insert one is what pooling mode means for the protocol.
In transaction pooling, a server connection is handed to one client transaction at a time, then returned. Most session-level state is therefore unsafe across the handback. Protocol-level prepared plans are a special, versioned case in current PgBouncer rather than a reason to declare all prepared statements broken.
  session pooling
    one server connection per client connection for its lifetime
    prepared statements, temp tables, session variables all survive
    connection count tracks client count

  transaction pooling
    a server connection is reused for whichever transaction is next
    most session state is not yours afterwards
    connection count can be far below client count
Npgsql automatic preparation is disabled by default (Max Auto Prepare = 0), and EF Core does not by itself mean every repeated query is prepared. If the application explicitly prepares commands or enables automatic preparation, PgBouncer 1.21 and later can track protocol-level prepared plans in transaction mode when max_prepared_statements is nonzero.
; PgBouncer 1.21 and later, transaction mode
[pgbouncer]
pool_mode = transaction
max_prepared_statements = 100

[databases]
orders = host=postgres.internal port=5432 dbname=orders
Host=pgbouncer.internal;Database=orders;
Maximum Pool Size=20;Max Auto Prepare=100;Auto Prepare Min Usages=5Those two 100 values control different resources and do not have to match: Npgsql’s value caps its per-physical-connection auto-prepared working set, while PgBouncer’s caps tracked prepared plans per client connection. If PgBouncer cannot track plans, leave Npgsql auto-prepare disabled and do not explicitly prepare across transaction pooling. Also review temp tables, LISTEN, session advisory locks, and arbitrary SET state; prepared-plan support does not make transaction pooling behave like session pooling.
It is also worth noting that EnableRetryOnFailure and a connection proxy interact. Retries make the application attempt a new operation after a transient failure, which is exactly right, and it should be enabled deliberately rather than assumed, with a bounded number of attempts and a cap on total elapsed time so a retry loop cannot outlive the request that started it.
A production-ready architecture
  measure
    λ = requests/sec      (from the APM or the load test)
    W = connection hold time in seconds
        |
        v
  L = λ × W  ->  required concurrency
        |
        +-- compare against the per-instance ceiling
        |      (small multiple of cores, as a sanity check)
        |
        +-- if L > ceiling, the answer is to reduce W
                fewer round trips, shorter queries,
                do not hold a connection across an external call
        |
        v
  size the pool
    sum of pool ceilings < documented application budget
    application budget  < max_connections - operational reserve
        |
        v
  +--------------------------------------------------+
  | alert on pool wait time, not only on pool size    |
  | alert on pg_stat_activity count                  |
  | terminate idle in transaction sessions            |
  | set ApplicationName so connections are traceable |
  | enable bounded retry on transient failures       |
  +--------------------------------------------------+
A delivery checklist:
- Measure λ and W under realistic load rather than deriving the pool size from
max_connections. - Set
Maximum Pool Sizeexplicitly in the connection string. The default is per process, not per application. - Multiply the pool size by the maximum pod count and confirm the total fits within about 60% of
max_connections. - Alert on time spent waiting for a pool slot. A full pool is normal; waiting on a full pool is not.
- Register a named
NpgsqlDataSourcewithApplicationNameso connections are attributable to a service. - Never hold a connection across an HTTP call, a message publish, or a file operation. That is the fastest way to multiply your required concurrency by a large factor.
- Enable bounded retry on transient failures, with an attempt cap and a total time cap.
- If you introduce a pooling proxy in transaction mode, configure prepared statement tracking on both sides in the same change.
- Watch
work_memper node as you watch connection count, because memory per connection is a function of the largest sort your queries perform. - Treat pool exhaustion as an application-side incident until
pg_stat_activityshows otherwise, since no query is ever sent.
Failure stories worth testing
Scale to twenty pods, then drive coincident demand
A one-instance load test cannot prove the fleet budget. Pools begin empty, so scaling idle pods alone should not open every allowed connection. Drive enough coincident work to grow each pool and verify the global cap, server reserve, acquisition time, and recovery after demand falls.
Set the pool to one and drive concurrent traffic
The application becomes a serial queue. It is an unreasonably low number, and it is useful for demonstrating the failure mode: latency grows linearly with concurrency while database CPU stays near zero.
Raise the pool to 2,000 against a database with 100 connections
Watch latency rise as connections increase. It is the clearest evidence that the fix for a slow database is not a larger pool, and it is the evidence that convinces a team to reduce hold time instead.
Trigger pool exhaustion deliberately and inspect the database from another session
The request fails with a connection timeout and pg_stat_activity shows no new activity. That absence is the diagnostic, and seeing it once makes it recognisable for the rest of your career.
Put a transaction-mode proxy in front of a connection using prepared statements
Without statement tracking, the application fails or silently loses its prepared statement plan. Testing this before a rollout is far cheaper than testing it during one.
Common mistakes
| Mistake | What actually happens | Better decision |
|---|---|---|
Sizing the pool from max_connections |
Every pod claims the whole database | Pod count times pool size, under 60% |
| Relying on the default pool size | 100 connections per process, multiplied by pods | Set Maximum Pool Size explicitly |
| Treating a connection as expensive | Idle pooled connections are cheap; held time is expensive | Reduce hold time, not pool size |
| Raising the pool when latency rises | Contention raises latency, which raises the demand for connections | Shorten queries and remove external calls from transactions |
| Holding a connection across an HTTP call | W is dominated by someone else’s latency | Commit before calling out |
Keeping a DbContext for the life of a singleton |
A connection is held for the life of the object | Create per unit of work and dispose it |
| Debugging pool exhaustion in the database | No query was sent, so the database has nothing to show | Check pool wait time and in-use counts on the client |
Reading work_mem as a per-query budget |
It applies per sort or hash node, per connection | Multiply by nodes and by connections |
| Adding transaction pooling without a feature audit | Session state such as temp tables, LISTEN, and session locks no longer follows the client |
Check PgBouncer’s feature matrix; configure tracked prepared plans only if used |
| Enabling unlimited retries | A retry loop outlives the request and amplifies load | Cap attempts and total elapsed time |
| Sizing only for one instance | The database sees the fleet, not the pod | Test at maximum scale-out, not at one instance |
The complete story in one minute
The number of busy connections you need starts with arithmetic. Little’s Law says concurrency equals throughput times hold time, so a service doing twelve hundred database-using operations a second with eight milliseconds of connection occupancy averages about ten busy connections. Tail latency, bursts, transactions, background work, and measurement error require explicit headroom. Reducing hold time—fewer round trips and no remote calls inside a transaction—reduces required concurrency. Idle physical connections still consume server processes and resources, so pool ceilings and idle pruning remain part of the budget.
Core-based rules of thumb are experiments, not ceilings derived by law. Each PostgreSQL connection is a backend process, and operations can allocate work_mem per sort or hash node. Past a point, more concurrent work contends for CPU, cache, I/O, and locks; rising latency then increases Little’s-Law concurrency and reinforces saturation. Npgsql defaults to a maximum of one hundred physical connections per pool, so twenty pods have a theoretical ceiling of two thousand even though pools start empty and grow on demand. Set every ceiling explicitly and keep their fleet-wide sum inside a documented server budget with operational reserve.
Pool exhaustion also looks like something it is not. A caller can time out waiting for a client-pool slot before any new query reaches PostgreSQL. The distinction is visible from both sides: pool wait telemetry rises without a corresponding active backend, while a lock wait appears in pg_stat_activity and pg_locks. Alert on acquisition duration and timeout count, not simply “pool full.” If a proxy is added, test the exact PgBouncer version and pooling mode: current versions can track protocol prepared plans when enabled, while most other session state remains incompatible with transaction pooling.
Technical references
- Npgsql connection-string and pool parameters
- Npgsql data sources, connection disposal, and pooling
- PostgreSQL connection limits and reserved slots
- PostgreSQL resource consumption and
work_mem - PgBouncer pooling-mode feature matrix
- PgBouncer prepared-statement FAQ
- EF Core
DbContextlifetime and threading
Related notes.
OFFSET Pagination: The Query That Gets Slower the Deeper You Scroll
OFFSET makes the executor process and discard rows before the page, so deep pages grow linearly even with an index. Keyset pagination bounds that work, and a unique tiebreaker makes the cursor unambiguous.
Batching: Turning a Thousand Round Trips Into One
How to remove database round trips without confusing batching, transactions, preparation, concurrency, and bulk-loading behavior in Npgsql and PostgreSQL.
Read Replicas: The Right Answer, the Wrong Moment, and How to Keep Users From Seeing It
Asynchronous replication separates primary commit, standby receipt, durable flush, and replay. Read-your-writes depends on replay; failover loss depends on what reached the promoted standby.